Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning for Computer Vision
End Term · 31 Aug 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ2 Marks·Choose one option
Why does DETR typically exhibit poor performance in detecting small objects compared to larger ones? Choose the best answer in your opinion.
- AThe CNN backbone used in DETR has a fixed receptive field that’s too large for small objects.
- BThe global self-attention mechanism in DETR tends to dilute the signal from small objects across all image locations.
- CDETR’s loss function actively discards all detections smaller than 50 × 50 pixels.
- DThe object queries in DETR are programmed to ignore any object smaller than 10% of the image size.
- EDETR’s encoder-decoder architecture was specifically designed to only detect objects larger than a cat.
- Q2MCQ2 Marks·Choose one option
Consider the following Pytorch code: 1. x = torch.tensor([[-3.,2.,3.],[4.,-5.,7.],[20.,3.,2.]]) 2. print(torch.mean(x,dim=0,keepdim=True)) The output of the code is:
- Atensor([ 7., 0., 4.])
- Btensor([[ -7., 10., -4.]])
- Ctensor([[ -7.],[7.],[4.]])
- Dtensor([ -7., 7., 3.])
- Etensor([[7., 0., 4.]])
- Ftensor([[ 0.],[7.],[4.]])
- Q3MCQ2 Marks·Choose one option
Which one of the following statements is false?
- ALinear contrast stretching is a point operation.
- BMoving average is an example of a local operation.
- CConvolution in the spatial domain cannot be obtained through addition in the frequency domain.
- DAll of these.
- Q4MCQ2 Marks·Choose one option
What is the correct order of operations for processing an image through a Vision Transformer (ViT)?
- AImage patching → Positional embedding → Linear projection of flattened patches → Transformer encoder→ Classification head
- BImage patching → Linear projection of flattened patches → Positional embedding → Transformer encoder→ Classification head
- CPositional embedding → Image patching → Linear projection of flattened patches → Transformer encoder→ Classification head
- DLinear projection of Images → Image patching → Positional embedding → Transformer encoder → Classification head
- ELinear projection of Images → Image patching → Positional embedding → Transformer encoder → Transformer decoder→ Classification head
- Q5MCQ2 Marks·Choose one option
Vector Quantized Variational Autoencoder (VQ-VAE) utilizes a discrete latent representation as opposed to continuous latent spaces used in traditional VAEs. One of the key components of a VQ- VAE is the codebook, which consists of a set of learnable vectors. What is the primary role of the codebook in VQ-VAE?
- AIt performs the non-linear transformation of the input data to a higher dimensional space.
- BIt regularizes the encoder by penalizing complex encodings.
- CIt provides a finite set of vectors which the encoder’s outputs are mapped to, effectively quantizing the latent space.
- DIt decodes the quantized vectors back into the reconstructed input space.
- Q6MCQ2 Marks·Choose one option
Given two normalized embeddings from CLIP, I = [0.2, 0.5, 0.3, 0.4] for an image and T = [0.1, 0.6, 0.3, 0.7] for a text description, compute the CLIPScore(I,T).
- A− 69%
- B0%
- C69%
- D50%
- Q7MCQ2 Marks·Choose one option
Which one of the following statements regarding hyperparameter tuning is false?
- AValidation set is the best choice for tuning hyperparameters
- BPicking hyperparameters that perform the best on the training set leads to overfitting
- CTuning hyperparameters on the test set is an acceptable approach to find the most powerful model for generalization performance
- DTest set performance, with hyperparameters tuned on the validation set, would be a realistic measure of how the model will generalize to new data.
- Q8MCQ2 Marks·Choose one option
Which one of the following statements is false? (Pick the most appropriate one.)
- AAttention mechanisms can be applied to the bidirectional RNN model
- BAn image captioning network can be trained end-to-end even though we are using 2 different modalities to train the network
- COne of the key components in the vanilla transformer is the recurrent connection that help them to deal with variable input length.
- DAll of these.
- Q9MCQ2 Marks·Choose one option
You are designing an edge detection pipeline for noisy grayscale images. For each of the following goals, choose the most appropriate filter or method: 1. Smooth out noise before any edge detection step 2. Detect edges by finding zero-crossings in the second derivative 3. Highlight regions with a strong intensity gradient 4. Perform basic edge detection with a simple directional gradient filter
- A1 → Gaussian filter, 2 → Laplacian of Gaussian, 3 → First derivative of Gaussian, 4 → Sobel operator
- B1 → Sobel operator, 2 → Gaussian filter, 3 → Laplacian of Gaussian, 4 → First derivative of Gaussian
- C1 → First derivative of Gaussian, 2 → Sobel operator, 3 → Gaussian filter, 4 → Laplacian of Gaussian
- D1→Laplacian of Gaussian, 2→First derivative of Gaussian, 3→Sobel operator, 4→Gaussian filter
- Q10MCQ2 Marks·Choose one option
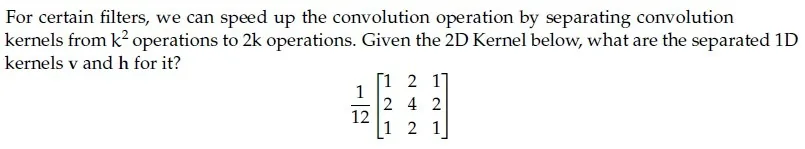
- A
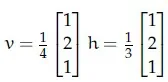
- B
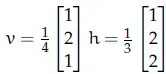
- C
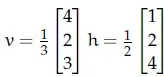
- D
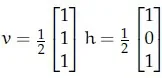
- A
- Q11MCQ2 Marks·Choose one option
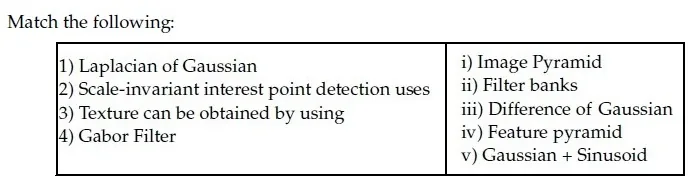
- A1→ iii, 2→ iv, 3→ ii, 4 → i
- B1→ i, 2→ iv, 3 → iii, 4→ ii
- C1→ iv, 2→ iii, 3→ ii, 4 → i
- D1→ iii, 2→ i, 3 → ii, 4 →v
- Q12MCQ2 Marks·Choose one option
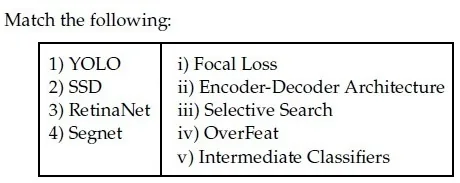
- A1→ iv, 2→ v, 3→ i, 4 → ii
- B1→ iii, 2→ i, 3 → v, 4→ ii
- C1→ iv, 2→ iii, 3→ ii, 4 → i
- D1→ iii, 2→ i, 3 → ii, 4→ v
- Q13MCQ2 Marks·Choose one option
In which one of the following applications would you use a many- to-one RNN architecture? Choose the most appropriate answer.
- AInput is a review of a movie and output is the sentiment of the given review
- BInput is an image and output is the textual description of the given image
- CInput is an image and output is the class to which the given image belongs
- DInput is a sentence in English language and output is the same sentence translated to Hindi language
- Q14MCQ2 Marks·Choose one option
Why might Segment Anything (SAM) be particularly useful in data annotation tasks compared to traditional segmentation models?
- AIt produces perfect segmentation masks.
- BIt can adapt to segment any object, even those not seen during training
- CIt requires less computational resources
- DIt automatically labels all objects in an image without user input
- Q15MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all possible correct options)
- AVariational AutoEncoders (VAE) generate sharper images compared to Generative adversarial networks (GANs)
- BGAN is an example of an implicit density estimation model
- CFully connected layers in mapping network of Style-GAN change the dimension of its input
- DIn a GAN, the generator and discriminator are trained in an alternating fashion, each using the other’s output to improve.
- Q16MSQ2 Marks·Choose all correct options
Classifier-free guidance is a technique used in diffusion models to improve sample quality without the explicit use of a classifier. This technique involves modifying the sampling process based on a control parameter. If the control parameter, denoted as γ, is set to zero, what effect does this have on the generation process?
- AIt fails to generate realistic samples
- BIt removes all guidance, effectively making the process equivalent to the unconditional generation.
- CIt maximizes the influence of the classifier, leading to highly detailed generations.
- DIt can lead to more diverse samples compared to higher values of γ, as the generation process is less constrained by the conditional information.
- Q17MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all possible correct options)
- AAutoencoder are equivalent to Principal Component Analysis (PCA) provided we don’t use of non-linear activation functions
- BWhen using global attention on temporal data, alignment weights are learnt for encoder hidden representations for all time steps
- CPositional encoding is an important component of the trans- former architecture as it conveys information about order in a given sequence
- DIt is not possible to generate different captions for the same image that have similar meaning but different tone/style
- EAutoencoders can not be used for data compression as its input and output dimensions are different
- Q18MSQ2 Marks·Choose all correct options
Which of the following statements about CLIP are TRUE? (Select ALL that apply)
- ACLIP uses a cross-entropy loss function to align text and image embeddings.
- BCLIP requires image labels for training.
- CCLIP is trained to maximize cosine similarity between embeddings of matching text-image pairs.
- DCLIP model is trained with pretext tasks such as rotation prediction and inpainting to learn effective feature representations.
- ETo use the CLIP model for image classification, it is imperative to finetune it on downstream datasets.
- Q19MSQ2 Marks·Choose all correct options
Which one of the following statements is true:
- AWeight change criterion is a method of ‘early stopping’ that checks whether or not the error is dropping over epochs to decide whether to continue training or stop.
- BL1 norm tends to create more sparse weights than L2 norm.
- CDuring the training phase, for each iteration, Dropout ignores a random fraction, p, of nodes, and accounts for it in the test phase by scaling down the activations by a factor of p.
- DA single McCulloch-Pitts neuron is capable of modeling AND, OR, XOR, NOR, and NAND functions.
- Q20MSQ2 Marks·Choose all correct options
Which of the following are examples of a high-pass filter?
- A

- B
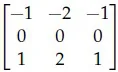
- C
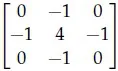
- D

- A
- Q21NAT2 Marks·Write the number
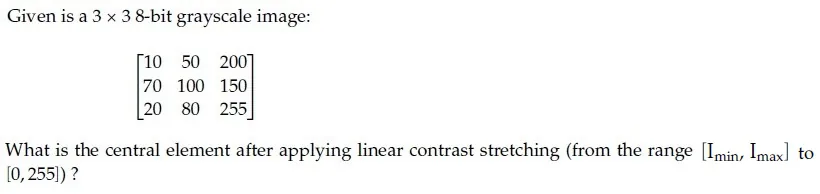 Your answer:
- Q22NAT2 Marks·Write the number
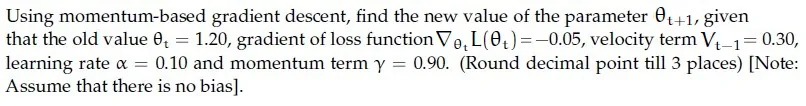 Your answer:
- Q23NAT2 Marks·Write the number
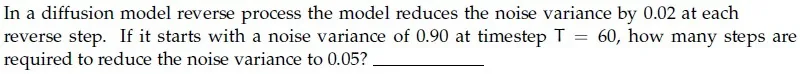 Your answer:
- Q24NAT2 Marks·Write the number
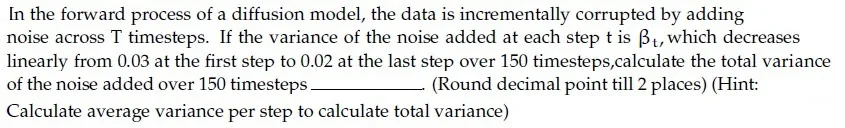 Your answer:
- Q25NAT2 Marks·Write the number
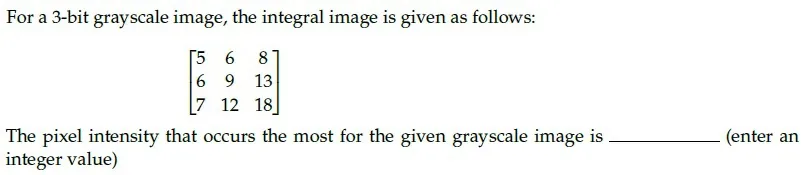 Your answer:
- Q26NAT2 Marks·Write the number
What is the size of the feature map after applying two successive convolution operations with given parameters? Image size = 72×72, Kernel size = 5×5, Padding = 2 and Stride = 3. (In calculation, take floor(x) whenever x is non-integer.If the answer is N × N, write just one value N in the blank) __________________ .
Your answer: Read the passage below, then answer Q27–Q28
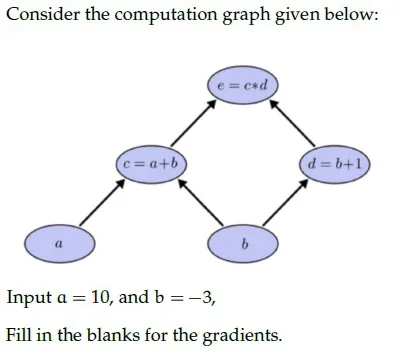
Based on the above data, answer the given subquestions.
Q27NAT1 Mark·Write the number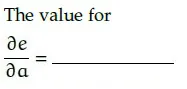 Your answer:
- Q28NAT1 Mark·Write the number
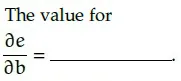 Your answer:
Read the passage below, then answer Q29–Q32
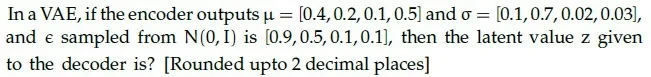
Based on the above data, answer the given subquestions.
Q29NAT2 Marks·Write the numberElement 1:___________
Your answer:- Q30NAT2 Marks·Write the number
Element 2:___________
Your answer: - Q31NAT1 Mark·Write the number
Element 3:___________
Your answer: - Q32NAT1 Mark·Write the number
Element 4:___________
Your answer: Read the passage below, then answer Q33–Q43
Consider the BLIP model architecture with an input (image-text pair) as shown below:
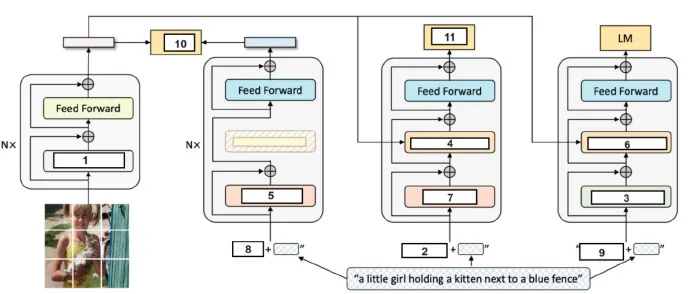
For each of the entities given, enter the appropriate number from the figure that corresponds to it:
Based on the above data, answer the given subquestions.
Q33NAT1 Mark·Write the numberSelf-Attention _______________
Your answer:- Q34NAT0.5 Marks·Write the number
BERT Text Encoder Bi Self Attention:__________________
Your answer: - Q35NAT0.5 Marks·Write the number
Image-Text Matching Loss (LITM ):__________________
Your answer: - Q36NAT0.5 Marks·Write the number
Image Grounded Text Encoder Bi Self Attention: ___________________
Your answer: - Q37NAT0.5 Marks·Write the number
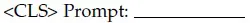 Your answer:
- Q38NAT0.5 Marks·Write the number
Image Grounded Text Encoder Cross Attention: _________________
Your answer: - Q39NAT0.5 Marks·Write the number
Image-Text Contrastive Loss (LITC): ____________
Your answer: - Q40NAT0.5 Marks·Write the number
 Your answer:
- Q41NAT0.5 Marks·Write the number
Causal Self Attention: _____________
Your answer: - Q42NAT0.5 Marks·Write the number
 Your answer:
- Q43NAT0.5 Marks·Write the number
Image Grounded Text Decoder Cross Attention: _____________
Your answer: Read the passage below, then answer Q44–Q49
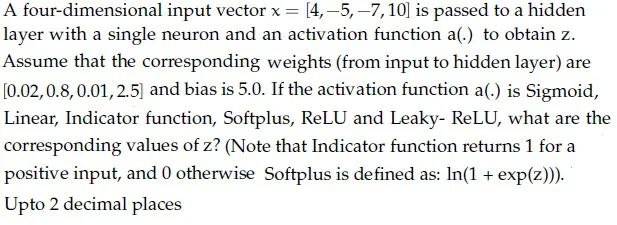
Based on the above data, answer the given subquestions.
Q44NAT1 Mark·Write the numberSigmoid ______________
Your answer:- Q45NAT1 Mark·Write the number
Linear ______________
Your answer: - Q46NAT1 Mark·Write the number
Indicator Function ______________
Your answer: - Q47NAT1 Mark·Write the number
Softplus _____________
Your answer: - Q48NAT1 Mark·Write the number
ReLU _______________
Your answer: - Q49NAT1 Mark·Write the number
Leaky-ReLU _____________
Your answer:
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.