Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Machine Learning Techniques
End Term · 13 Apr 2025 (Forenoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
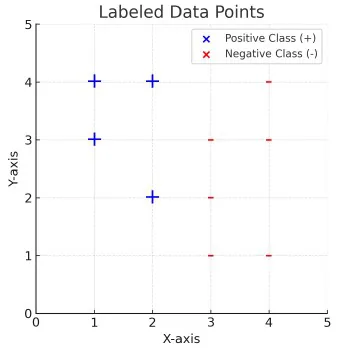
For a given dataset, a 1-Nearest Neighbor (1-NN) and a 3-Nearest Neighbor (3-NN) classifier are applied. Which classifier is likely to exhibit a higher Leave-One-Out Cross Validation (LOOCV) error? In case of tie-breaker, assign a positive class (+) to the data point.
- A1-NN
- B3-NN
- CBoth have the same error.
- Q2MCQ3 Marks·Choose one option
- A
- B
- C
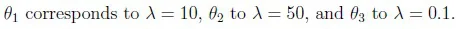
- A
- Q3MCQ4 Marks·Choose one option
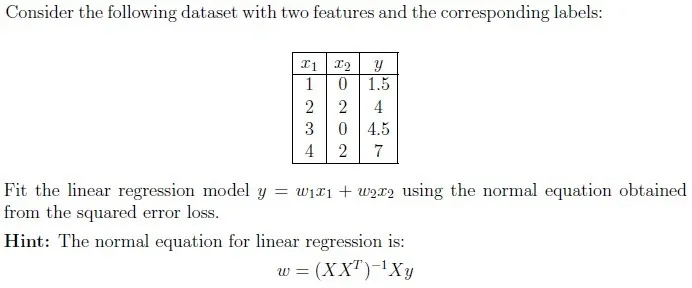
- A
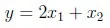
- B
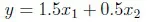
- C
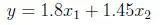
- D
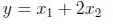
- A
- Q4MCQ4 Marks·Choose one option
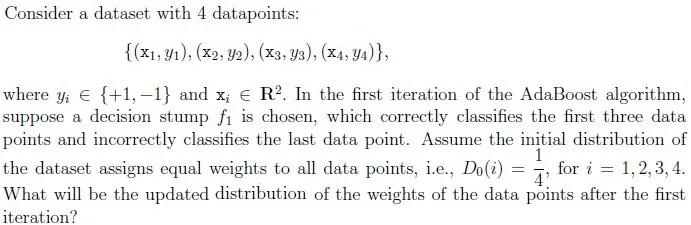
- A
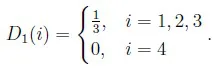
- B
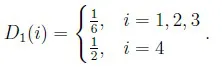
- C
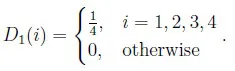
- D
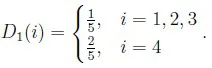
- A
- Q5MSQ3 Marks·Choose all correct options
Which of the following statements correctly differentiates PCA and Kernel PCA?
- APCA maximizes variance in the original feature space, while Kernel PCA maximizes variance in a higher-dimensional transformed space.
- BPCA finds principal components using linear transformations in the original space, while Kernel PCA uses non-linear transformations to find principal components in a higher- dimensional space.
- CKernel PCA can capture non-linear patterns in data, making it useful when PCA fails to represent complex structures in a linear space.
- DPCA and Kernel PCA always yield identical results regardless of the dataset structure.
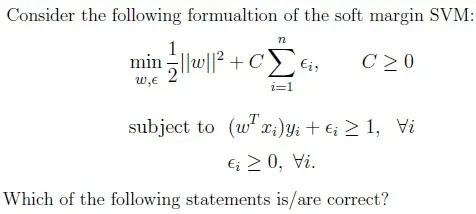
- Q6MSQ3 Marks·Choose all correct options
- A
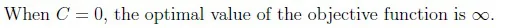
- B
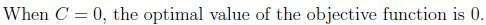
- C
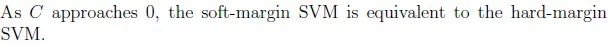
- D
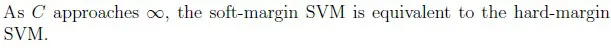
- E
- A
- Q7MSQ2 Marks·Choose all correct options
Which of the following statements are true for bagging?
- AThe final model has lesser variance than the individual learners.
- BThe final model has a higher variance than the individual learners.
- CEstimators in bagging can be trained parallely.
- DIf the number of data points is large, typically two-third of the data points remain unselected in bags.
- Q8MSQ2 Marks·Choose all correct options
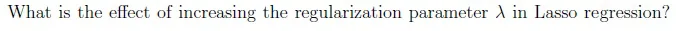
- AIt penalizes large coefficients to reduce overfitting.
- BIt shrinks the coefficients but does not set them to zero.
- CIt forces more coefficients to be exactly zero, performing feature selection.
- DIt has no effect on the regression model.
- Q9NAT2 Marks·Write the number
For a decision tree, each node has exactly two child nodes (balanced tree). If the tree has a depth of 3, how many leaf nodes are there?
Your answer: - Q10NAT3 Marks·Write the number
 Your answer:
- Q11NAT3 Marks·Write the number
 Your answer:
- Q12NAT3 Marks·Write the number
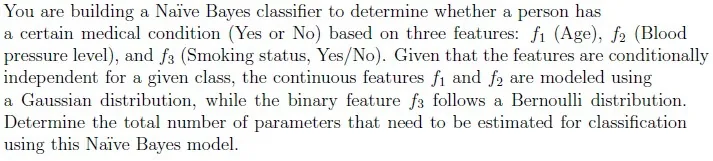 Your answer:
Read the passage below, then answer Q13–Q14
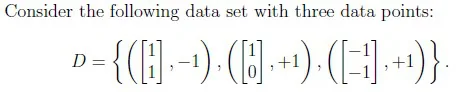
Based on the above data, answer the given subquestions.
Q13NAT3 Marks·Write the number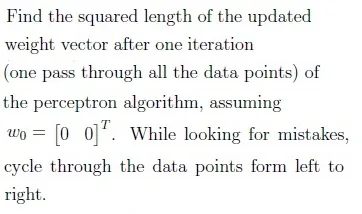 Your answer:
- Q14MCQ2 Marks·Choose one option
Will the algorithm converge after this update?
- AYES
- BNO
Read the passage below, then answer Q15–Q16
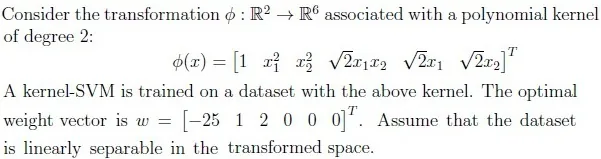
Based on the above data, answer the given subquestions.
Q15MCQ2 Marks·Choose one option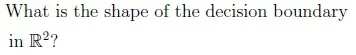
- AIt is a circle.
- BIt is a straight line.
- CIt is an ellipse.
- DIt is a parabola.
- Q16MSQ3 Marks·Choose all correct options
Which of the following training data points are certainly not support vectors?
- A

- B

- C

- D

- A
Read the passage below, then answer Q17–Q18
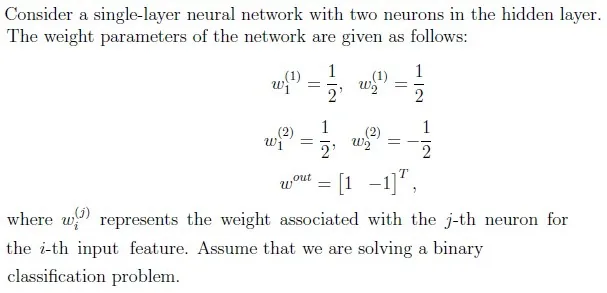
Based on the above data, answer the given subquestions.
Q17NAT3 Marks·Write the number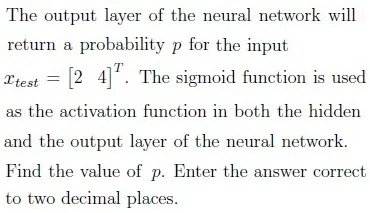 Your answer:
- Q18NAT2 Marks·Write the number
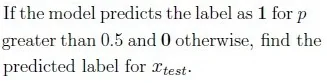 Your answer: