Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Machine Learning Techniques
Most repeated questions
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
Type 1 · asked 4 times · Neural networks
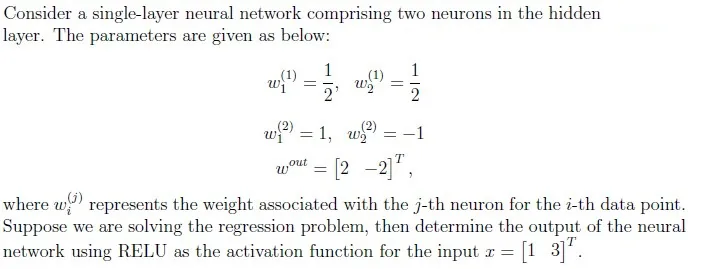
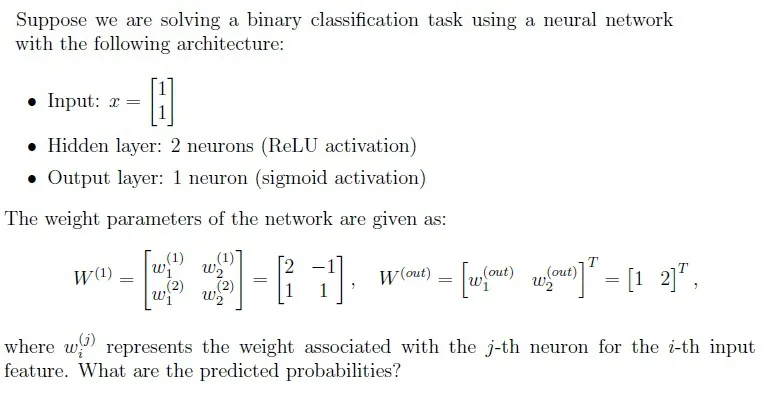
Neural network forward pass with ReLU/sigmoid for a given input
- Q1NAT4 Marks·Write the numberEnd Term · 13 Apr 2025 (AN)Key ↓
 Your answer:
Read the passage below, then answer Q2
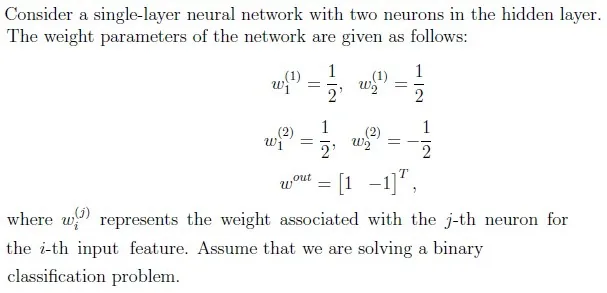
Based on the above data, answer the given subquestions.
Q2NAT3 Marks·Write the numberEnd Term · 13 Apr 2025 (FN)Key ↓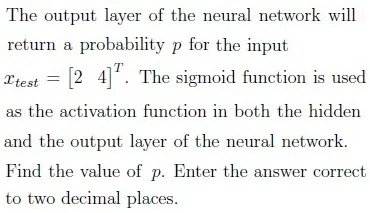 Your answer:
- Q3MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
- A
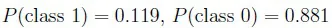
- B
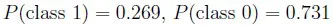
- C
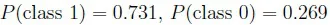
- D
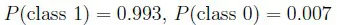
- A
- Q4NAT4 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓
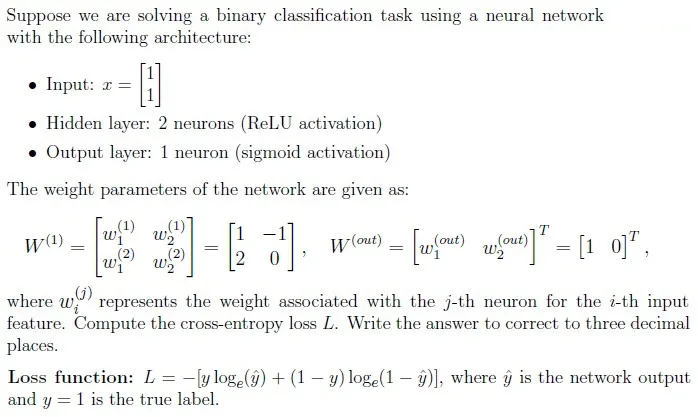 Your answer:
Type 2 · asked 3 times · MLE, MAP & Bayesian estimation
Find the MAP estimate of a parameter with a uniform prior
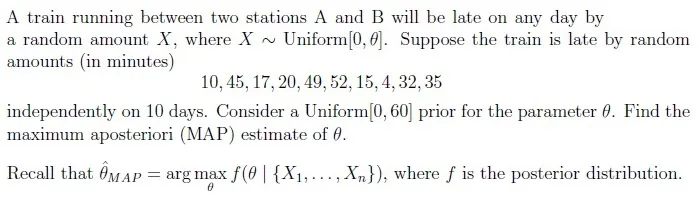
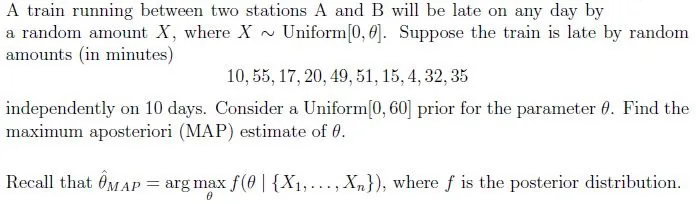
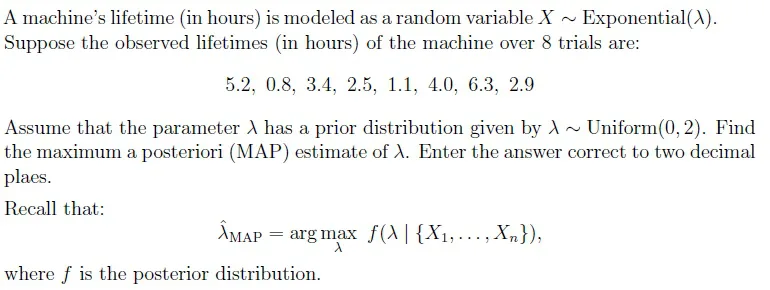
Type 3 · asked 3 times · K-means clustering
Statements on k-means / Lloyd's algorithm: init, outliers, convergence
- Q8MSQ3 Marks·Choose all correct optionsEnd Term · 22 Dec 2024 (AN)Key ↓
Select the correct statements from the following for k-means algorithm:
- AIn k-means algorithm, all cluster initializations lead to the same result.
- Bk-means algorithm is sensitive to outliers.
- COne initialization may converge while another may not.
- DThe initialization of cluster centres may affect the number of iterations k- means takes to converge.
- Q9MSQ2 Marks·Choose all correct optionsEnd Term · 31 Aug 2025 (FN)Key ↓
With respect to the Lloyd’s algorithm, choose the correct statements:
- AThe partition configurations cannot repeat themselves.
- BAfter doing the reassignments (consider at least one point reassigned to the new cluster), we might get the same means for all clusters.
- CObjective function after making the re-assignments strictly reduces.
- DObjective function after making the re-assignments strictly increases.
- Q10MSQ2 Marks·Choose all correct optionsQuiz 1 · 26 Oct 2025 (AN)Key ↓
Which among the following is true with respect to the Lloyds’ algorithm?
- AIt always converges.
- BIt may fail to converge for an initialization while it may converge for other initialization.
- CIt is sensitive to outliers.
- DThe solution produced is always the optimal.
Type 4 · asked 3 times · K-means clustering
Run Lloyd's (k-means) algorithm from given initial clusters or centres
- Q11MCQ3 Marks·Choose one optionEnd Term · 13 Apr 2025 (AN)Key ↓
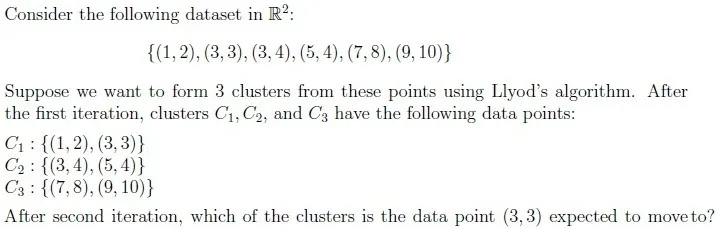
- A

- B

- C

- A
- Q12NAT3 Marks·Write the numberEnd Term · 13 Apr 2025 (FN)Key ↓
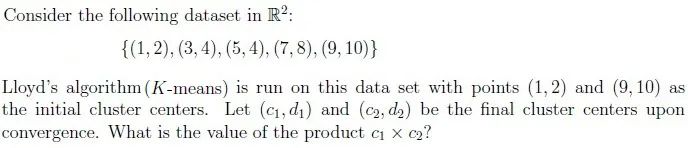 Your answer:
Read the passage below, then answer Q13
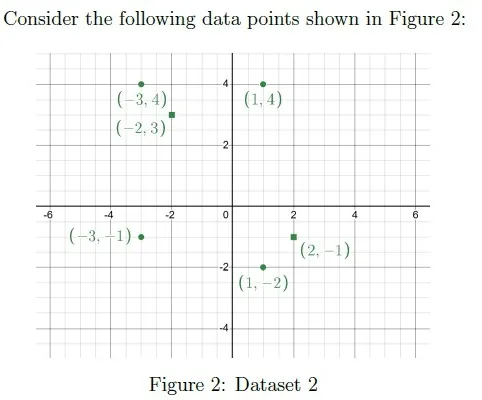
Based on the above data, answer the given subquestions.
Q13MCQ3 Marks·Choose one optionQuiz 1 · 26 Oct 2025 (AN)Key ↓Perform K-means clustering with K = 2 and initial cluster centers at (−2, 3) and (2,−1). What are the final means of clusters after convergence?
- A
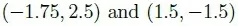
- B
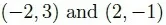
- C
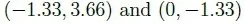
- D
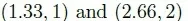
- A
Type 5 · asked 3 times · Perceptron algorithm
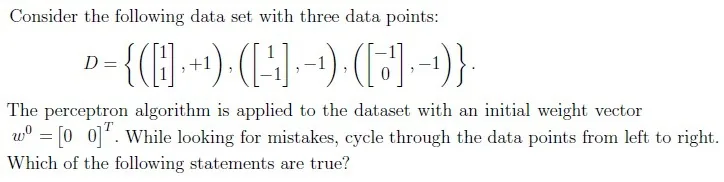
Run the perceptron on a small dataset cycling left to right
- Q14MSQ4 Marks·Choose all correct optionsEnd Term · 13 Apr 2025 (AN)Key ↓
- A
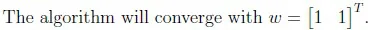
- B
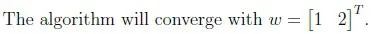
- C
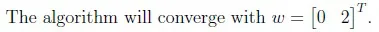
- D
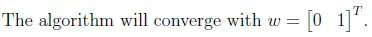
- E
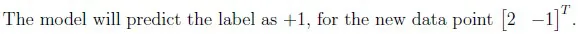
- F
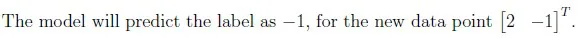
- A
Read the passage below, then answer Q15
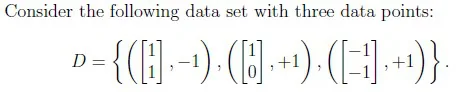
Based on the above data, answer the given subquestions.
Q15NAT3 Marks·Write the numberEnd Term · 13 Apr 2025 (FN)Key ↓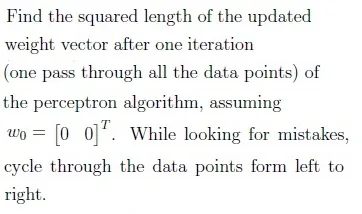 Your answer:
- Q16MCQ3 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
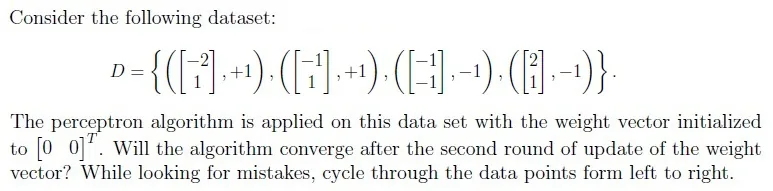
- AYes
- BNo
Type 6 · asked 3 times · Bagging, boosting & random forests
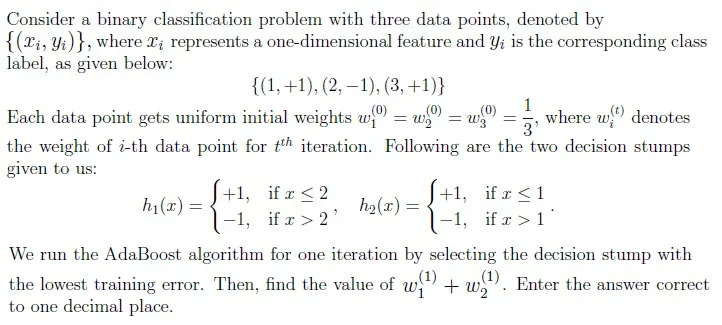
Run one round of AdaBoost: pick the stump and update weights
Read the passage below, then answer Q17
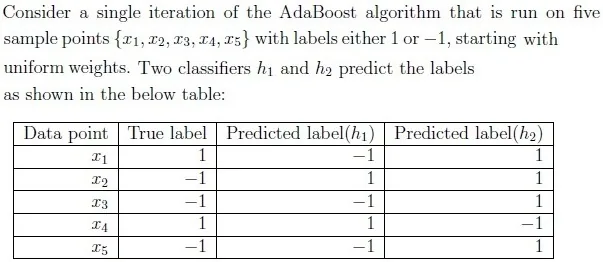
Based on the above data, answer the given subquestions.
Q17MCQ3 Marks·Choose one optionEnd Term · 13 Apr 2025 (AN)Key ↓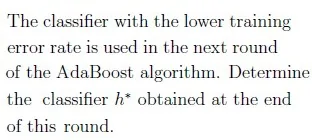
- A
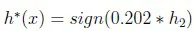
- B
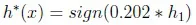
- C
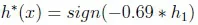
- D
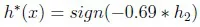
- A
- Q18MCQ4 Marks·Choose one optionEnd Term · 13 Apr 2025 (FN)Key ↓
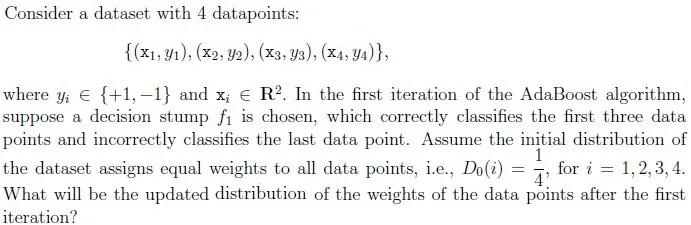
- A
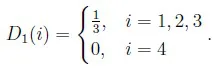
- B
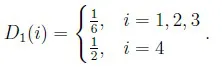
- C
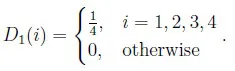
- D
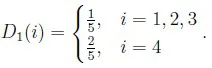
- A
- Q19NAT4 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓
 Your answer:
Type 7 · asked 2 times · PCA, kernel PCA & kernels
Variance along the first PC for the dataset {-2u, -u, u, 2u}
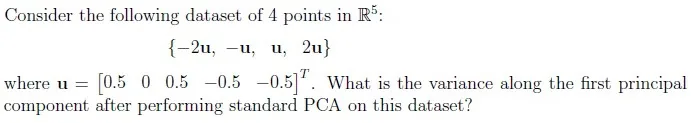 NOTE: Enter the answer correct to one decimal place
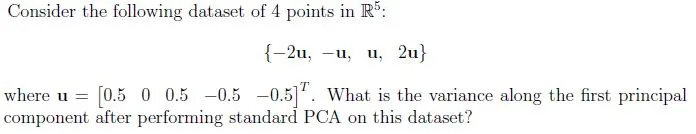 NOTE: Enter the answer correct to one decimal place
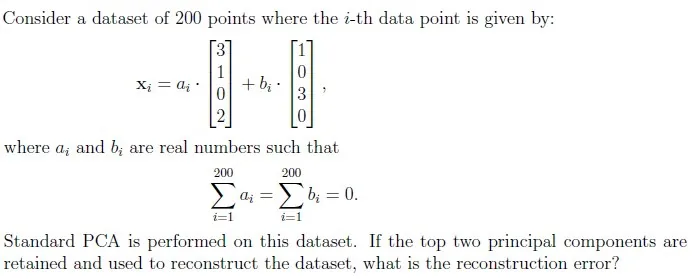
Type 8 · asked 2 times · PCA, kernel PCA & kernels
PCA reconstruction error when keeping the top two components
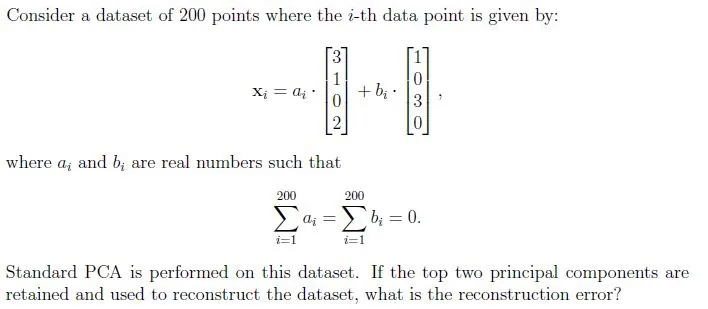
Type 9 · asked 2 times · MLE, MAP & Bayesian estimation
Posterior mean of a probability with a Beta prior
- Q24NAT4 Marks·Write the numberEnd Term · 13 Apr 2025 (AN)Key ↓
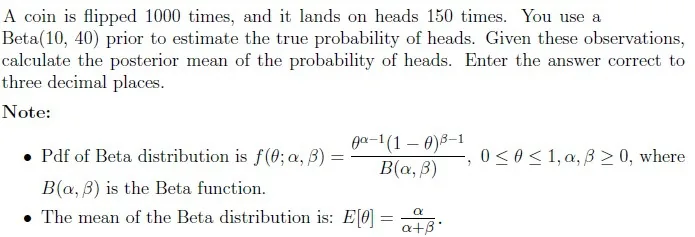 Your answer:
- Q25MSQ4 Marks·Choose all correct optionsQuiz 1 · 26 Oct 2025 (AN)Key ↓
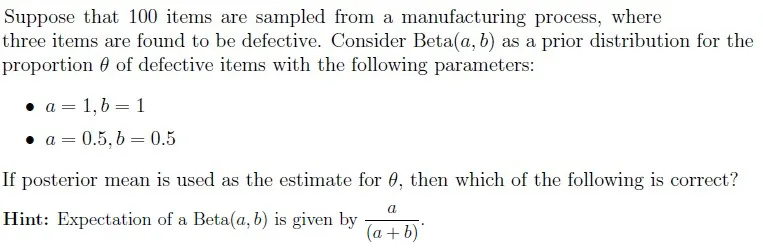
- APosterior mean for Beta(1, 1) is 0.039.
- BPosterior mean for Beta(1, 1) is 0.03.
- CPosterior mean for Beta(0.5, 0.5) is 0.025.
- DPosterior mean for Beta(0.5, 0.5) is 0.034.
Type 10 · asked 2 times · Logistic regression
Logistic regression spam detector: threshold and error trade-off
- Q26NAT3 Marks·Write the numberEnd Term · 22 Dec 2024 (AN)Key ↓
Consider a logistic regression model trained to detect spam emails. Emails containing harmful phishing links are labeled as spam (1), while regular emails are labeled as not spam (0). A good spam detector should correctly identify almost all emails with phishing links. Even a single phishing email incorrectly classified as not spam could expose users to significant risks. However, the detector may classify some regular emails as spam. This trade-off is acceptable to ensure safety. To ensure user safety, if the threshold is set to a low value to prioritize the detection of phishing emails, type 1. If the threshold is set to a high value to minimize false positives (misclassifying regular emails as spam), type 0.
Your answer: - Q27NAT3 Marks·Write the numberEnd Term · 22 Dec 2024 (FN)Key ↓
Consider a logistic regression model trained to detect spam emails. Emails containing harmful phishing links are labeled as spam (1), while regular emails are labeled as not spam (0). A good spam detector should correctly identify almost all emails with phishing links. Even a single phishing email incorrectly classified as not spam could expose users to significant risks. However, the detector may classify some regular emails as spam. This trade-off is acceptable to ensure safety. To ensure user safety, if the threshold is set to a low value to prioritize the detection of phishing emails, type 1. If the threshold is set to a high value to minimize false positives (misclassifying regular emails as spam), type 0.
Your answer:
Type 11 · asked 2 times · Bias-variance, overfitting & validation
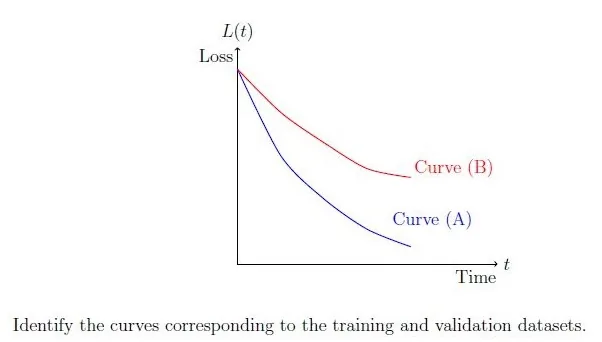
Identify training vs validation loss curves
- Q28MSQ3 Marks·Choose all correct optionsEnd Term · 22 Dec 2024 (AN)Key ↓
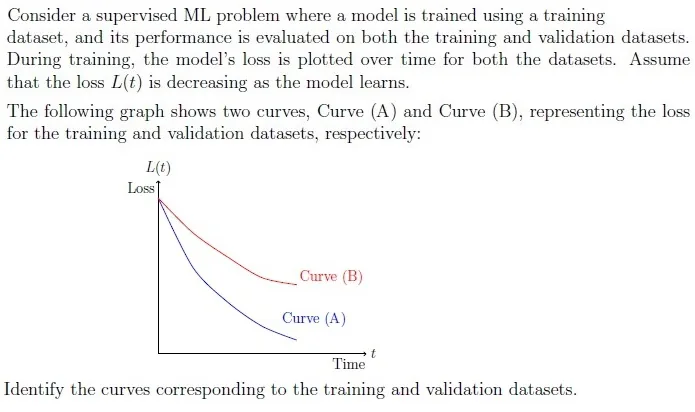
- ACurve (A) represents the training loss.
- BCurve (B) represents the training loss.
- CCurve (A) represents the validation loss.
- DCurve (B) represents the validation loss.
- Q29MSQ3 Marks·Choose all correct optionsEnd Term · 22 Dec 2024 (FN)Key ↓
Consider a supervised ML problem where a model is trained using a training dataset, and its performance is evaluated on both the training and validation datasets. During training, the model’s loss is plotted over time for both the datasets. Assume that the loss L(t) is decreasing as the model learns. The following graph shows two curves, Curve (A) and Curve (B), representing the loss for the training and validation datasets, respectively:
- ACurve (A) represents the training loss.
- BCurve (B) represents the training loss.
- CCurve (A) represents the validation loss.
- DCurve (B) represents the validation loss.
Type 12 · asked 2 times · Linear regression
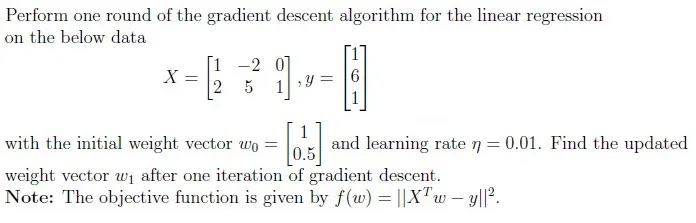
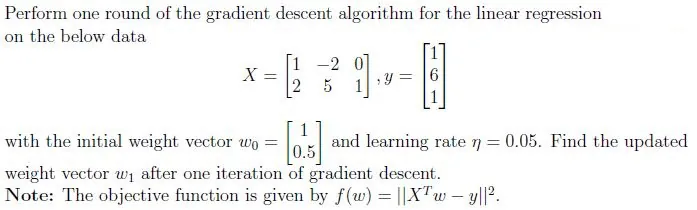
One gradient descent step for linear regression
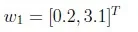
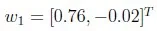
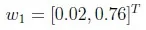
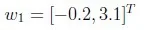
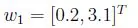
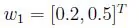
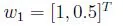
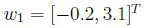
Type 13 · asked 2 times · Perceptron algorithm
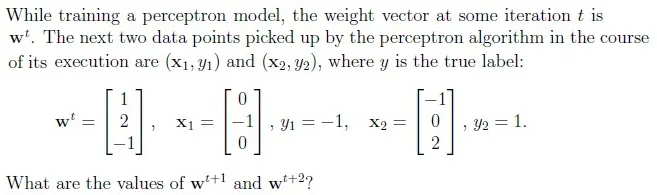
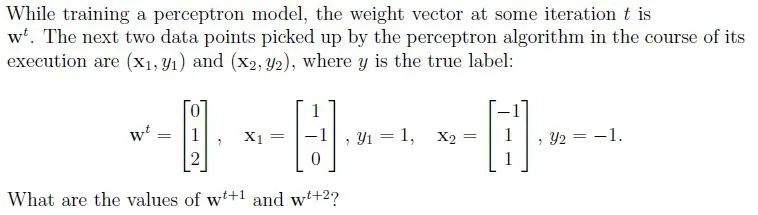
Perceptron: weights after the next two update points
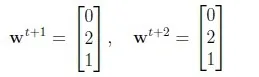
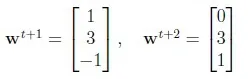
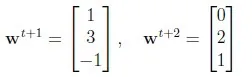
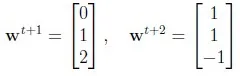
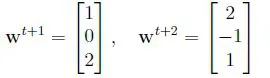
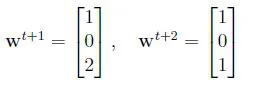
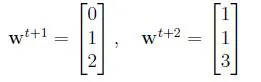
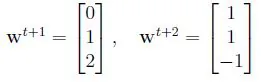
Type 14 · asked 2 times · Naive Bayes & generative models
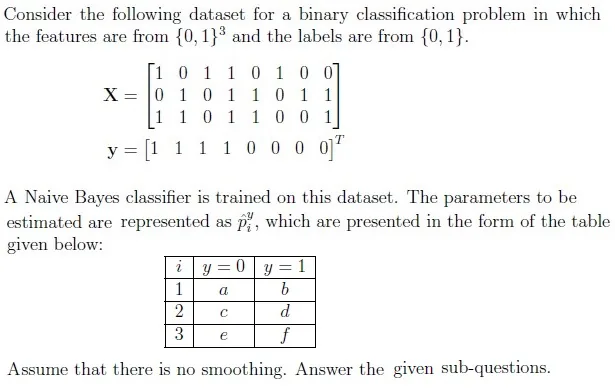
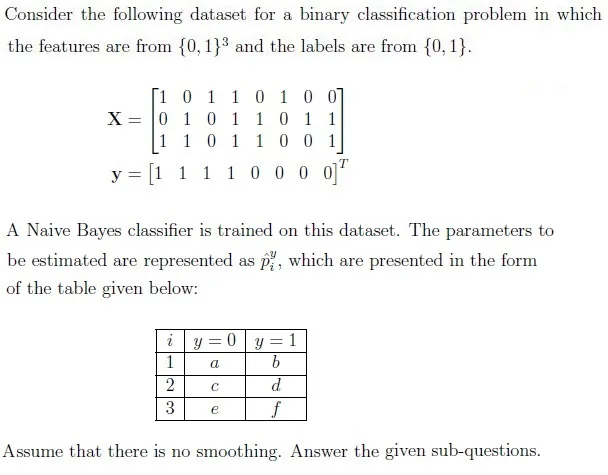
Naive Bayes passage: find a + b from estimated parameters
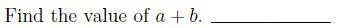
Type 15 · asked 2 times · Naive Bayes & generative models
Naive Bayes passage: find b + d + f from estimated parameters
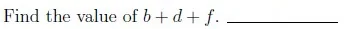
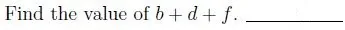
Type 16 · asked 2 times · Naive Bayes & generative models
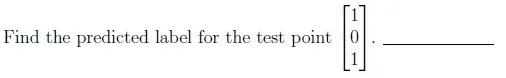
Naive Bayes passage: predict the label for test point [1,0,1]
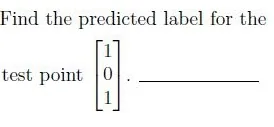
Type 17 · asked 2 times · Bias-variance, overfitting & validation
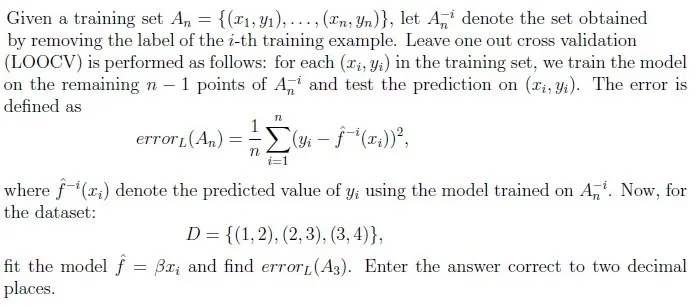
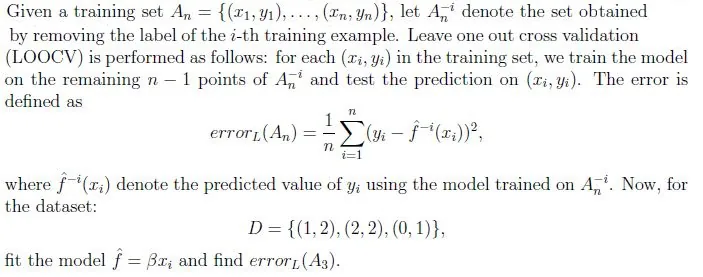
LOOCV error for the model f = beta x on three points
Type 18 · asked 2 times · Support vector machines
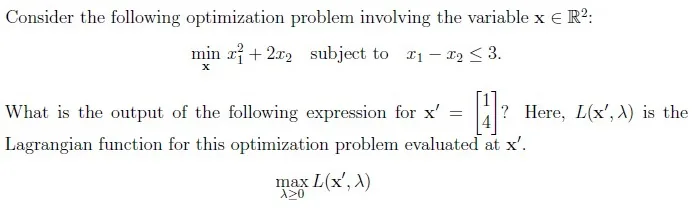
Evaluate max over lambda of the Lagrangian at a given point
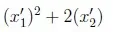


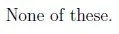
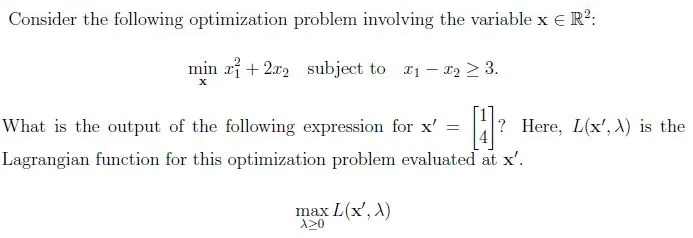
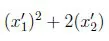


Type 19 · asked 2 times · Bias-variance, overfitting & validation
Bias, variance, weak learners and bagging statements
- Q44MCQ3 Marks·Choose one optionEnd Term · 22 Dec 2024 (AN)Key ↓
Which of the following options are not correct? Select all that apply.
- AUnderfitted models generally have less bias and high variance.
- BA decision tree with the maximum possible length may lead to overfitting.
- CWeak learners are those whose performance is slightly better than the random classifier.
- DAll the estimators in bagging can be trained parallelly.
- Q45MSQ3 Marks·Choose all correct optionsEnd Term · 22 Dec 2024 (FN)Key ↓
Which of the following options are correct? Select all that apply.
- AUnderfitted models generally have less bias and high variance.
- BA decision tree with the maximum possible length may lead to overfitting.
- CWeak learners are those whose performance is slightly better than the random classifier.
- DAll the estimators in bagging can be trained parallelly.
Type 20 · asked 2 times · Support vector machines
Effect of removing non-support vectors on an SVM
- Q46MCQ2 Marks·Choose one optionEnd Term · 22 Dec 2024 (AN)Key ↓
If we remove all the non-support vectors from the dataset, what will be the impact on the model using SVM algorithm?
- AModel will overfit.
- BThe model will not be changed.
- CModel will underfit.
- DAccuracy of the model will increase.
- Q47MCQ2 Marks·Choose one optionEnd Term · 22 Dec 2024 (FN)Key ↓
If we remove all the non-support vectors from the dataset, what will be the impact on the model using SVM algorithm?
- AModel will overfit.
- BThe model will not be changed.
- CModel will underfit.
- DAccuracy of the model will increase.
Type 21 · asked 2 times · Bagging, boosting & random forests
When does AdaBoost decrease a training point's weight
- Q48MCQ2 Marks·Choose one optionEnd Term · 22 Dec 2024 (AN)Key ↓
In each round of AdaBoost, the weight for a particular training observation is decreased from round t to round t + 1 if the observation was:
- Aclassified incorrectly by the weak learner trained in the round.
- Bclassified correctly by the weak learner trained in the round.
- Cclassified incorrectly by a majority of the weak learners trained up to the round.
- Dclassified correctly by a majority of the weak learners trained up to the round.
- Q49MCQ2 Marks·Choose one optionEnd Term · 22 Dec 2024 (FN)Key ↓
In each round of AdaBoost, the weight for a particular training observation is decreased from round t to round t + 1 if the observation was:
- Aclassified incorrectly by the weak learner trained in the round.
- Bclassified correctly by the weak learner trained in the round.
- Cclassified incorrectly by a majority of the weak learners trained up to the round.
- Dclassified correctly by a majority of the weak learners trained up to the round.
Type 22 · asked 2 times · Bias-variance, overfitting & validation
Does more model complexity always raise test error
- Q50MCQ1 Mark·Choose one optionEnd Term · 22 Dec 2024 (AN)Key ↓
Is the following statement true or false? For a fixed size of the training and the test set, increasing the complexity of the model always leads to an increment in the test error.
- ATrue
- BFalse
- Q51MCQ1 Mark·Choose one optionEnd Term · 22 Dec 2024 (FN)Key ↓
Is the following statement true or false? For a fixed size of the training and the test set, increasing the complexity of the model always leads to an increment in the test error.
- ATRUE
- BFALSE
Type 23 · asked 2 times · Support vector machines
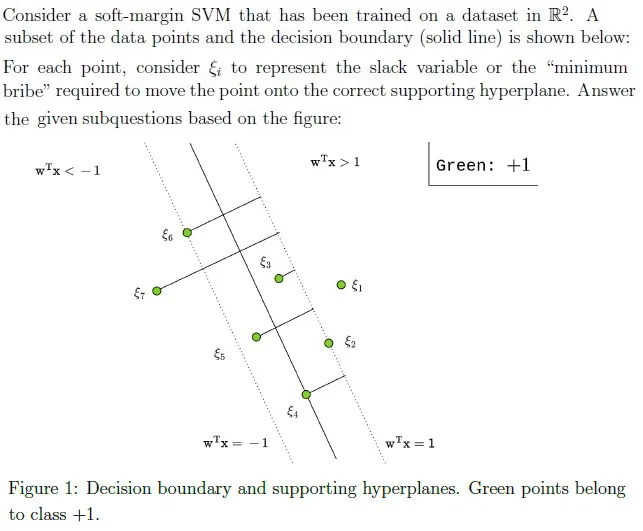
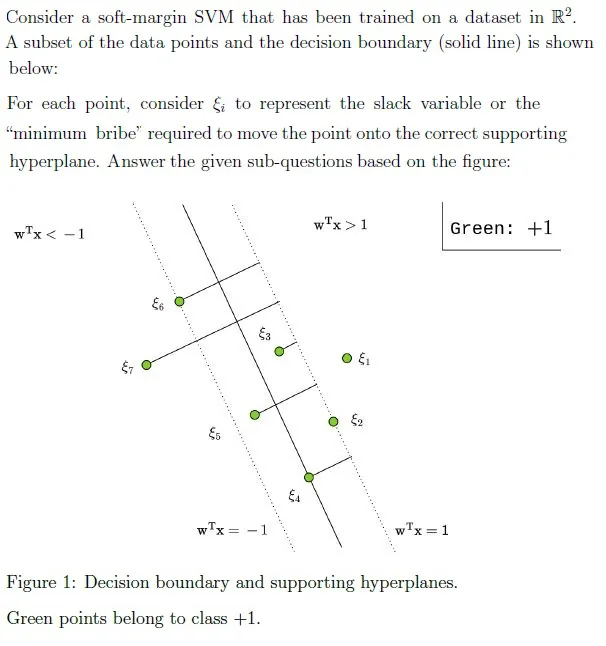
Soft-margin SVM slack value xi_4
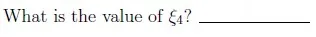
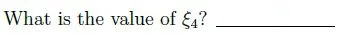
Type 24 · asked 2 times · Support vector machines
Soft-margin SVM slack value xi_1
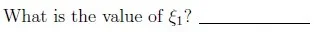
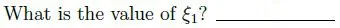
Type 25 · asked 2 times · Support vector machines
Soft-margin SVM slack value xi_2
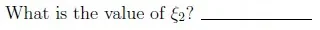
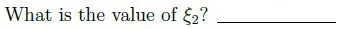
Type 26 · asked 2 times · Support vector machines
Soft-margin SVM slack value xi_6
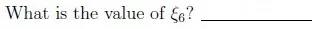
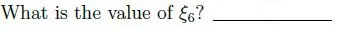
Type 27 · asked 2 times · Support vector machines
Soft-margin SVM: range of xi_5 and xi_7

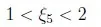

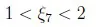

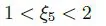

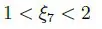
Type 28 · asked 2 times · Ridge & lasso regularization
Effect of the regularization term / lambda in ridge and lasso
- Q62MSQ2 Marks·Choose all correct optionsEnd Term · 13 Apr 2025 (AN)Key ↓
What is the role of the regularization term in ridge regression?
- AIt ensures that the dataset is normally distributed.
- BIt penalizes large coefficients to reduce overfitting.
- CIt forces more coefficients to be exactly zero, performing feature selection.
- DIt increases the variance of the model.
- Q63MSQ2 Marks·Choose all correct optionsEnd Term · 13 Apr 2025 (FN)Key ↓
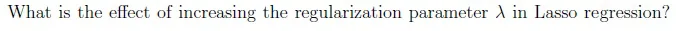
- AIt penalizes large coefficients to reduce overfitting.
- BIt shrinks the coefficients but does not set them to zero.
- CIt forces more coefficients to be exactly zero, performing feature selection.
- DIt has no effect on the regression model.
Type 29 · asked 2 times · Ridge & lasso regularization
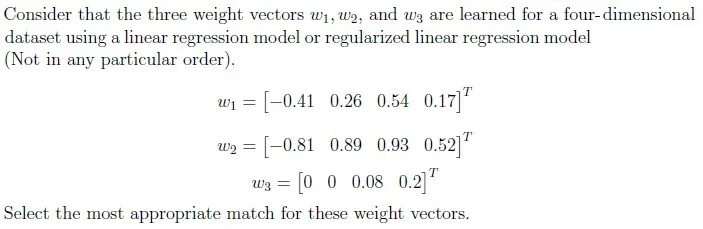
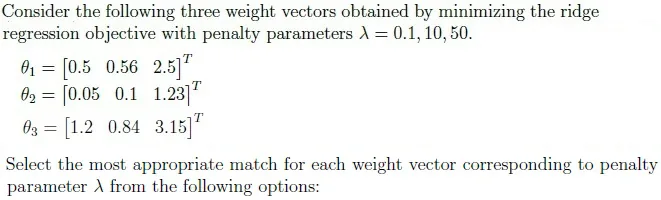
Match weight vectors to regularization strength
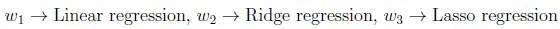
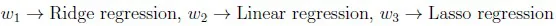
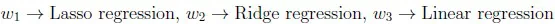
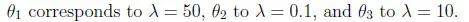
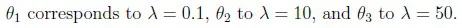
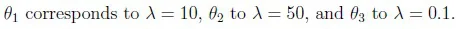
Type 30 · asked 2 times · Ridge & lasso regularization
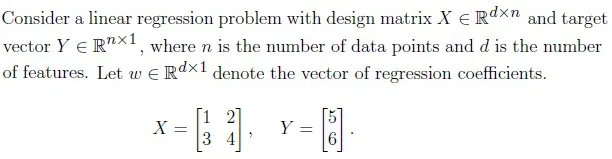
Compute the ML and ridge weight estimates for a given lambda
Read the passage below, then answer Q66
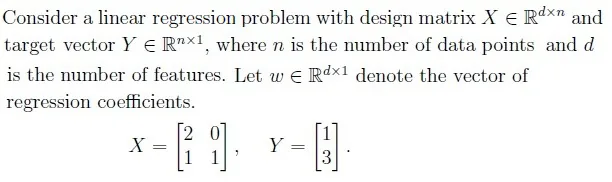
Based on the above data, answer the given subquestions.
Q66MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓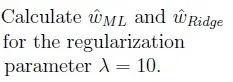
- A
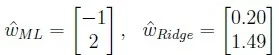
- B
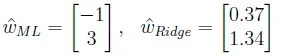
- C
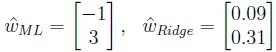
- D
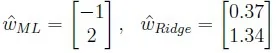
- A
Read the passage below, then answer Q67
Based on the above data, answer the given subquestions.
Q67MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓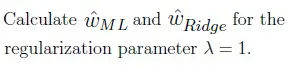
- A
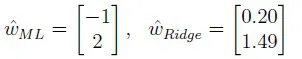
- B
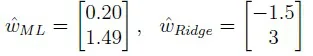
- C
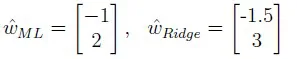
- D
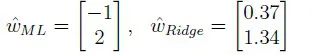
- A
Type 31 · asked 2 times · Ridge & lasso regularization
How ridge coefficients change as lambda changes
Read the passage below, then answer Q68
Based on the above data, answer the given subquestions.
Q68MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓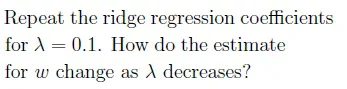
- AThe coefficients shrinks towards zero.
- BThe coefficients increases in magnitude.
- CThe coefficients remain unchanged.
Read the passage below, then answer Q69
Based on the above data, answer the given subquestions.
Q69MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓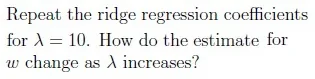
- AThe coefficients shrinks towards zero.
- BThe coefficients increases in magnitude.
- CThe coefficients remain unchanged.
Type 32 · asked 2 times · Support vector machines
Soft-margin SVM: statements about optimal primal and dual solutions

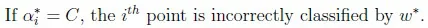
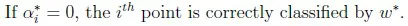
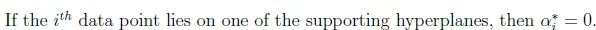
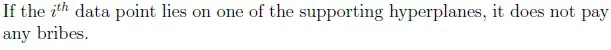
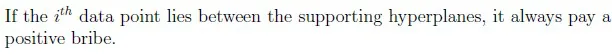

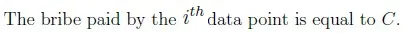
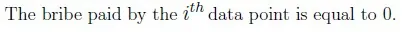
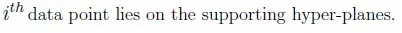
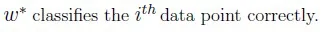
Type 33 · asked 2 times · Support vector machines
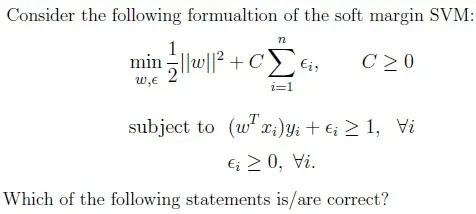
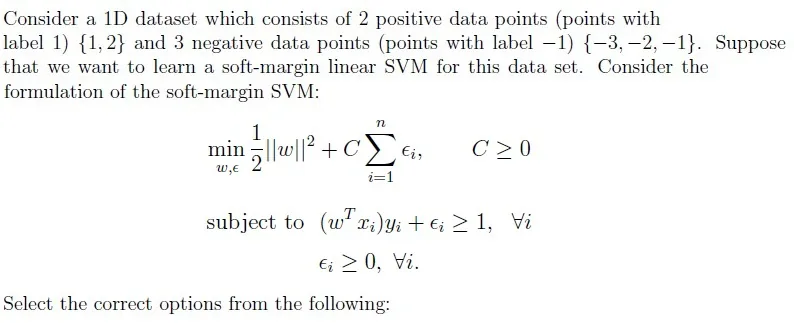
Soft-margin SVM formulation: which statements are correct
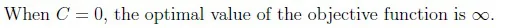
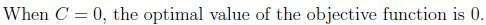
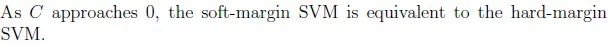
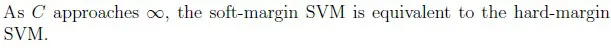
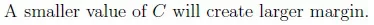
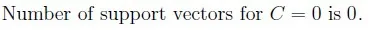
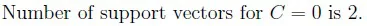
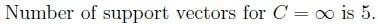
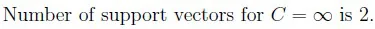
Type 34 · asked 2 times · Support vector machines
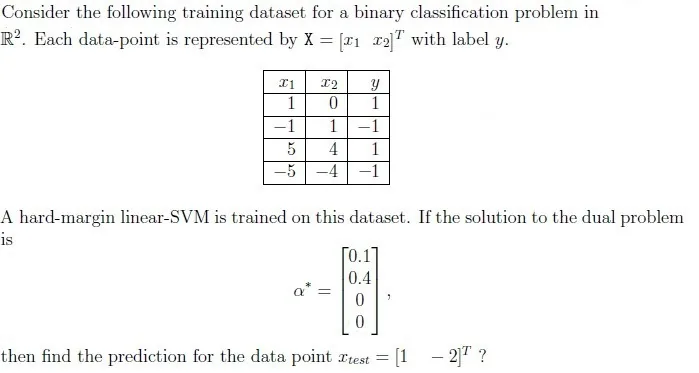
Use the SVM dual solution alpha* to get w, then predict or find margin
- Q74NAT3 Marks·Write the numberEnd Term · 13 Apr 2025 (AN)Key ↓
 Your answer:
Read the passage below, then answer Q75
Consider the datapoints (−2,−2) with label +1 and (2, 2) with label −1. A hard margin SVM is applied on this dataset. Answer the given subquestions:
Q75NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓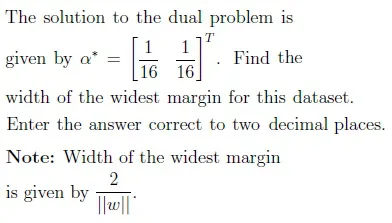 Your answer:
Type 35 · asked 2 times · Support vector machines
Identify which points are (not) support vectors
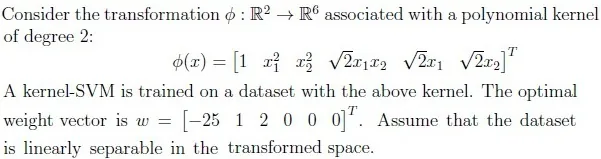
Read the passage below, then answer Q76
Based on the above data, answer the given subquestions.
Q76MSQ3 Marks·Choose all correct optionsEnd Term · 13 Apr 2025 (FN)Key ↓Which of the following training data points are certainly not support vectors?
- A

- B

- C

- D

- A
- Q77MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
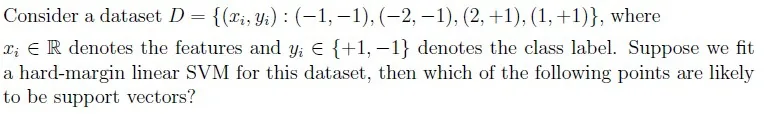
- A
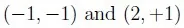
- B
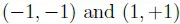
- C
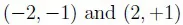
- D
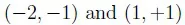
- A
Type 36 · asked 2 times · Naive Bayes & generative models
Count the parameters a naive Bayes model must estimate
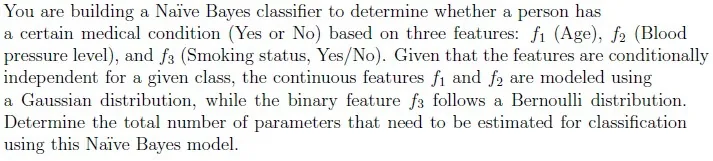
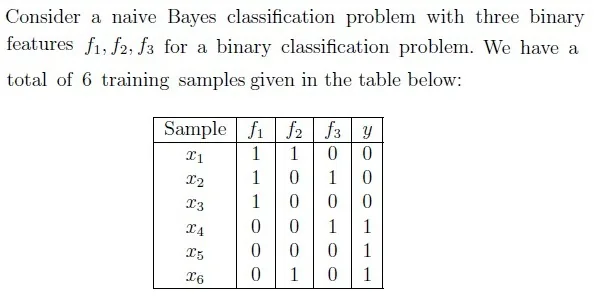
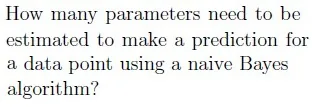
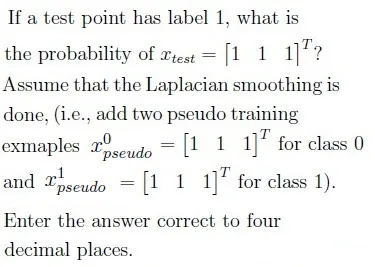
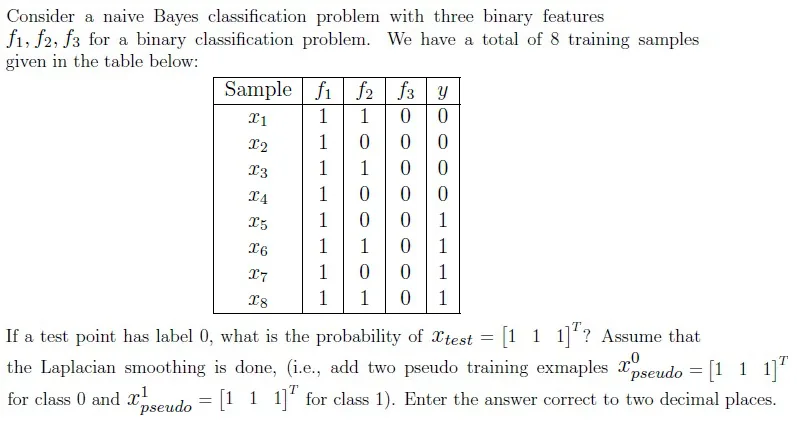
Type 37 · asked 2 times · Naive Bayes & generative models
Naive Bayes class-conditional probability with Laplace smoothing
Type 38 · asked 2 times · Logistic regression
Logistic regression: predicted probability or label for a point
- Q82NAT3 Marks·Write the numberEnd Term · 13 Apr 2025 (AN)Key ↓
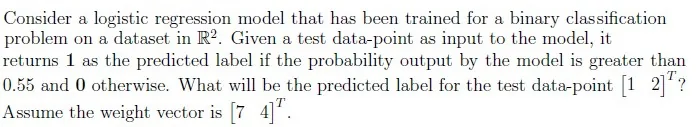 Your answer:
Read the passage below, then answer Q83
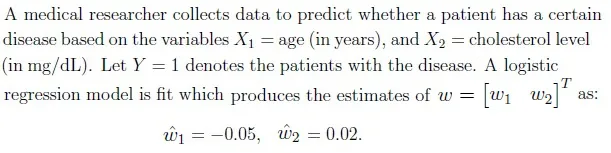
Based on the above data, answer the given subquestions.
Q83NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓What is the probability that a 60-year-old patient with a cholesterol level of 200 mg/dL has the disease? Enter the answer correct to two decimal places.
Your answer:
Type 39 · asked 2 times · Logistic regression
Logistic regression: feature value giving a target probability
- Q84NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓
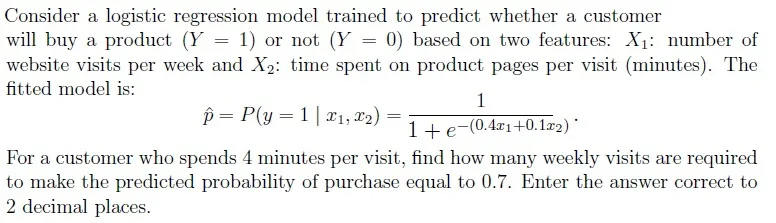 Your answer:
Read the passage below, then answer Q85
Based on the above data, answer the given subquestions.
Q85NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓How high should the cholesterol level be for the patient mentioned in the previous question to have a 50% chance of being diagnosed with the disease?
Your answer:
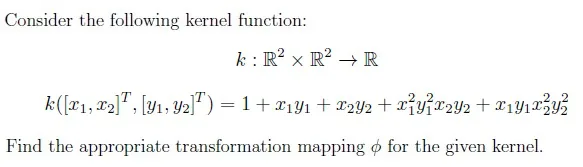
Type 40 · asked 2 times · PCA, kernel PCA & kernels
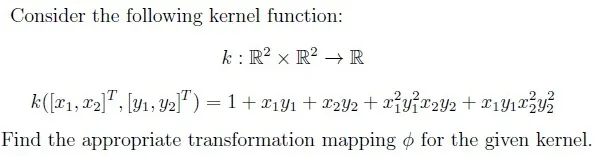
Find the feature map phi for a given polynomial kernel
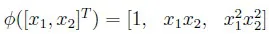
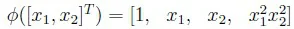
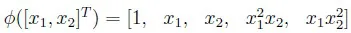
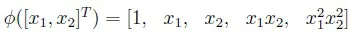
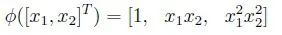
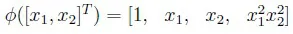
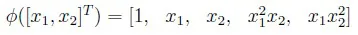
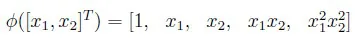
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.