Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning
End Term · 13 Apr 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ1 Mark·Choose one option
A neural network is being trained for a regression problem in which the target is in the interval (−1, 1). Which of the following is NOT a good choice for the activation function at the output layer?
- AReLU
- BLinear (identity)
- CTanh
- Q2MCQ3 Marks·Choose one option
In the transformer architecture, which of the following are true regarding cross attention in the decoder?
- AThe query vectors come from the decoder stack, while the key and value vectors come from the encoder stack.
- BThe query and value vectors come from the decoder stack, while the key vectors come from the encoder stack.
- CThe query, key and value vectors come from the decoder stack.
- DThe query, key and value vectors come from the encoder stack.
- Q3MSQ2 Marks·Choose all correct options
Consider applying dropout to a hidden layer with p = 0.5. Which of the following are true?
- ADuring training, a randomly chosen set of neurons in the layer are dropped out. The neurons to be dropped are determined dynamically during each iteration.
- BDuring inference (testing), no neurons are dropped out. Instead, the activation of each neuron in the layer is scaled by 0.5.
- CDuring training, a fixed set of neurons in the layer are dropped out. This set remains the same in every iteration and the neurons to be dropped are determined before the training begins.
- DDuring inference (testing), a randomly chosen set of neurons in the layer are dropped out.
- Q4MSQ3 Marks·Choose all correct options
Consider the following plot of error versus model complexity. Models of varying complexity are evaluated on the same training and test datasets. Model complexity increases from left to right:
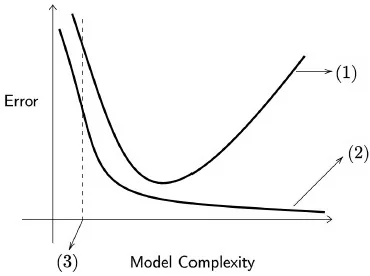 Select all true options.
- A(1) corresponds to the test error.
- B(2) corresponds to the training error.
- C(3) corresponds to a model with high bias and low variance.
- D(1) corresponds to the training error.
- E(2) corresponds to the test error.
- F(3) corresponds to a model with low bias and high variance.
- Q5MSQ3 Marks·Choose all correct options
Consider the following tasks which can be solved using an encoder-decoder architecture. Which of these tasks has a decoder where an RNN is not necessary?
- AVideo classification: outputs a single class label
- BSentiment analysis: outputs a single class label
- CDocument summarization: outputs a sequence of text
- DMachine translation: outputs a sequence of text
- EVideo captioning: outputs a sequence of text
- Q6NAT3 Marks·Write the number
The input volume to a convolutional layer is 100×100×5. If ten kernels, each of size 9 × 9, with unit stride are applied over this volume, what should be the padding so that the output volume has dimensions 100 × 100 × 10? Note that you should enter the value of P as per the convention we have been following.
Your answer: Read the passage below, then answer Q7–Q8
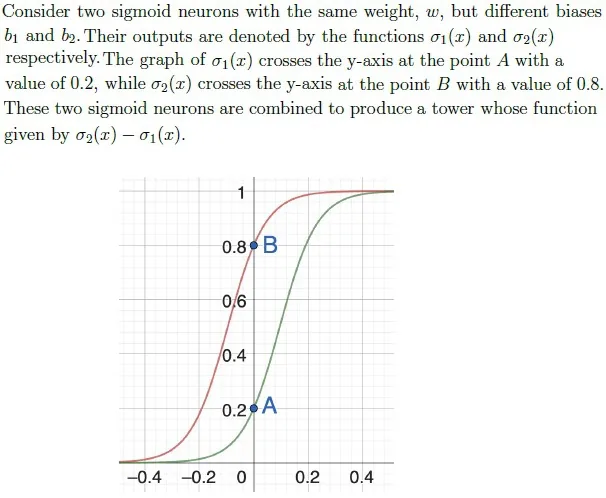
Based on the above data, answer the given subquestions.
Q7NAT2 Marks·Write the numberFind the value of x at which the tower attains its maximum value.
Your answer:- Q8NAT1 Mark·Write the number
Find the maximum value that the tower attains.
Your answer: Read the passage below, then answer Q9–Q11
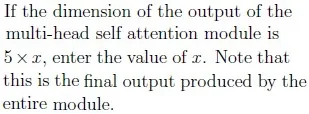
Consider the multi-head self-attention mechanism in the encoder of a transformer with 8 heads. The word embedding dimension is 32. In a given head, the query, key and value vectors have the same dimension and each of them is 4. The sequence length is 5.
Based on the above data, answer the given subquestions.
Q9MCQ1 Mark·Choose one optionIn any given head, what is the dimension of the W_Q matrix?
- A32 × 4
- B32 × 32
- C4 × 4
- D32 × 8
- E5 × 5
- Q10MCQ1 Mark·Choose one option
In any given head, what is the dimension of the query-key product matrix?
- A5 × 5
- B4 × 4
- C8 × 8
- D32 × 32
- Q11NAT1 Mark·Write the number
 Your answer:
Read the passage below, then answer Q12–Q14
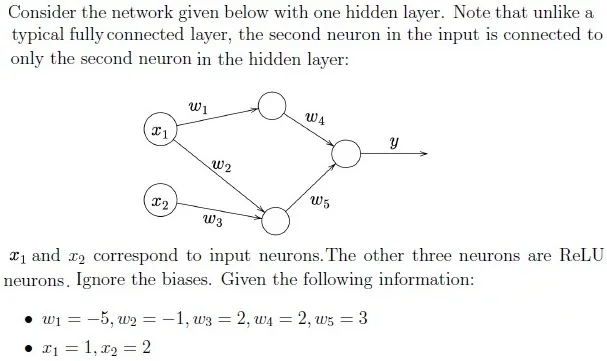
Based on the above data, answer the given subquestions.
Q12NAT1 Mark·Write the numberFind the value y at the end of the forward pass.
Your answer:- Q13NAT1 Mark·Write the number
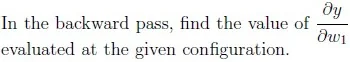 Your answer:
- Q14NAT1 Mark·Write the number
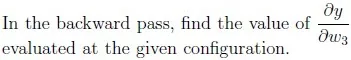 Your answer:
Read the passage below, then answer Q15–Q17
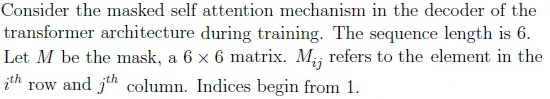
Based on the above data, answer the given subquestions.
Q15MCQ1 Mark·Choose one option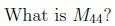
- A

- B

- C

- D

- A
- Q16MCQ1 Mark·Choose one option
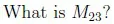
- A

- B

- C

- D

- A
- Q17MCQ1 Mark·Choose one option
Which of the following is true?
- AThe mask matrix is added to the query-key product matrix before applying softmax.
- BThe mask matrix is added to the query-key product matrix after applying softmax.
- CThe mask matrix could be added either before or after the softmax.
Read the passage below, then answer Q18–Q20
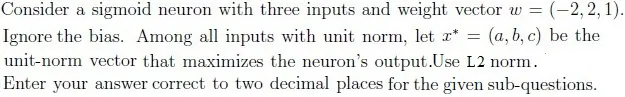
Based on the above data, answer the given subquestions.
Q18NAT1 Mark·Write the numberFind a.
Your answer:- Q19NAT1 Mark·Write the number
Find b.
Your answer: - Q20NAT1 Mark·Write the number
Find c.
Your answer: Read the passage below, then answer Q21–Q22
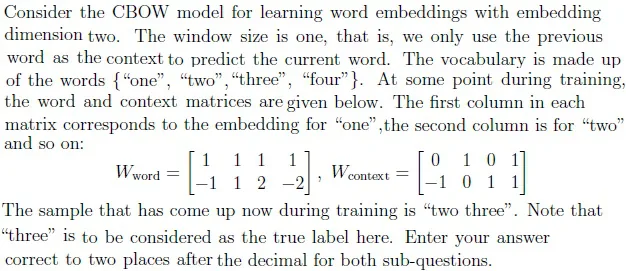
Based on the above data, answer the given subquestions.
Q21NAT2 Marks·Write the numberFind the probability of predicting “three” given “two” as context.
Your answer:- Q22NAT2 Marks·Write the number
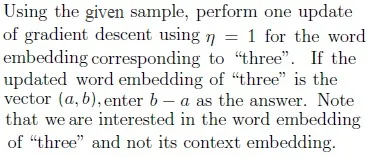 Your answer:
Read the passage below, then answer Q23–Q25
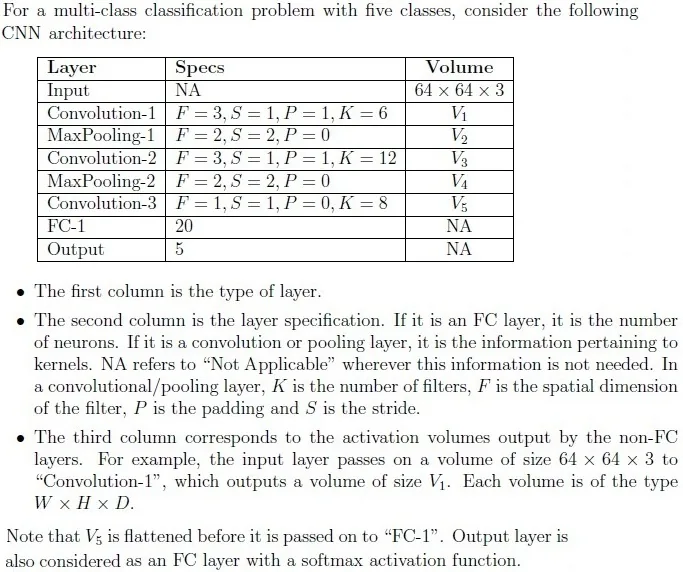
Based on the above data, answer the given subquestions.
Q23NAT1 Mark·Write the numberFind the number of parameters associated with the layer “Convolution-2” that are required to transform V_2 to V_3. Ignore biases.
Your answer:- Q24MCQ1 Mark·Choose one option
Which of the following corresponds to V_4, the activation volume output by the layer “MaxPooling- 2”?
- A16 × 16 × 12
- B8 × 8 × 12
- C32 × 32 × 8
- D16 × 16 × 6
- Q25MCQ2 Marks·Choose one option
The parameters associated with the fully connected layers, namely “FC- 1” and “Output”, represent what percentage of the total number of parameters in the network? The answer should be rounded off to the nearest integer. Ignore biases.
- A98%
- B85%
- C50%
- D10%
Read the passage below, then answer Q26–Q28
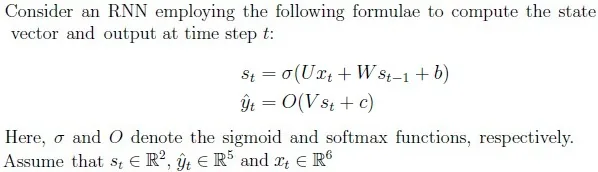
Based on the above data, answer the given subquestions.
Q26NAT2 Marks·Write the numberWith a total of 7 time steps (T = 7), what is the total count of parameters (including bias) within the network?
Your answer:- Q27MCQ2 Marks·Choose one option
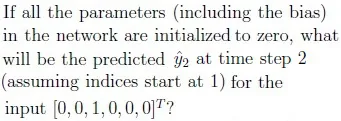
- A
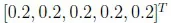
- B
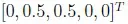
- C
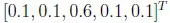
- D

- A
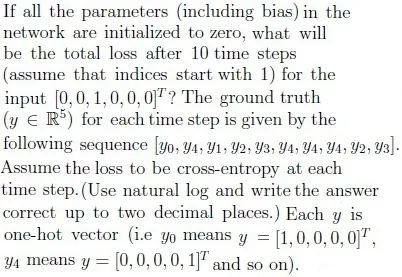
- Q28NAT2 Marks·Write the number
 Your answer:
Read the passage below, then answer Q29–Q31
Based on the above data, answer the given subquestions.
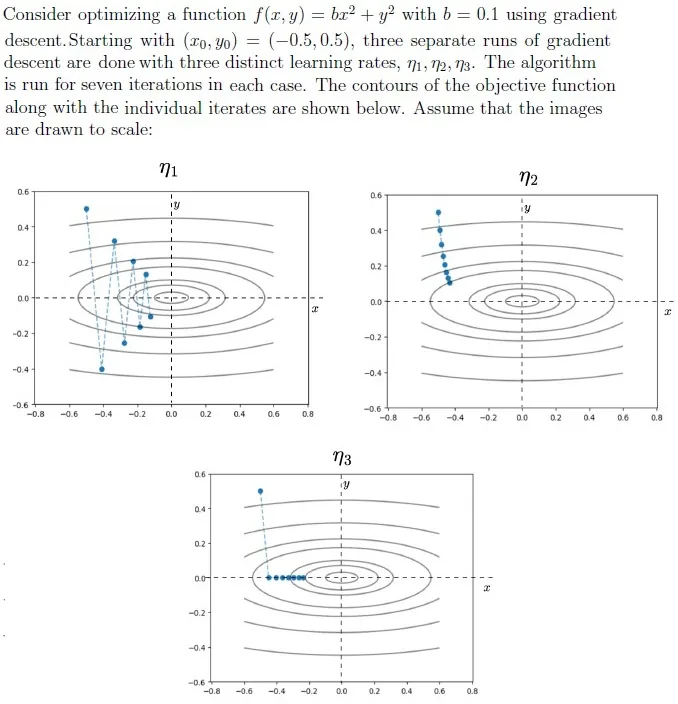
Q29MCQ2 Marks·Choose one optionWhich of these is the correct ordering among the learning rates?
- A
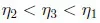
- B

- C
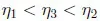
- D
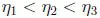
- A
- Q30MCQ2 Marks·Choose one option
- A0.5
- B0.9
- C0.1
- D1
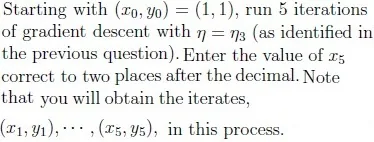
- Q31NAT2 Marks·Write the number
 Your answer:
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.