Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning for Computer Vision
Vision-language: CLIP & BLIP
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
End Term · 31 Aug 2025 (FN)End Term
- Q1MSQ2 Marks·Choose all correct options
Which of the following statements about CLIP are TRUE? (Select ALL that apply)
- ACLIP uses a contrastive loss function to align text and image embeddings.
- BCLIP requires image labels for training.
- CCLIP is trained to maximize cosine similarity between embeddings of matching text-image pairs.
- DCLIP model is trained with pretext tasks such as rotation prediction and inpainting to learn effective feature representations.
- ETo use the CLIP model for image classification, it is imperative to finetune it on downstream datasets.
Read the passage below, then answer Q2–Q12
Consider the BLIP model architecture with an input (image-text pair) as shown below: For each of the given entities, enter the appropriate number from the figure that corresponds to it:
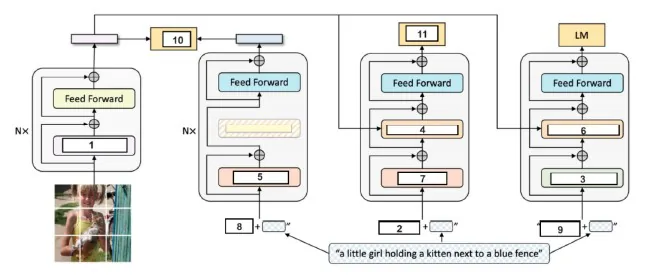
Based on the above data, answer the given subquestions.
Q2NAT0.55 Marks·Write the number Your answer:
- Q3NAT0.55 Marks·Write the number
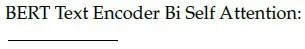 Your answer:
- Q4NAT0.55 Marks·Write the number
 Your answer:
- Q5NAT0.55 Marks·Write the number
 Your answer:
- Q6NAT0.55 Marks·Write the number
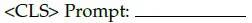 Your answer:
- Q7NAT0.55 Marks·Write the number
 Your answer:
- Q8NAT0.54 Marks·Write the number
 Your answer:
- Q9NAT0.54 Marks·Write the number
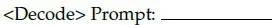 Your answer:
- Q10NAT0.54 Marks·Write the number
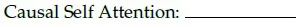 Your answer:
- Q11NAT0.54 Marks·Write the number
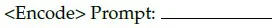 Your answer:
- Q12NAT0.54 Marks·Write the number
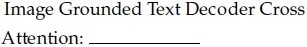 Your answer:
End Term · 31 Aug 2025 (AN)End Term
- Q13MCQ2 Marks·Choose one option
Given two normalized embeddings from CLIP, I = [0.2, 0.5, 0.3, 0.4] for an image and T = [0.1, 0.6, 0.3, 0.7] for a text description, compute the CLIPScore(I,T).
- A− 69%
- B0%
- C69%
- D50%
- Q14MSQ2 Marks·Choose all correct options
Which of the following statements about CLIP are TRUE? (Select ALL that apply)
- ACLIP uses a cross-entropy loss function to align text and image embeddings.
- BCLIP requires image labels for training.
- CCLIP is trained to maximize cosine similarity between embeddings of matching text-image pairs.
- DCLIP model is trained with pretext tasks such as rotation prediction and inpainting to learn effective feature representations.
- ETo use the CLIP model for image classification, it is imperative to finetune it on downstream datasets.
Read the passage below, then answer Q15–Q25
Consider the BLIP model architecture with an input (image-text pair) as shown below:
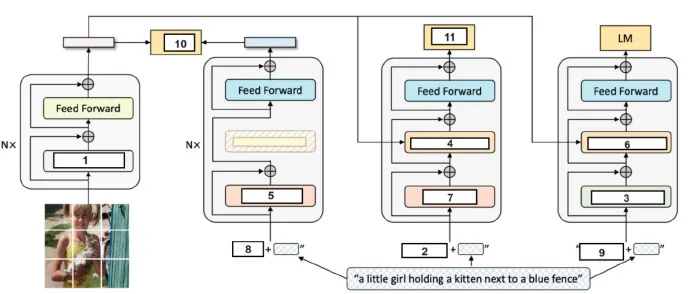
For each of the entities given, enter the appropriate number from the figure that corresponds to it:
Based on the above data, answer the given subquestions.
Q15NAT1 Mark·Write the numberSelf-Attention _______________
Your answer:- Q16NAT0.5 Marks·Write the number
BERT Text Encoder Bi Self Attention:__________________
Your answer: - Q17NAT0.5 Marks·Write the number
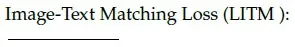
Image-Text Matching Loss (LITM ):__________________
Your answer: - Q18NAT0.5 Marks·Write the number
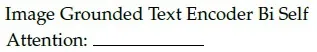
Image Grounded Text Encoder Bi Self Attention: ___________________
Your answer: - Q19NAT0.5 Marks·Write the number
 Your answer:
- Q20NAT0.5 Marks·Write the number
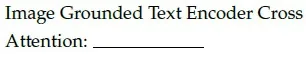
Image Grounded Text Encoder Cross Attention: _________________
Your answer: - Q21NAT0.5 Marks·Write the number
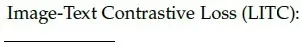
Image-Text Contrastive Loss (LITC): ____________
Your answer: - Q22NAT0.5 Marks·Write the number
 Your answer:
- Q23NAT0.5 Marks·Write the number
Causal Self Attention: _____________
Your answer: - Q24NAT0.5 Marks·Write the number
 Your answer:
- Q25NAT0.5 Marks·Write the number
Image Grounded Text Decoder Cross Attention: _____________
Your answer: