Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning for Computer Vision
Generative models
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
End Term · 31 Aug 2025 (FN)End Term
- Q1MSQ2 Marks·Choose all correct options
Which of the following statements are false? (Select all that apply)
- AGenerative adversarial networks (GANs) generate sharper images compared to Variational AutoEncoders (VAE)
- BGAN is an example of an implicit density estimation model
- CFully connected layers in mapping network of Style-GAN do not change the dimension of its input
- DThe generator and discriminator are always trained together in a GAN
- Q2MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all possible correct options)
- AAutoencoder are equivalent to Principal Component Analysis (PCA) provided we don’t use of non-linear activation functions
- BWhen using global attention on temporal data, alignment weights are learnt for encoder hidden representations for all time steps
- CPositional encoding is an important component of the transformer architecture as it conveys information about order in a given sequence
- DIt is not possible to generate different captions for the same image that have similar meaning but different tone/style
- EAutoencoders can not be used for data compression as its input and output dimensions are different
- Q3NAT2 Marks·Write the number
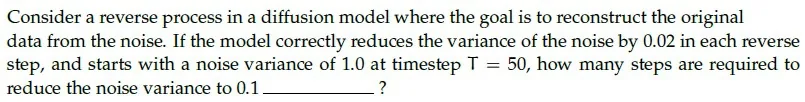 Your answer:
- Q4NAT2 Marks·Write the number
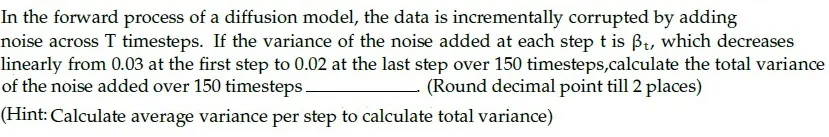 Your answer:
End Term · 31 Aug 2025 (AN)End Term
- Q5MCQ2 Marks·Choose one option
Vector Quantized Variational Autoencoder (VQ-VAE) utilizes a discrete latent representation as opposed to continuous latent spaces used in traditional VAEs. One of the key components of a VQ- VAE is the codebook, which consists of a set of learnable vectors. What is the primary role of the codebook in VQ-VAE?
- AIt performs the non-linear transformation of the input data to a higher dimensional space.
- BIt regularizes the encoder by penalizing complex encodings.
- CIt provides a finite set of vectors which the encoder’s outputs are mapped to, effectively quantizing the latent space.
- DIt decodes the quantized vectors back into the reconstructed input space.
- Q6MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all possible correct options)
- AVariational AutoEncoders (VAE) generate sharper images compared to Generative adversarial networks (GANs)
- BGAN is an example of an implicit density estimation model
- CFully connected layers in mapping network of Style-GAN change the dimension of its input
- DIn a GAN, the generator and discriminator are trained in an alternating fashion, each using the other’s output to improve.
- Q7MSQ2 Marks·Choose all correct options
Classifier-free guidance is a technique used in diffusion models to improve sample quality without the explicit use of a classifier. This technique involves modifying the sampling process based on a control parameter. If the control parameter, denoted as γ, is set to zero, what effect does this have on the generation process?
- AIt fails to generate realistic samples
- BIt removes all guidance, effectively making the process equivalent to the unconditional generation.
- CIt maximizes the influence of the classifier, leading to highly detailed generations.
- DIt can lead to more diverse samples compared to higher values of γ, as the generation process is less constrained by the conditional information.
- Q8MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all possible correct options)
- AAutoencoder are equivalent to Principal Component Analysis (PCA) provided we don’t use of non-linear activation functions
- BWhen using global attention on temporal data, alignment weights are learnt for encoder hidden representations for all time steps
- CPositional encoding is an important component of the trans- former architecture as it conveys information about order in a given sequence
- DIt is not possible to generate different captions for the same image that have similar meaning but different tone/style
- EAutoencoders can not be used for data compression as its input and output dimensions are different
- Q9NAT2 Marks·Write the number
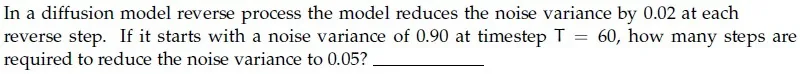 Your answer:
- Q10NAT2 Marks·Write the number
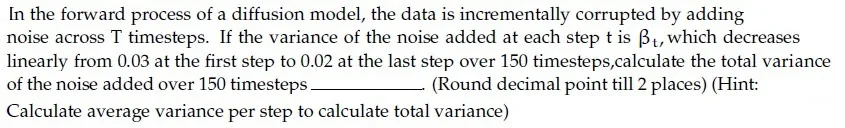 Your answer: