Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Machine Learning Techniques
All 2025 papers
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
Quiz 1 · 26 Oct 2025 (AN)Quiz 1
- Q1MSQ2 Marks·Choose all correct options
Which among the following is true with respect to the Lloyds’ algorithm?
- AIt always converges.
- BIt may fail to converge for an initialization while it may converge for other initialization.
- CIt is sensitive to outliers.
- DThe solution produced is always the optimal.
- Q2MSQ4 Marks·Choose all correct options

- AThere will be 50 non-zero eigenvalues of the covariance matrix.
- BThere will be 6 non-zero eigenvalues of the covariance matrix.
- CUsing the first 5 principal components, the dataset can be reconstructed with zero residue.
- DThe variance captured by the top 6 principal components equals the total variance of the dataset.
- Q3MSQ4 Marks·Choose all correct options
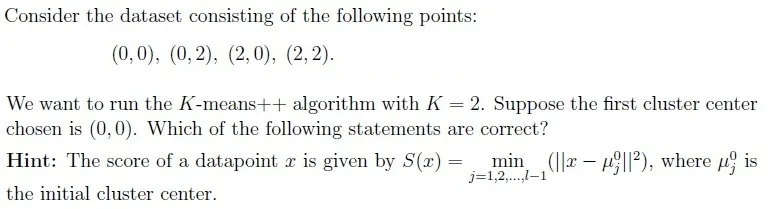
- AThe points (0, 2), (2, 0), and (2, 2) have the equal probability of being chosen as the second cluster center.
- BThe probability of selecting (2, 2) as the second cluster center is twice that of selecting (0, 2).
- CIf (2, 2) is chosen as the second cluster center, the algorithm will always converge in one iteration.
- DThe tie-breaking rule will affect the final cluster centers.
- Q4MSQ4 Marks·Choose all correct options
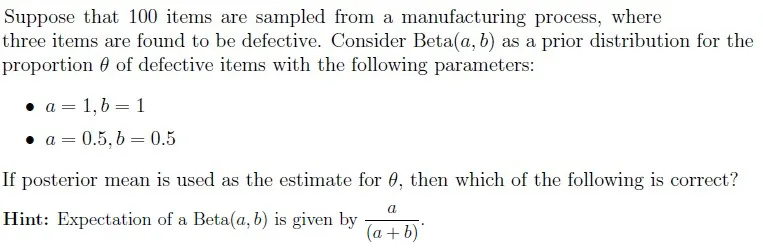
- APosterior mean for Beta(1, 1) is 0.039.
- BPosterior mean for Beta(1, 1) is 0.03.
- CPosterior mean for Beta(0.5, 0.5) is 0.025.
- DPosterior mean for Beta(0.5, 0.5) is 0.034.
- Q5MSQ3 Marks·Choose all correct options
Which of the following are valid kernel functions? Select all that apply.
- A
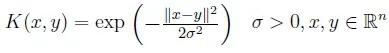
- B
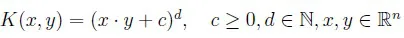
- C
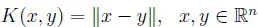
- D
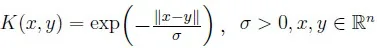
- A
- Q6NAT3 Marks·Write the number
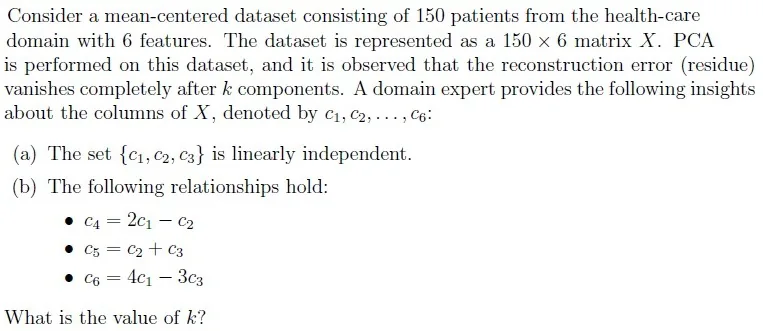 Your answer:
- Q7NAT3 Marks·Write the number
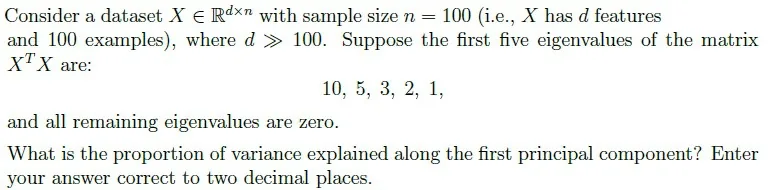 Your answer:
Read the passage below, then answer Q8–Q10
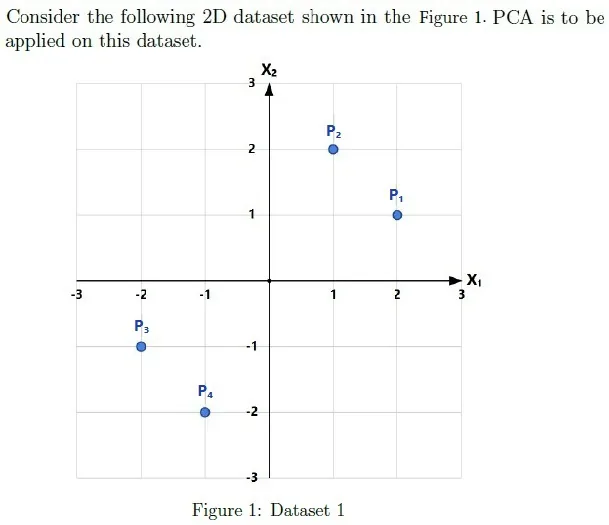
Based on the above data, answer the given subquestions.
Q8MCQ2 Marks·Choose one optionWhat is the covariance matrix of the dataset?
- A

- B

- C

- D

- A
- Q9NAT2 Marks·Write the number
If standard PCA is performed on this dataset, what is the variance along the first principal component? Enter the answer correct to one decimal place.
Your answer: - Q10NAT2 Marks·Write the number
If standard PCA is performed on this dataset, what is the variance along the second principal component? Enter the answer correct to one decimal place.
Your answer: Read the passage below, then answer Q11–Q12
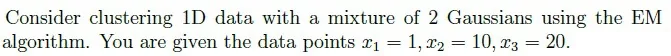
Based on the above data, answer the given subquestions.
Q11MCQ3 Marks·Choose one option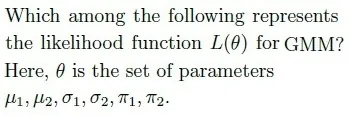
- A
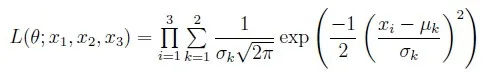
- B
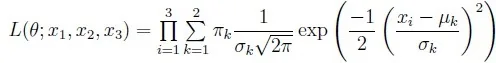
- C
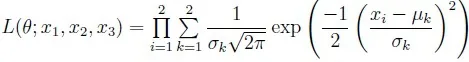
- D
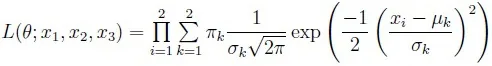
- A
- Q12NAT3 Marks·Write the number
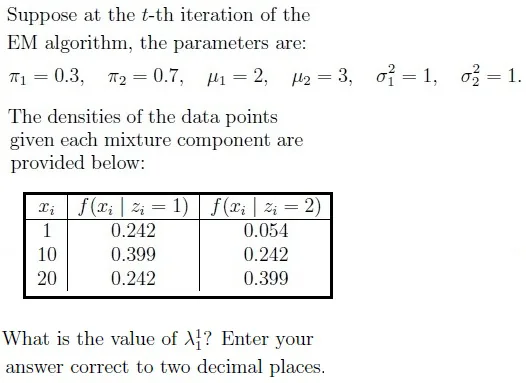 Your answer:
Read the passage below, then answer Q13–Q14
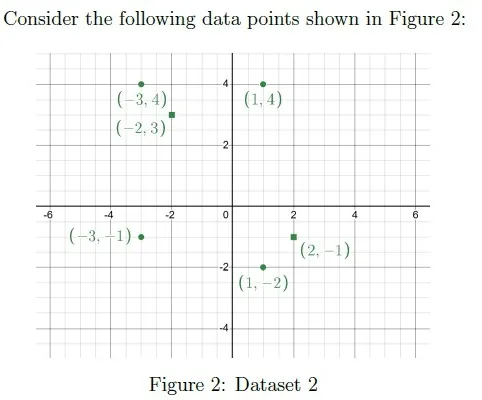
Based on the above data, answer the given subquestions.
Q13MCQ3 Marks·Choose one optionPerform K-means clustering with K = 2 and initial cluster centers at (−2, 3) and (2,−1). What are the final means of clusters after convergence?
- A
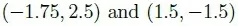
- B
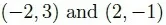
- C
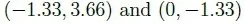
- D
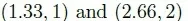
- A
- Q14NAT2 Marks·Write the number
Suppose we introduce a new data point (0, 0) to the existing dataset and perform K means with the same initial cluster centers. How many iterations would it require now for convergence?
Your answer:
End Term · 31 Aug 2025 (FN)End Term
- Q15MCQ3 Marks·Choose one option
- APCA has reduced the dimensionality of the dataset because the combinations of features are de-correlated.
- BPCA has not reduced the dimensionality of the dataset because all principal components are retained.
- CPCA always reduces the dimensionality of the dataset regardless of the number of components retained.
- DPCA can never be used for dimensionality reduction.
- Q16MCQ3 Marks·Choose one option
- A
- B
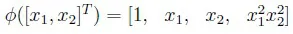
- C
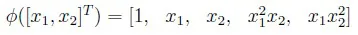
- D
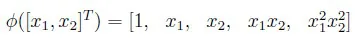
- A
- Q17MCQ4 Marks·Choose one option
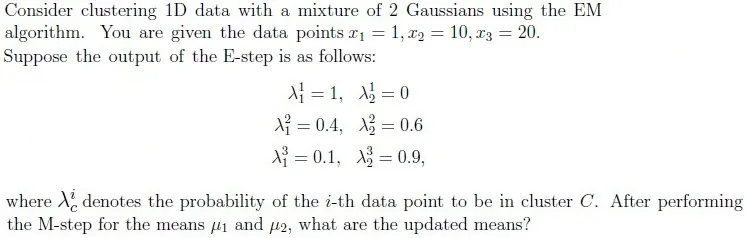
- A
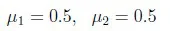
- B
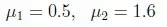
- C
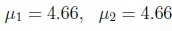
- D
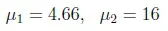
- A
- Q18MCQ2 Marks·Choose one option
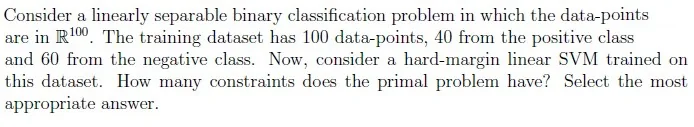
- A40
- B60
- C100
- D1
- Q19MSQ3 Marks·Choose all correct options
Which among the following is TRUE for k-NN algorithm? Select all that apply.
- A1-nearest neighbour is sensitive to outliers.
- Bk-NN can only be applied to a classification problem.
- CAs k increases, the model is more likely to overfit.
- DThe bias increases with the increase in the value of k.
- EThe variance increases with the increase in the value of k.
- Q20MSQ3 Marks·Choose all correct options
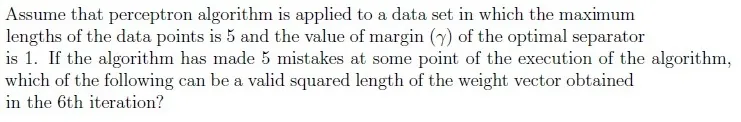
- A30
- B120
- C50
- D160
- Q21MSQ3 Marks·Choose all correct options

- A
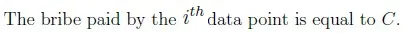
- B
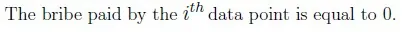
- C
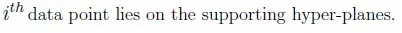
- D
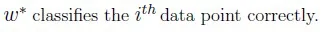
- A
- Q22MSQ2 Marks·Choose all correct options
With respect to the Lloyd’s algorithm, choose the correct statements:
- AThe partition configurations cannot repeat themselves.
- BAfter doing the reassignments (consider at least one point reassigned to the new cluster), we might get the same means for all clusters.
- CObjective function after making the re-assignments strictly reduces.
- DObjective function after making the re-assignments strictly increases.
- Q23NAT3 Marks·Write the number
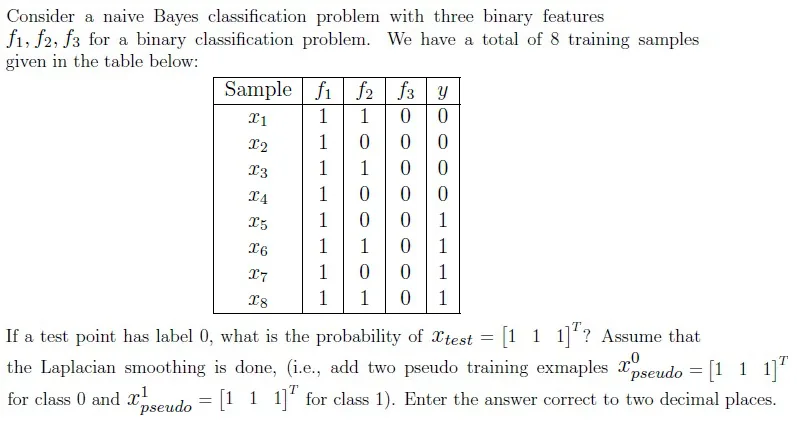 Your answer:
- Q24NAT4 Marks·Write the number
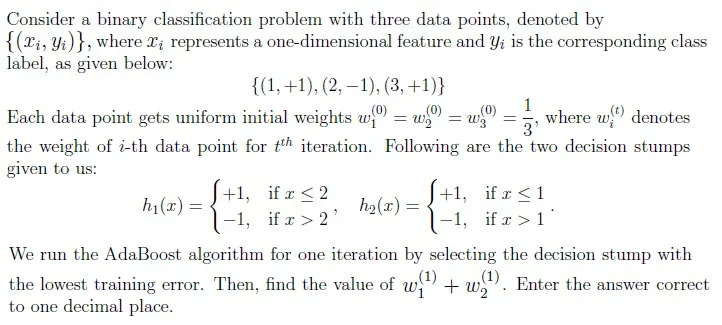 Your answer:
- Q25NAT4 Marks·Write the number
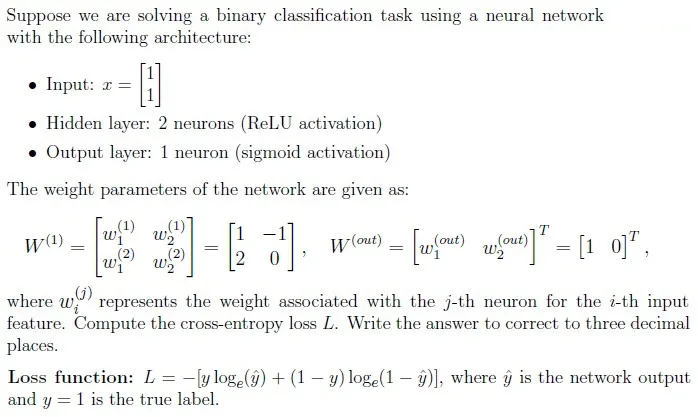 Your answer:
Read the passage below, then answer Q26–Q27
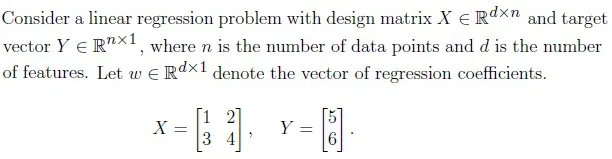
Based on the above data, answer the given subquestions.
Q26MCQ4 Marks·Choose one option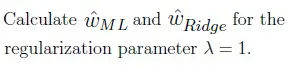
- A
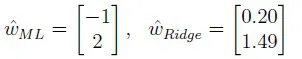
- B
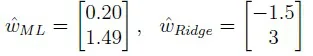
- C
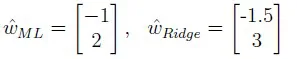
- D
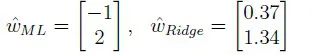
- A
- Q27MCQ2 Marks·Choose one option
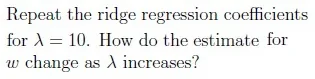
- AThe coefficients shrinks towards zero.
- BThe coefficients increases in magnitude.
- CThe coefficients remain unchanged.
Read the passage below, then answer Q28–Q29
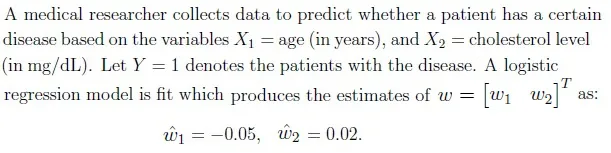
Based on the above data, answer the given subquestions.
Q28NAT3 Marks·Write the numberWhat is the probability that a 60-year-old patient with a cholesterol level of 200 mg/dL has the disease? Enter the answer correct to two decimal places.
Your answer:- Q29NAT3 Marks·Write the number
How high should the cholesterol level be for the patient mentioned in the previous question to have a 50% chance of being diagnosed with the disease?
Your answer: Read the passage below, then answer Q30–Q31
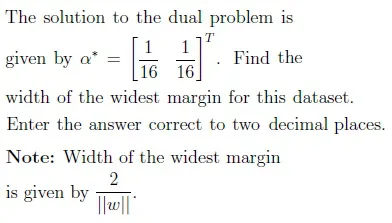
Consider the datapoints (−2,−2) with label +1 and (2, 2) with label −1. A hard margin SVM is applied on this dataset. Answer the given subquestions:
Q30MCQ2 Marks·Choose one optionWhich of the following is the decision boundary for the given dataset?
- A

- B
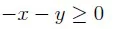
- C

- D
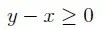
- A
- Q31NAT2 Marks·Write the number
 Your answer:
End Term · 31 Aug 2025 (AN)End Term
- Q32MCQ3 Marks·Choose one option
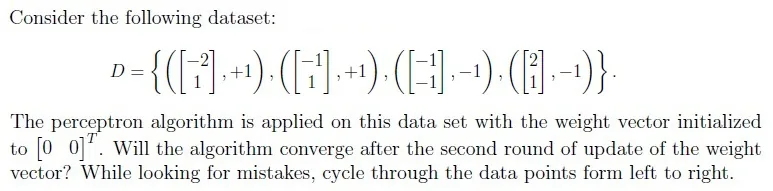
- AYes
- BNo
- Q33MCQ3 Marks·Choose one option
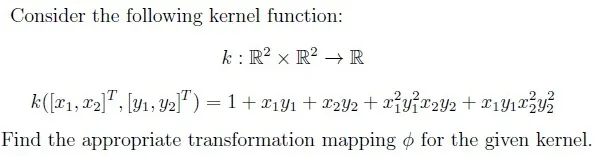
- A
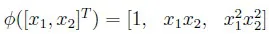
- B
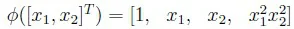
- C
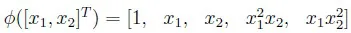
- D
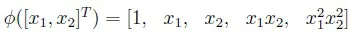
- A
- Q34MCQ2 Marks·Choose one option
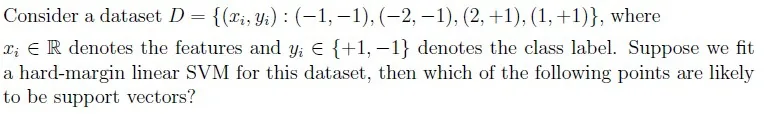
- A
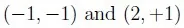
- B
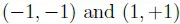
- C
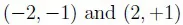
- D
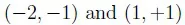
- A
- Q35MCQ2 Marks·Choose one option
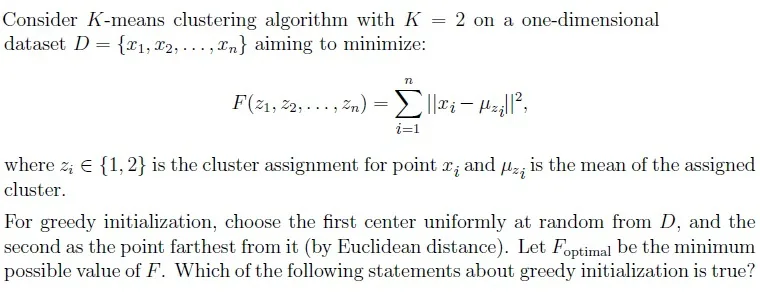
- AGreedy initialization always achieves F = F_(optimal) by maximizing the distance between initial centers.
- BGreedy initialization may achieve F = F_(optimal) or a larger value depending on the dataset and the initial choice.
- CGreedy initialization does not ensure convergence for K-means clustering.
- DGreedy initialization ensures convergence to a unique solution for any dataset.
- Q36MCQ4 Marks·Choose one option
- A
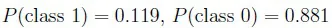
- B
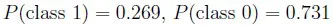
- C
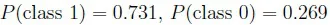
- D
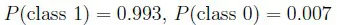
- A
- Q37MSQ3 Marks·Choose all correct options
Which of the following statements are true about the decision tree algorithm?
- ADecision trees are prone to overfitting if the maximum depth is set too shallow.
- BDecision trees are not affected by the order of features in the dataset.
- CDecision trees are sensitive to small perturbations in the dataset and can result in different tree structures.
- DDecision trees can handle both numerical and categorical features.
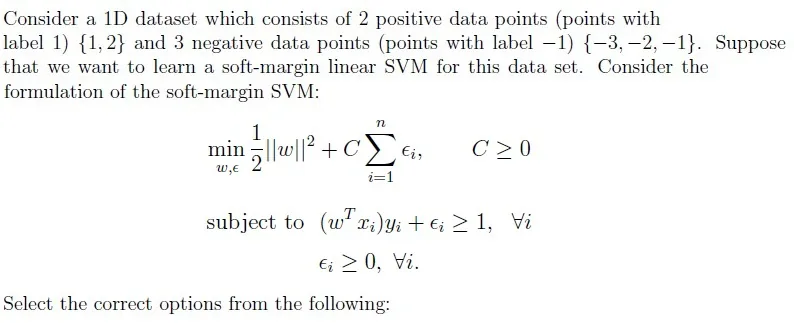
- Q38MSQ3 Marks·Choose all correct options
- A
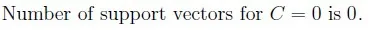
- B
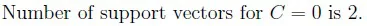
- C
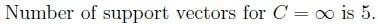
- D
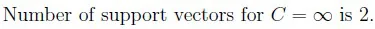
- A
- Q39MSQ3 Marks·Choose all correct options
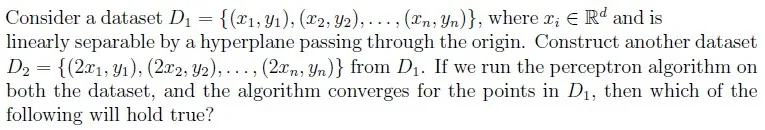
- A
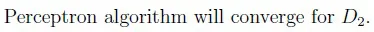
- B
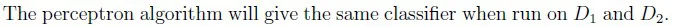
- C
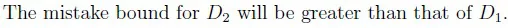
- A
- Q40MSQ4 Marks·Choose all correct options
Given a two-dimensional data set where points from class 1 are: {(−2, 3), (−1, 1)} and points from class 0 are: {(1, 3), (1, 4)}. Which of the following statements are true?
- AThe given data points from classes 1 and 0 can be linearly separated using a hard-margin SVM.
- BA perceptron model and a hard-margin SVM can give different decision boundary for this dataset.
- CA soft-margin SVM would be a more robust choice than a hard-margin SVM for this dataset as the dataset is not linearly separable.
- DThe width of the separation between the two supporting hyperplanes is 4.
- Q41NAT3 Marks·Write the number
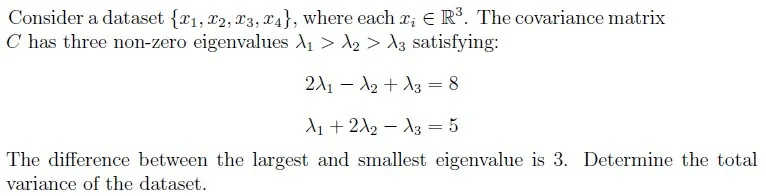 Your answer:
- Q42NAT3 Marks·Write the number
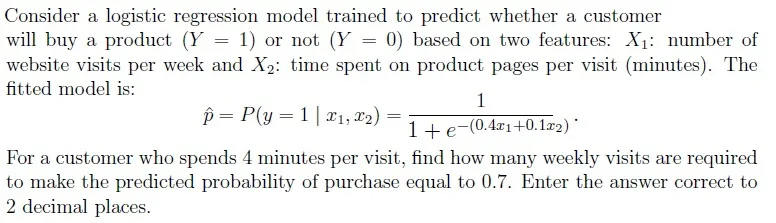 Your answer:
- Q43NAT3 Marks·Write the number
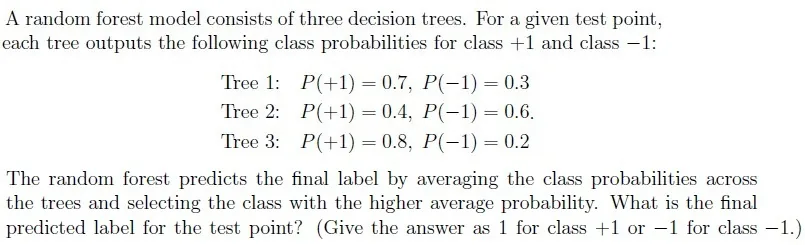 Your answer:
- Q44NAT4 Marks·Write the number
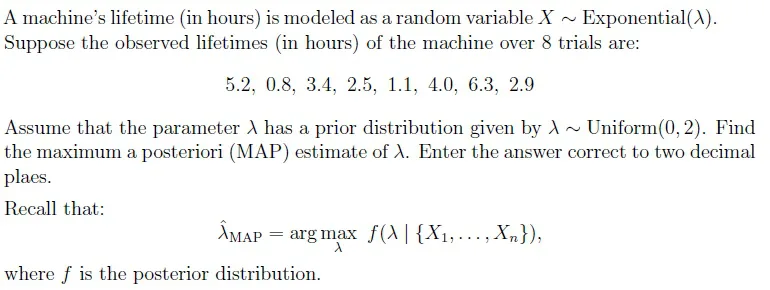 Your answer:
Read the passage below, then answer Q45–Q46
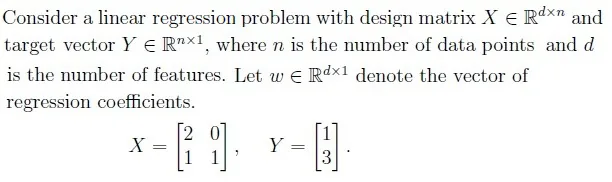
Based on the above data, answer the given subquestions.
Q45MCQ4 Marks·Choose one option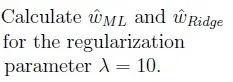
- A
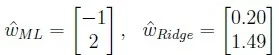
- B
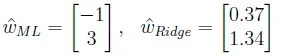
- C
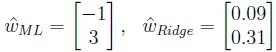
- D
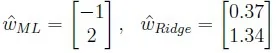
- A
- Q46MCQ2 Marks·Choose one option
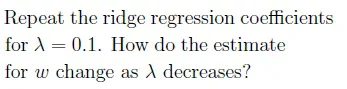
- AThe coefficients shrinks towards zero.
- BThe coefficients increases in magnitude.
- CThe coefficients remain unchanged.
Read the passage below, then answer Q47–Q48
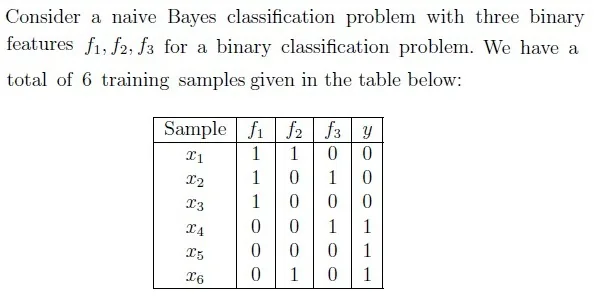
Based on the above data, answer the given subquestions.
Q47NAT1 Mark·Write the number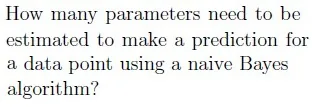 Your answer:
- Q48NAT3 Marks·Write the number
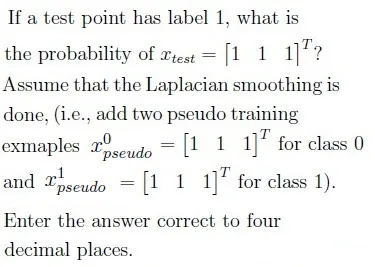 Your answer:
Quiz 2 · 3 Aug 2025 (AN)Quiz 2
- Q49MCQ4 Marks·Choose one option

- A
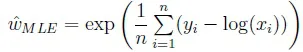
- B
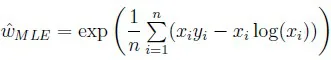
- C
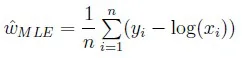
- D
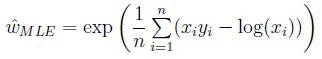
- A
- Q50MCQ3 Marks·Choose one option
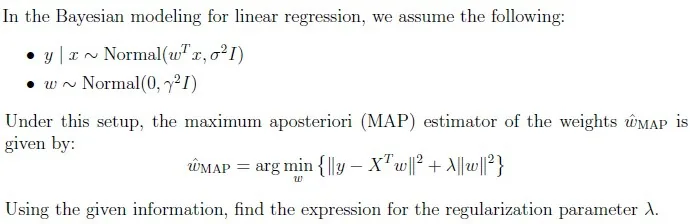
- A
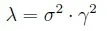
- B

- C

- D
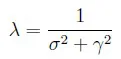
- A
- Q51MCQ3 Marks·Choose one option
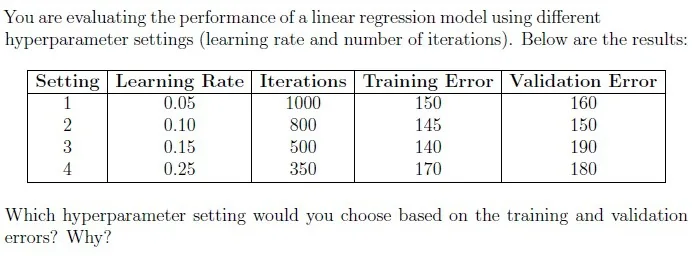
- ASetting 3, because it has the lowest training error, indicating the best fit to the training data.
- BSetting 2, because it has the lowest validation error and a relatively low training error, indicating a good generalization.
- CSetting 1, because it has the highest number of iterations and therefore likely to be more stable.
- DSetting 4, because it uses the highest learning rate and converges the fastest.
- Q52MCQ3 Marks·Choose one option
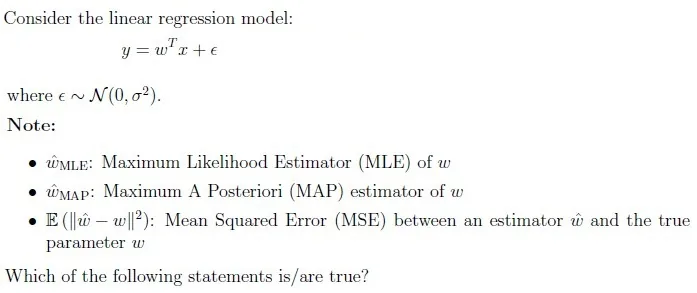
- A
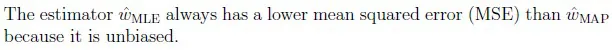
- B
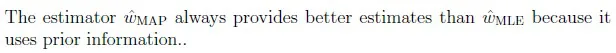
- C
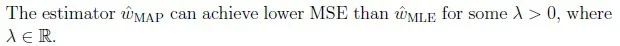
- D
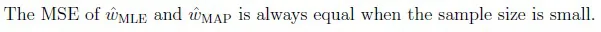
- A
- Q53MCQ2 Marks·Choose one option
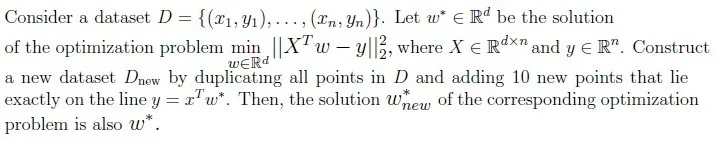
- ATRUE
- BFALSE
- Q54MCQ1 Mark·Choose one option
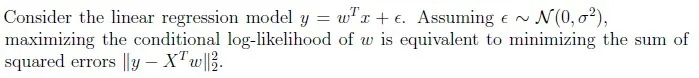
- ATRUE
- BFALSE
- Q55MSQ2 Marks·Choose all correct options

- A
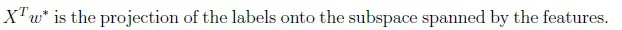
- B
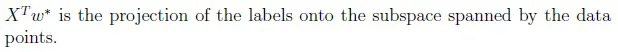
- C
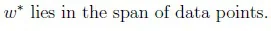
- D
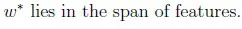
- A
- Q56MSQ2 Marks·Choose all correct options
Which among the following are true?
- A
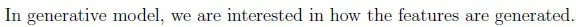
- B
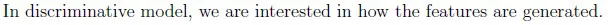
- C
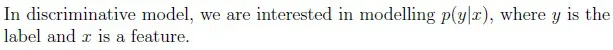
- D
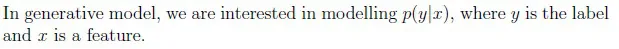
- E
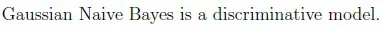
- A
- Q57NAT3 Marks·Write the number
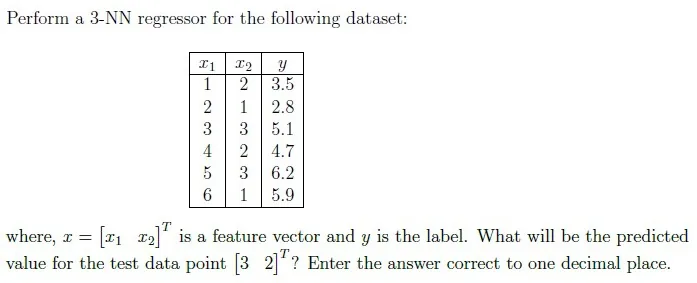 Your answer:
Read the passage below, then answer Q58–Q59
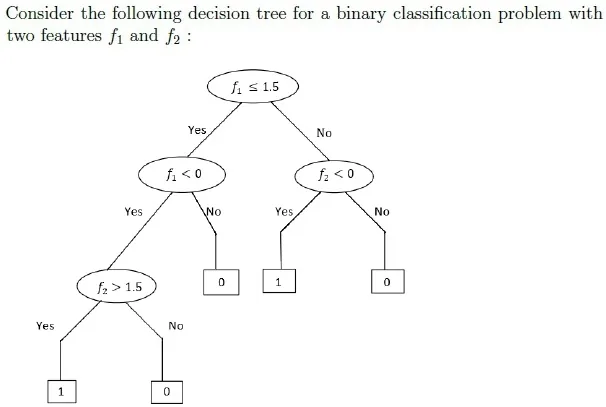
Based on the above data, answer the given subquestions.
Q58MCQ3 Marks·Choose one optionWhich among the following represents the correct decision boundary for the decision tree? Note: Here + represents the label 1 and − represents the label 0.
- A
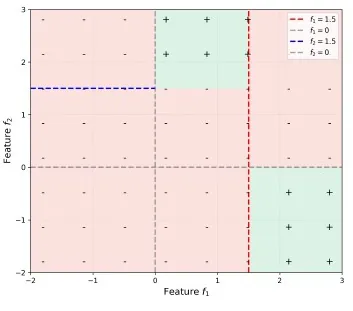
- B
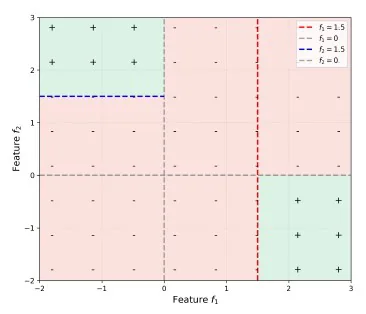
- C
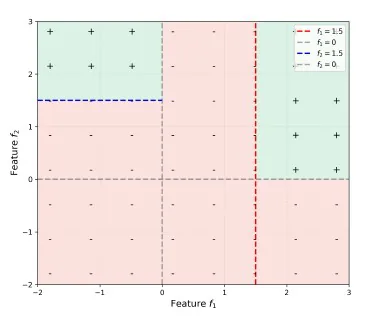
- D
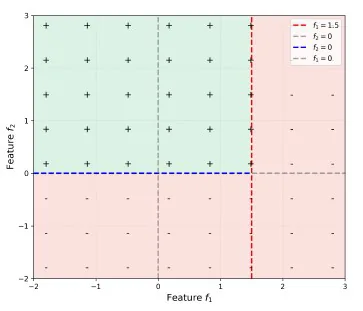
- A
- Q59NAT2 Marks·Write the number
What will be the prediction for the new datapoint (2, 2)?
Your answer: Read the passage below, then answer Q60–Q61
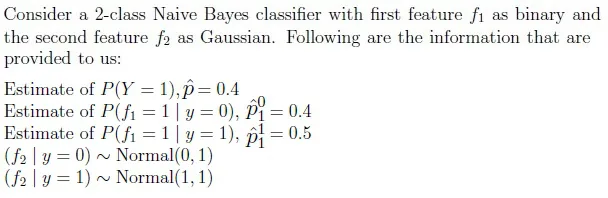
Based on the above data, answer the given subquestions.
Q60NAT2 Marks·Write the number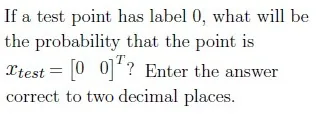 Your answer:
- Q61NAT3 Marks·Write the number
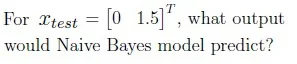 Your answer:
Read the passage below, then answer Q62–Q63
Suppose you want to build a decision tree to help diagnose a certain disease based on patient data. You have a dataset of 1000 patients labeled as either “positive” or “negative”. Here, positive represents patients with the disease and negative represents no disease. One of the feature used to diagnose is headache.
Below is the breakdown of the patients reporting headache:
Headache present: 300 positive, 50 negative
Headache not present: 100 positive, 550 negative
Based on the above data, answer the given subquestions.
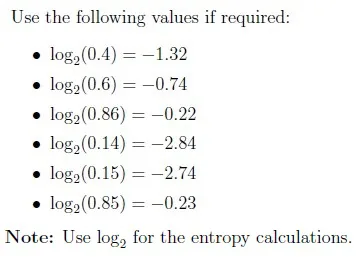
Q62NAT3 Marks·Write the numberWhat is the entropy of the root node? Enter the answer correct to two decimal places.
Your answer:- Q63NAT4 Marks·Write the number
What is the information gain for choosing the feature “headache” for splitting at the root node? Enter the answer correct to two decimal places.
Your answer:
End Term · 13 Apr 2025 (FN)End Term
- Q64MCQ3 Marks·Choose one option
For a given dataset, a 1-Nearest Neighbor (1-NN) and a 3-Nearest Neighbor (3-NN) classifier are applied. Which classifier is likely to exhibit a higher Leave-One-Out Cross Validation (LOOCV) error? In case of tie-breaker, assign a positive class (+) to the data point.
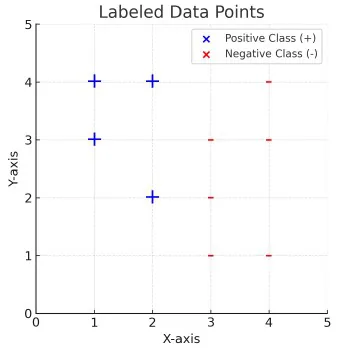
- A1-NN
- B3-NN
- CBoth have the same error.
- Q65MCQ3 Marks·Choose one option
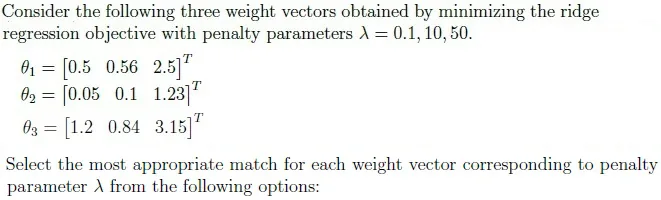
- A
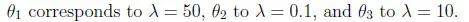
- B
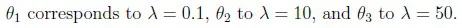
- C
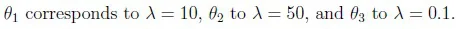
- A
- Q66MCQ4 Marks·Choose one option
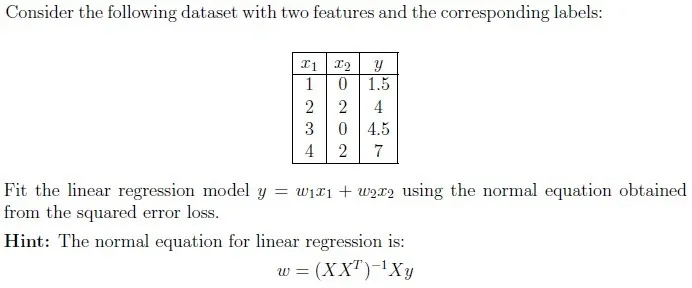
- A
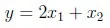
- B
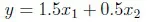
- C
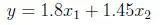
- D
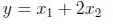
- A
- Q67MCQ4 Marks·Choose one option
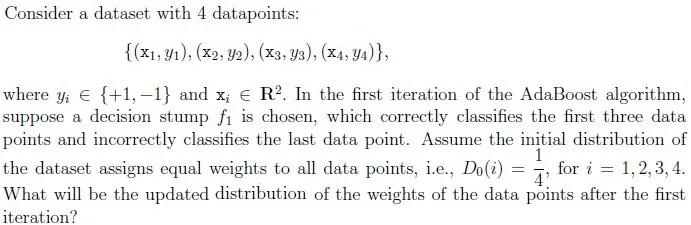
- A
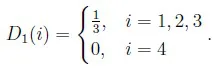
- B
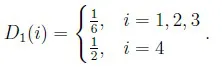
- C
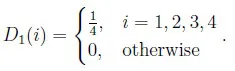
- D
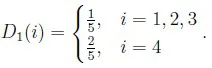
- A
- Q68MSQ3 Marks·Choose all correct options
Which of the following statements correctly differentiates PCA and Kernel PCA?
- APCA maximizes variance in the original feature space, while Kernel PCA maximizes variance in a higher-dimensional transformed space.
- BPCA finds principal components using linear transformations in the original space, while Kernel PCA uses non-linear transformations to find principal components in a higher- dimensional space.
- CKernel PCA can capture non-linear patterns in data, making it useful when PCA fails to represent complex structures in a linear space.
- DPCA and Kernel PCA always yield identical results regardless of the dataset structure.
- Q69MSQ3 Marks·Choose all correct options
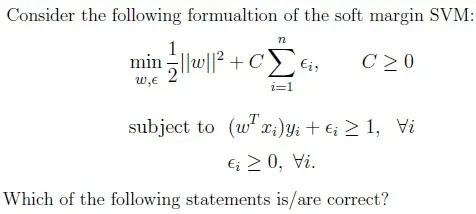
- A
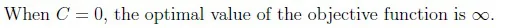
- B
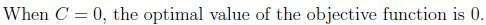
- C
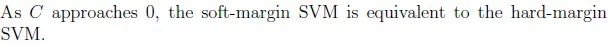
- D
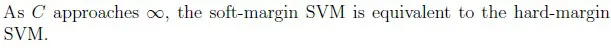
- E
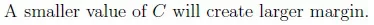
- A
- Q70MSQ2 Marks·Choose all correct options
Which of the following statements are true for bagging?
- AThe final model has lesser variance than the individual learners.
- BThe final model has a higher variance than the individual learners.
- CEstimators in bagging can be trained parallely.
- DIf the number of data points is large, typically two-third of the data points remain unselected in bags.
- Q71MSQ2 Marks·Choose all correct options
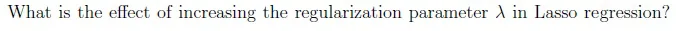
- AIt penalizes large coefficients to reduce overfitting.
- BIt shrinks the coefficients but does not set them to zero.
- CIt forces more coefficients to be exactly zero, performing feature selection.
- DIt has no effect on the regression model.
- Q72NAT2 Marks·Write the number
For a decision tree, each node has exactly two child nodes (balanced tree). If the tree has a depth of 3, how many leaf nodes are there?
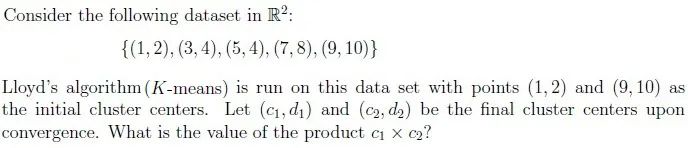
Your answer: - Q73NAT3 Marks·Write the number
 Your answer:
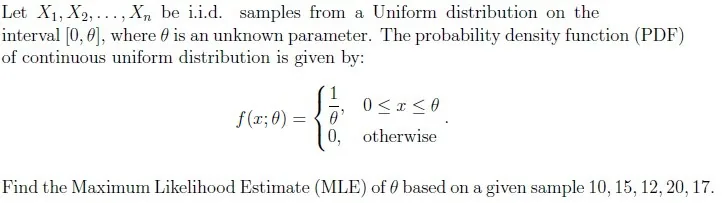
- Q74NAT3 Marks·Write the number
 Your answer:
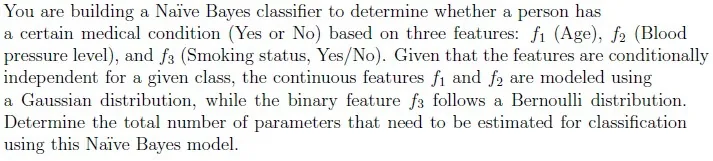
- Q75NAT3 Marks·Write the number
 Your answer:
Read the passage below, then answer Q76–Q77
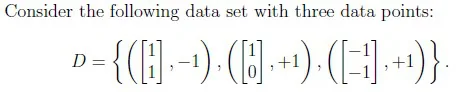
Based on the above data, answer the given subquestions.
Q76NAT3 Marks·Write the number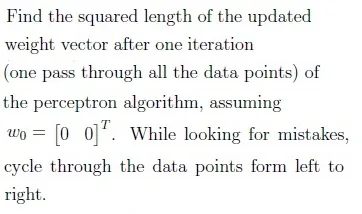 Your answer:
- Q77MCQ2 Marks·Choose one option
Will the algorithm converge after this update?
- AYES
- BNO
Read the passage below, then answer Q78–Q79
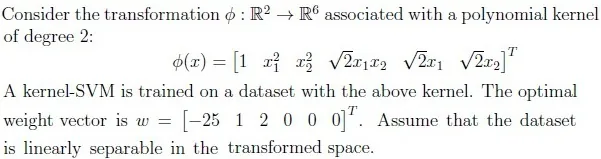
Based on the above data, answer the given subquestions.
Q78MCQ2 Marks·Choose one option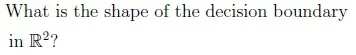
- AIt is a circle.
- BIt is a straight line.
- CIt is an ellipse.
- DIt is a parabola.
- Q79MSQ3 Marks·Choose all correct options
Which of the following training data points are certainly not support vectors?
- A

- B

- C

- D

- A
Read the passage below, then answer Q80–Q81
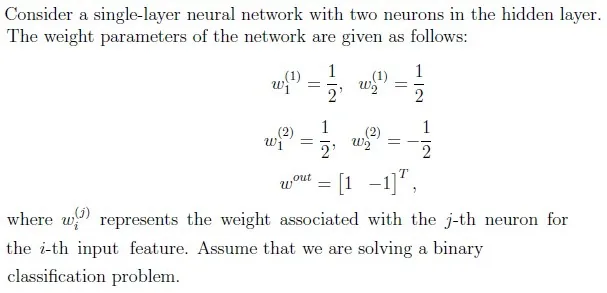
Based on the above data, answer the given subquestions.
Q80NAT3 Marks·Write the number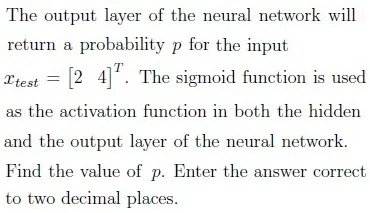 Your answer:
- Q81NAT2 Marks·Write the number
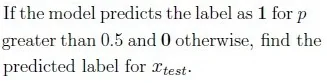 Your answer:
End Term · 13 Apr 2025 (AN)End Term
- Q82MSQ2 Marks·Choose all correct options
What is the role of the regularization term in ridge regression?
- AIt ensures that the dataset is normally distributed.
- BIt penalizes large coefficients to reduce overfitting.
- CIt forces more coefficients to be exactly zero, performing feature selection.
- DIt increases the variance of the model.
- Q83MSQ2 Marks·Choose all correct options
Which of the following conditions must be satisfied for a decision tree to be pure at a given node?
- AThe entropy of the node is maximum.
- BThe information gain at the node is negative.
- CAll samples at a node belong to the same class.
- DThe entropy of the node is 0.
- Q84MCQ3 Marks·Choose one option
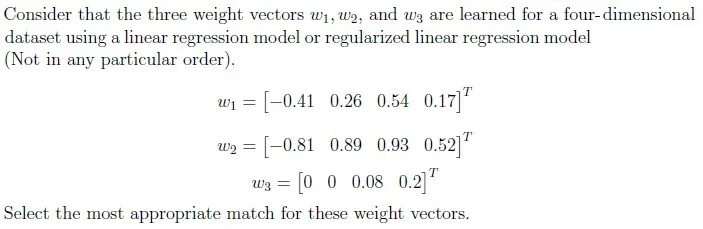
- A
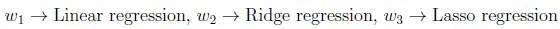
- B
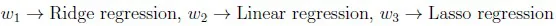
- C
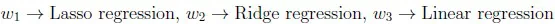
- D
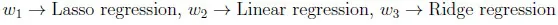
- A
- Q85MCQ3 Marks·Choose one option
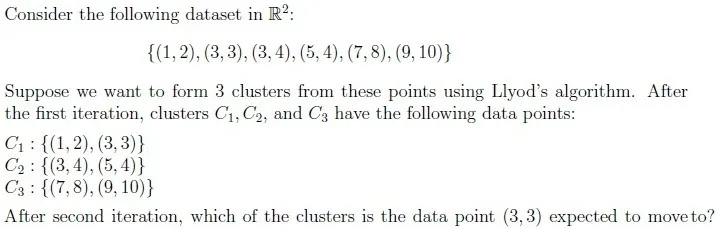
- A

- B

- C

- A
- Q86MCQ2 Marks·Choose one option
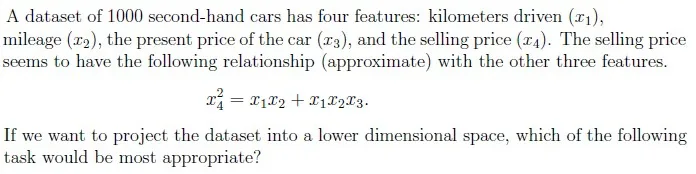
- AKernel PCA with a polynomial kernel of degree 2.
- BKernel PCA with a polynomial kernel of degree 3.
- CKernel PCA with a polynomial kernel of degree 4.
- DStandard PCA
- Q87MCQ1 Mark·Choose one option
Weak learners used in the ensemble method typically perform slightly better than random guessing.
- ATRUE
- BFALSE
- Q88MSQ3 Marks·Choose all correct options
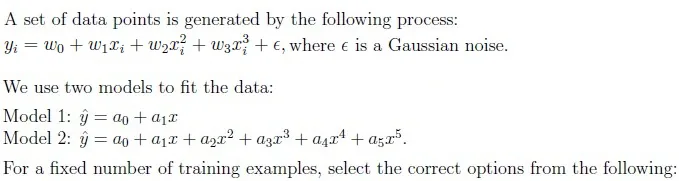
- AModel 1 will have a higher bias than Model 2.
- BModel 2 will have a lower variance than Model 1.
- CModel 1 is more likely to underfit.
- DModel 1 is more likely to overfit.
- Q89MSQ3 Marks·Choose all correct options

- A
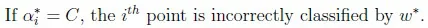
- B
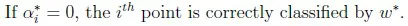
- C
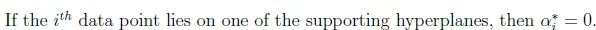
- D
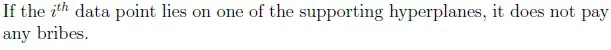
- E
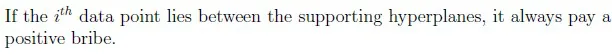
- A
- Q90MSQ4 Marks·Choose all correct options
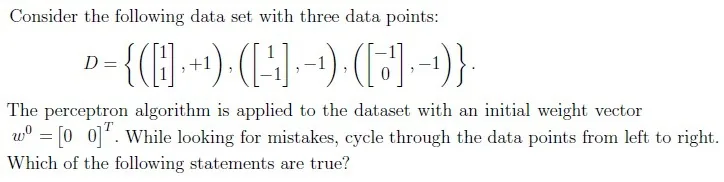
- A
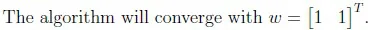
- B
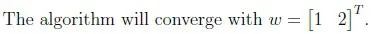
- C
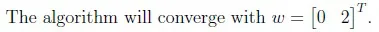
- D
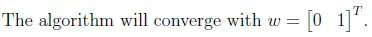
- E
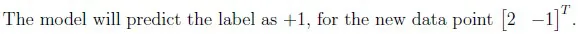
- F
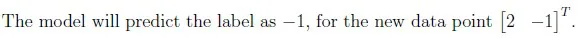
- A
- Q91NAT4 Marks·Write the number
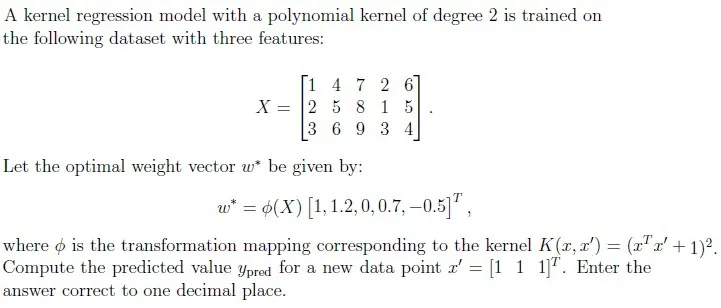 Your answer:
- Q92NAT4 Marks·Write the number
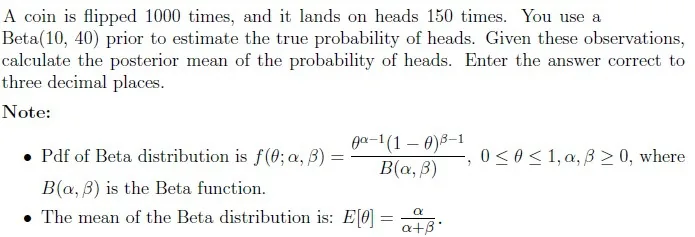 Your answer:
- Q93NAT4 Marks·Write the number
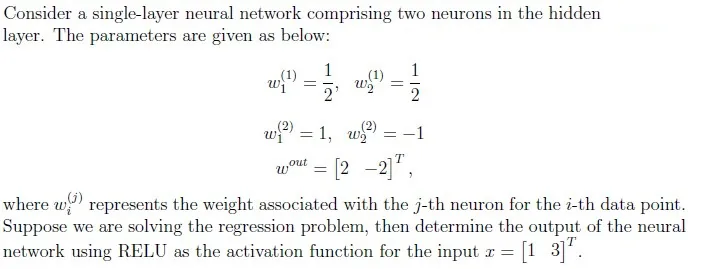 Your answer:
- Q94NAT4 Marks·Write the number
The following dataset represents different weather conditions and the corresponding decision on whether a person chooses to play tennis:
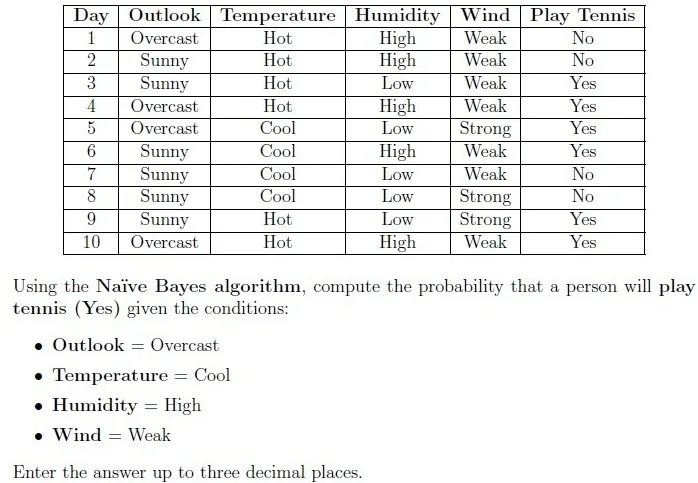 Your answer:
- Q95NAT3 Marks·Write the number
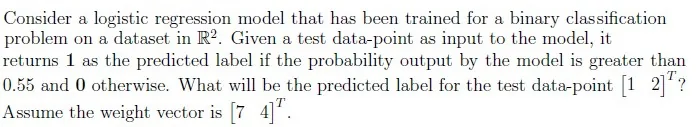 Your answer:
- Q96NAT3 Marks·Write the number
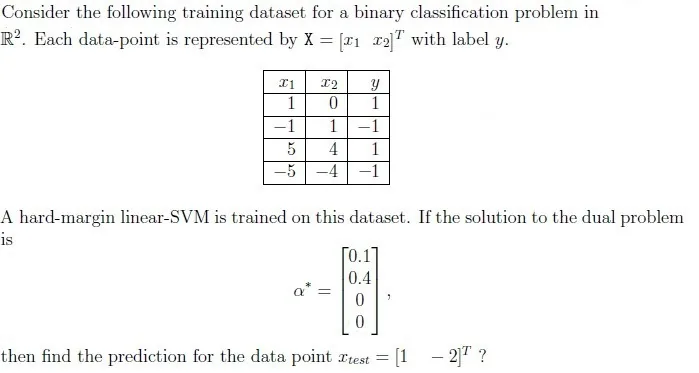 Your answer:
Read the passage below, then answer Q97–Q98
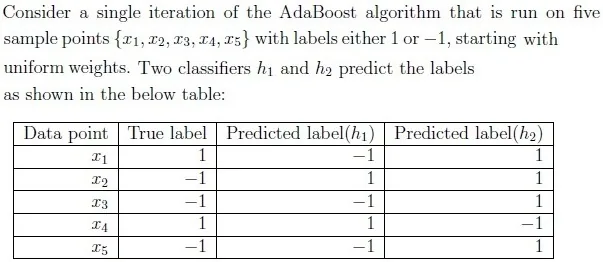
Based on the above data, answer the given subquestions.
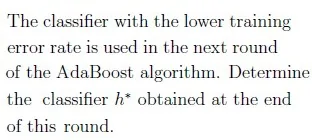
Q97MCQ2 Marks·Choose one optionWhich classifier has the lower training error?
- A

- B

- A
- Q98MCQ3 Marks·Choose one option
- A
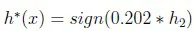
- B
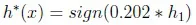
- C
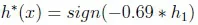
- D
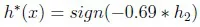
- A
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.