Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Machine Learning Techniques
End Term · 31 Aug 2025 (Afternoon)
Official Paper
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
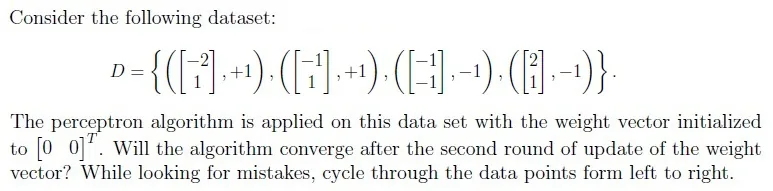
- AYes
- BNo
- Q2MCQ3 Marks·Choose one option
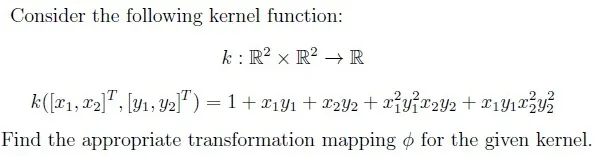
- A
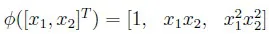
- B
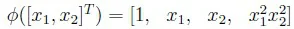
- C
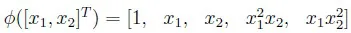
- D
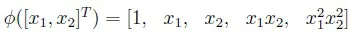
- A
- Q3MCQ2 Marks·Choose one option
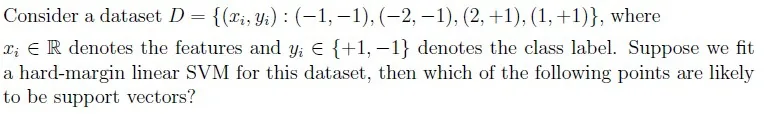
- A
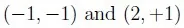
- B
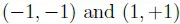
- C
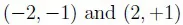
- D
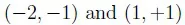
- A
- Q4MCQ2 Marks·Choose one option
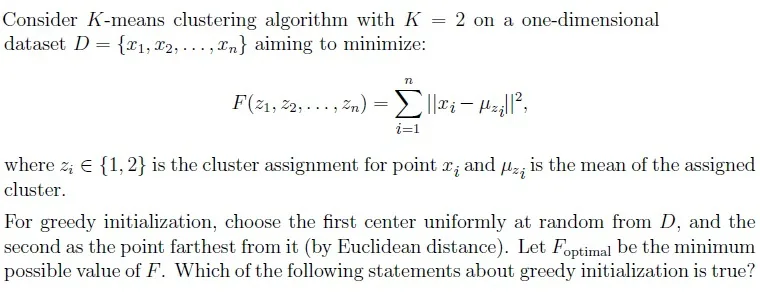
- AGreedy initialization always achieves F = F_(optimal) by maximizing the distance between initial centers.
- BGreedy initialization may achieve F = F_(optimal) or a larger value depending on the dataset and the initial choice.
- CGreedy initialization does not ensure convergence for K-means clustering.
- DGreedy initialization ensures convergence to a unique solution for any dataset.
- Q5MCQ4 Marks·Choose one option
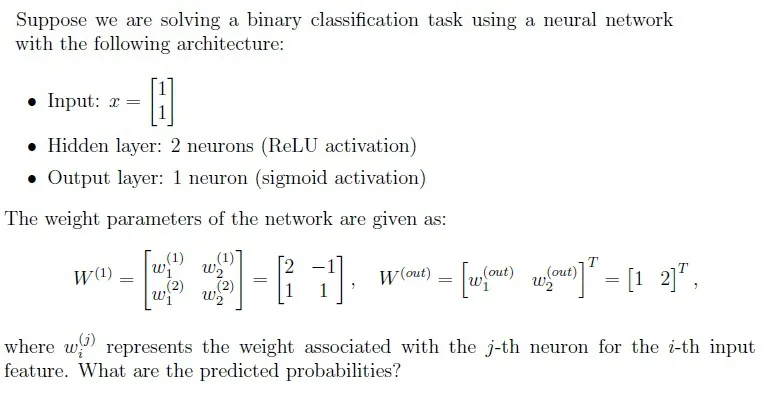
- A
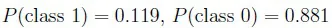
- B
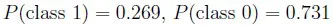
- C
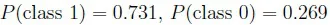
- D
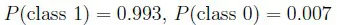
- A
- Q6MSQ3 Marks·Choose all correct options
Which of the following statements are true about the decision tree algorithm?
- ADecision trees are prone to overfitting if the maximum depth is set too shallow.
- BDecision trees are not affected by the order of features in the dataset.
- CDecision trees are sensitive to small perturbations in the dataset and can result in different tree structures.
- DDecision trees can handle both numerical and categorical features.
- Q7MSQ3 Marks·Choose all correct options
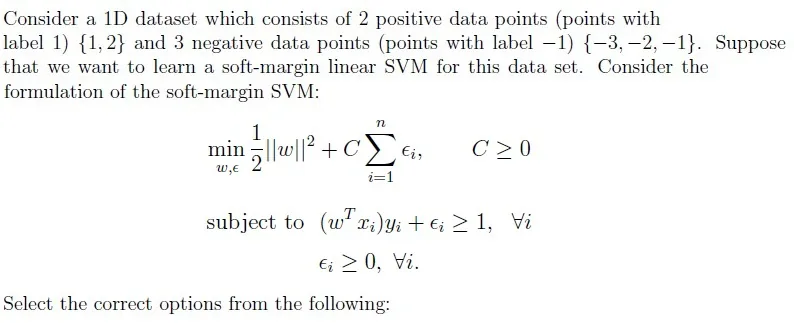
- A
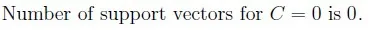
- B
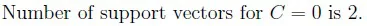
- C
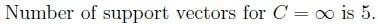
- D
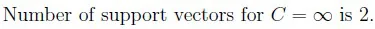
- A
- Q8MSQ3 Marks·Choose all correct options
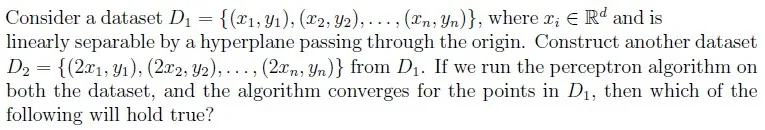
- A
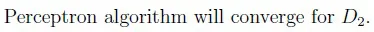
- B
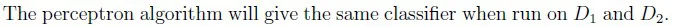
- C
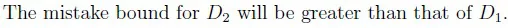
- A
- Q9MSQ4 Marks·Choose all correct options
Given a two-dimensional data set where points from class 1 are: {(−2, 3), (−1, 1)} and points from class 0 are: {(1, 3), (1, 4)}. Which of the following statements are true?
- AThe given data points from classes 1 and 0 can be linearly separated using a hard-margin SVM.
- BA perceptron model and a hard-margin SVM can give different decision boundary for this dataset.
- CA soft-margin SVM would be a more robust choice than a hard-margin SVM for this dataset as the dataset is not linearly separable.
- DThe width of the separation between the two supporting hyperplanes is 4.
- Q10NAT3 Marks·Write the number
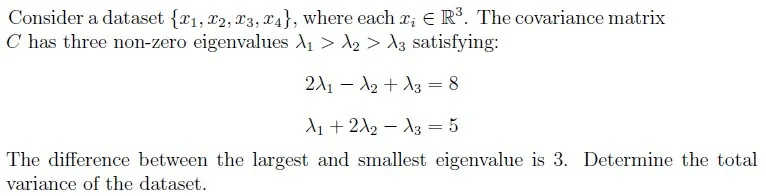 Your answer:
- Q11NAT3 Marks·Write the number
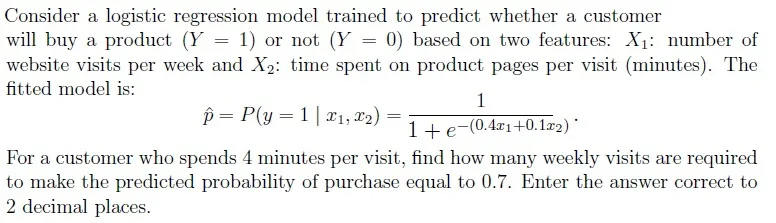 Your answer:
- Q12NAT3 Marks·Write the number
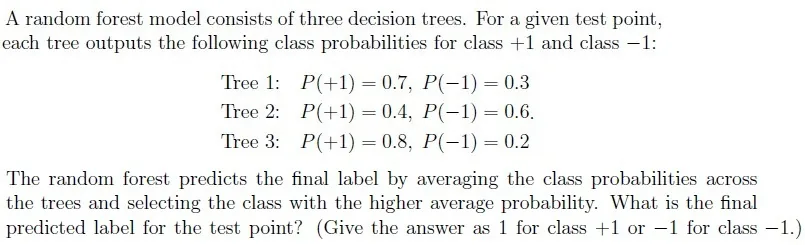 Your answer:
- Q13NAT4 Marks·Write the number
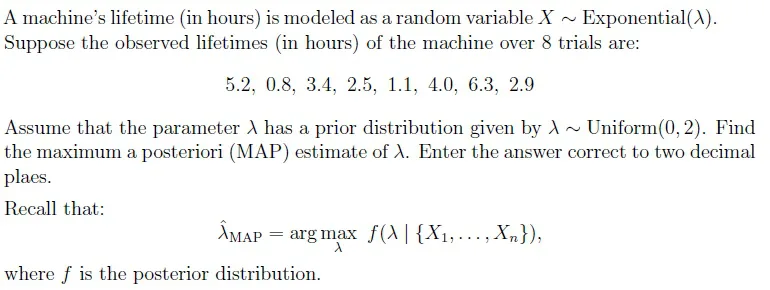 Your answer:
Read the passage below, then answer Q14–Q15
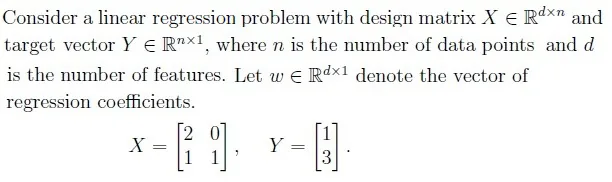
Based on the above data, answer the given subquestions.
Q14MCQ4 Marks·Choose one option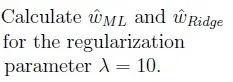
- A
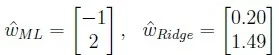
- B
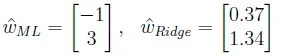
- C
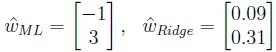
- D
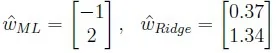
- A
- Q15MCQ2 Marks·Choose one option
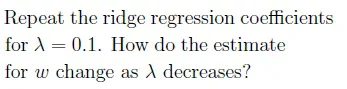
- AThe coefficients shrinks towards zero.
- BThe coefficients increases in magnitude.
- CThe coefficients remain unchanged.
Read the passage below, then answer Q16–Q17
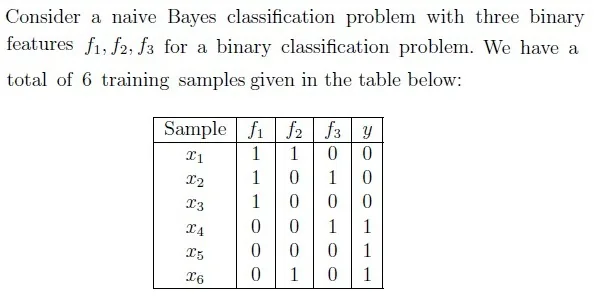
Based on the above data, answer the given subquestions.
Q16NAT1 Mark·Write the number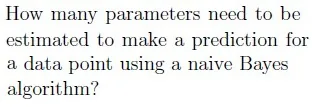 Your answer:
- Q17NAT3 Marks·Write the number
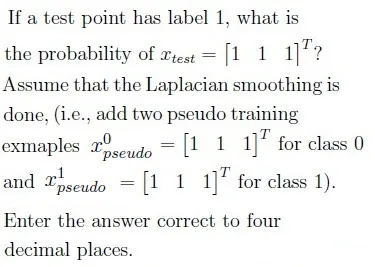 Your answer: