Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Reinforcement Learning
Multi-armed bandits
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
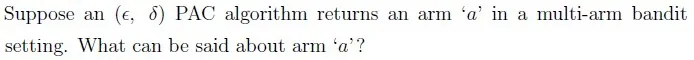
- A
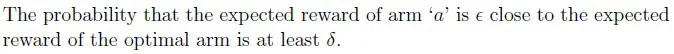
- B
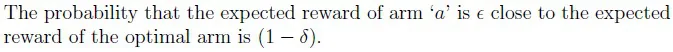
- C
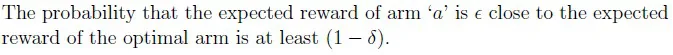
- D
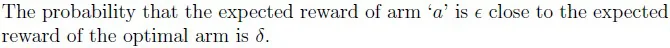
- A
- Q2MCQ3 Marks·Choose one option
Consider following assertion reason pair: Assertion: In the UCB algorithm for multi-armed bandits, replacing the upper confidence bound with a lower confidence bound (and greedily selecting actions based on that lower bound) would still promote effective exploration or lead to optimal reward maximisation. Reason: Even when lower confidence bounds are used instead of upper bounds, if the algorithm greedily selects arms based on these lower bounds, it would still encourage exploration and ultimately achieve optimal reward maximisation.
- ABoth Assertion and Reason are true, and Reason is the correct explanation of Assertion.
- BBoth Assertion and Reason are true, but Reason is NOT the correct explanation of Assertion.
- CAssertion is true, Reason is false
- DAssertion is false, Reason is false
- Q3MCQ2 Marks·Choose one option
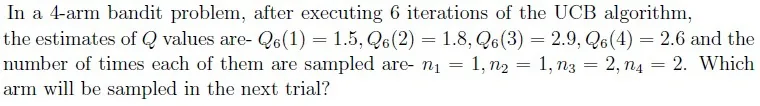
- AArm 1
- BArm 2
- CArm 3
- DArm 4
Read the passage below, then answer Q4–Q5
Suppose you face a 2-armed bandit task where, at each time step, the true action values are either (10, 20) with probability 0.7 (case A) or (90, 80) with probability 0.3 (case B).
Based on the above data, answer the given subquestions.
Q4MCQ1 Mark·Choose one optionIf you cannot observe which case you face, what is the best expected reward per step you can achieve, and what strategy should you follow?
- ARandomly choose between Action 1 and Action 2; expected reward is 3.
- BChoose Action 1 always; expected reward is 34.
- CChoose Action 2 always; expected reward is 38.
- DAlternate between Action 1 and Action 2; expected reward is 40.
- Q5MCQ1 Mark·Choose one option
If, at each time step, you are told whether you face case A or case B (but not the true action values), what is the best expected reward per step you can achieve,and what strategy should you follow?
- APick Action 2 in case A, Action 1 in case B; expected reward is 41.
- BAlways pick Action 2; expected reward is 38.
- CAlways pick Action 1; expected reward is 34.
- DThe expected reward stated in all the given options is incorrect.