Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Large Language Models
Quiz 2 · 3 Aug 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ2 Marks·Choose one option
What is a primary motivation for using subword tokenization (like BPE or WordPiece) instead of word-level tokenization in transformers?
- AIt increases vocabulary size exponentially
- BIt completely eliminates the need for a tokenizer
- CIt helps handle out-of-vocabulary words more effectively
- DIt prevents the model from needing positional encoding
- Q2MCQ2 Marks·Choose one option
What is a key implication of scaling laws in large language models?
- ATraining longer always leads to better performance
- BLarger models require less training data
- CModel size and dataset size must scale together to maintain optimal performance
- DNone of these
- Q3MCQ2 Marks·Choose one option
Consider the Following Assertion and Reason pair : Assertion : In Byte Pair Encoding (BPE), each merge operation adds exactly one new token to the vocabulary. Reason : BPE helps reduce the size of the initial vocabulary by merging the most frequent tokens.
- ABoth Assertion and Reason are true, and Reason is the correct explanation of Assertion.
- BBoth Assertion and Reason are true, but Reason is not the correct explanation of Assertion.
- CAssertion is true, but Reason is false.
- DAssertion is false, but Reason is true.
- Q4MCQ2 Marks·Choose one option
What is the primary advantage of T5’s text-to-text approach for transfer learning in NLP?
- AIt reduces the computational cost of training models significantly.
- BIt allows a single model and architecture to be applied to a wide variety of NLP tasks without modification.
- CIt guarantees optimal performance on all tasks without fine-tuning.
- DIt eliminates the need for any pre-training data.
- Q5MCQ2 Marks·Choose one option
What is the format of output the T5 model is expected to generate during its span-corruption pretraining?
- A
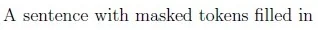
- B
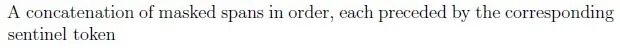
- C
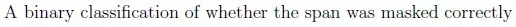
- D
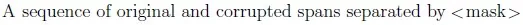
- A
- Q6MCQ3 Marks·Choose one option
- A
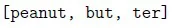
- B
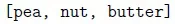
- C
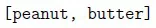
- D
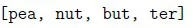
- A
- Q7MCQ3 Marks·Choose one option
Suppose you are given 4x more compute budget to scale a Transformer-based language model. According to scaling laws, what is the best way to utilize this increased compute for optimal model performance?
- AIncrease the model size (number of parameters) by 4x and keep the dataset size and training steps the same.
- BTrain the same model on 4x more data for 4x more steps without changing the model size.
- CIncrease the model size by approximately 2x and increase the amount of training data by approximately 2x.
- DDouble the model size and halve the training data size to compensate.
- Q8MSQ3 Marks·Choose all correct options
In a data preprocessing stage designed to prepare clean, diverse, and safe data, which of the following examples is likely to be filtered out?
- A“All people from that xyz area are thieves. They should be jailed immediately.”
- BKavya’s PAN number is BDZPK1234K and her registered address is 17/4, Green Park, Delhi.
- C[“Reinforcement learning allows agents to learn optimal strategies through interaction with an environment.”, “Reinforcement learning allows agents to learn optimal strategies through interaction with an environment.”]
- DThe Union Budget 2024 proposes increased spending on green energy infrastructure.
- EAccording to WHO, global life expectancy has increased by 6 years since 2000.
- FNone of these.
- Q9MSQ3 Marks·Choose all correct options
What are the key challenges encountered when building a vocabulary for NLP models?
- AA larger vocabulary leads to a bigger embedding matrix and increased softmax computation
- BDifficulty in handling out-of-vocabulary (OOV) words
- CThe size of each embedding vector increases with the number of out-of- vocabulary (OOV) words
- DMore vocabulary entries always guarantee better model generalization
- Q10MSQ3 Marks·Choose all correct options
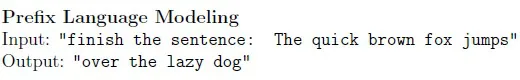
Select all the correct input-output representations used for different pretraining objectives based on the base sentence: “The quick brown fox jumps over the lazy dog”
- A
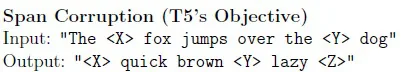
- B
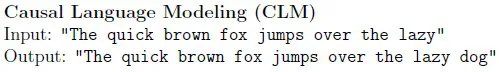
- C
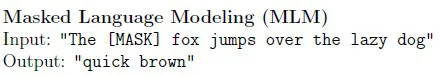
- D
- A
- Q11NAT2 Marks·Write the number
 Your answer:
- Q12NAT3 Marks·Write the number
 Your answer:
Read the passage below, then answer Q13–Q17
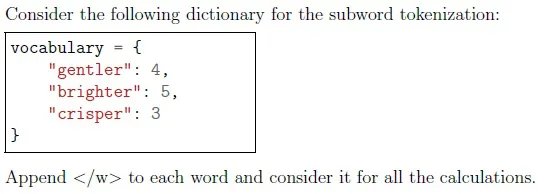
Based on the above data, answer the given subquestions.
Q13NAT2 Marks·Write the numberUsing Byte Pair Encoding (BPE), how many distinct tokens are there in the initial vocabulary before any merges are performed?
Your answer:- Q14MCQ2 Marks·Choose one option
Which token pair has the lowest frequency before any merges in Byte Pair Encoding?
- A(‘b’, ‘r’)
- B(‘t’, ‘l’)
- C(‘p’, ‘e’)
- D(‘e’, ‘r’)
- ENone of these
- Q15NAT2 Marks·Write the number
What is the frequency of the most frequent byte-pair before the first merge in Byte Pair Encoding?
Your answer: - Q16NAT2 Marks·Write the number
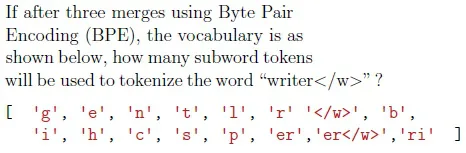 Your answer:
- Q17MCQ2 Marks·Choose one option
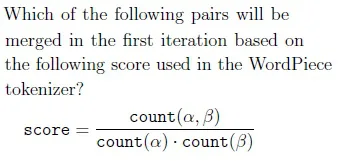
- A

- B
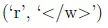
- C

- D

- A