Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Large Language Models
Most repeated questions
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
Type 1 · asked 3 times · Tokenization: BPE, WordPiece & more
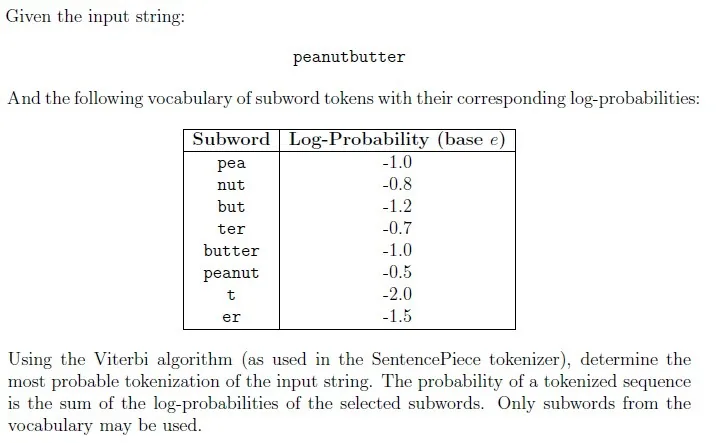
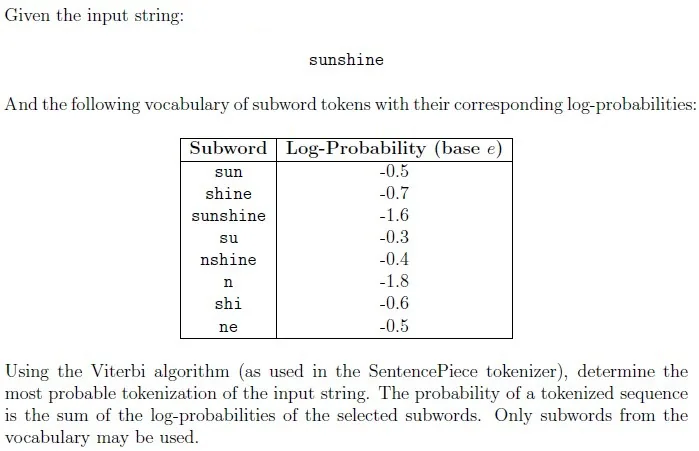
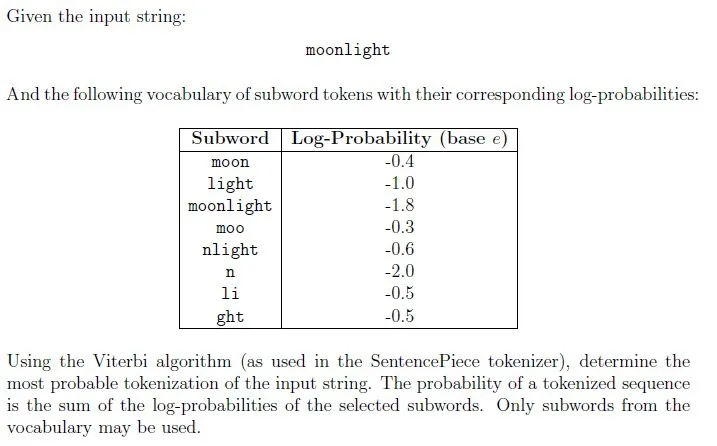
Find the most probable tokenization with Viterbi (SentencePiece)
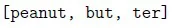
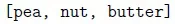
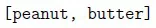
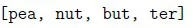

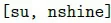
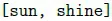
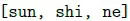
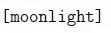
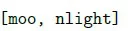
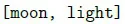
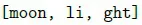
Type 2 · asked 2 times · Tokenization: BPE, WordPiece & more
Why subword tokenizers handle rare/OOV words better
- Q4MCQ2 Marks·Choose one optionQuiz 2 · 3 Aug 2025 (AN)Key ↓
What is a primary motivation for using subword tokenization (like BPE or WordPiece) instead of word-level tokenization in transformers?
- AIt increases vocabulary size exponentially
- BIt completely eliminates the need for a tokenizer
- CIt helps handle out-of-vocabulary words more effectively
- DIt prevents the model from needing positional encoding
- Q5MSQ3 Marks·Choose all correct optionsEnd Term · 31 Aug 2025 (FN)Key ↓
Which of the following statements about subword tokenizers (e.g., Byte Pair Encoding, SentencePiece) is true?
- AThey always split words into individual characters.
- BThey help handle rare words by breaking them into smaller units.
- CThey require the vocabulary to contain every possible word in the language.
- DThey can reduce the overall vocabulary size compared to word-level tokenizers.
Type 3 · asked 2 times · Transformer & self-attention
Apply the causal look-ahead mask to attention scores
- Q6MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
A GPT model is trained using causal language modeling. During training, for a sequence of T = 4 tokens, which of the following correctly represents the attention mask matrix applied to the attention logits?
- A
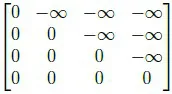
- B
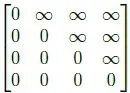
- C

- D

- A
- Q7MCQ2 Marks·Choose one optionQuiz 1 · 26 Oct 2025 (AN)Key ↓
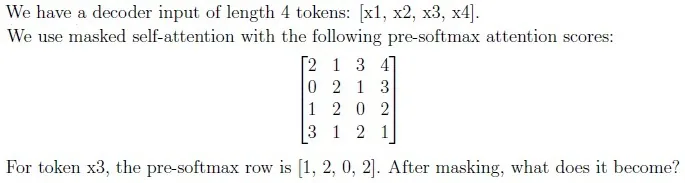
- A

- B

- C
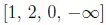
- D
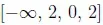
- E
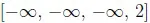
- A
Type 4 · asked 2 times · Efficient & sparse attention
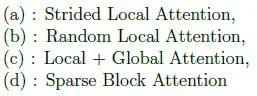
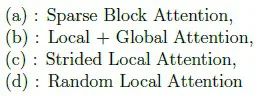
Match attention mask images to sparse attention variants
- Q8MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
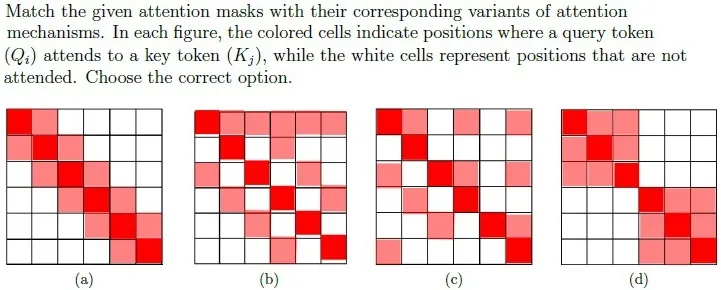
- A(a) : Random Local Attention, (b) : Strided Local Attention, (c) : Sparse Block Attention, (d) : Local + Global Attention
- B(a) : Strided Local Attention, (b) : Local + Global Attention, (c) : Random Local Attention, (d) : Sparse Block Attention
- C(a) : Strided Local Attention, (b) : Random Local Attention, (c) : Local + Global Attention, (d) : Sparse Block Attention
- D(a) : Sparse Block Attention, (b) : Local + Global Attention, (c) : Strided Local Attention, (d) : Random Local Attention
- Q9MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓
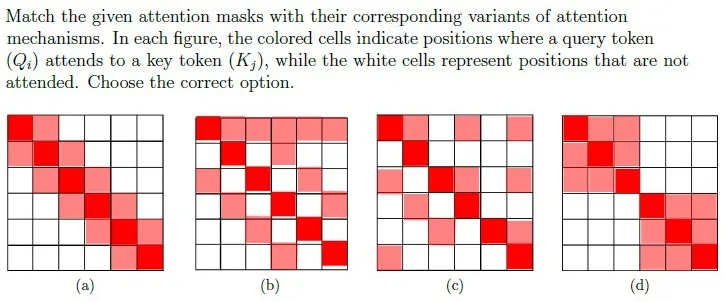
- A
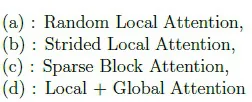
- B
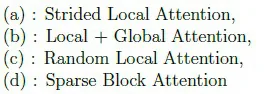
- C
- D
- A
Type 5 · asked 2 times · Pretraining, T5, data & scaling laws
Pick common preprocessing steps for BERT-style models
- Q10MSQ3 Marks·Choose all correct optionsEnd Term · 31 Aug 2025 (AN)Key ↓
Which of the following preprocessing steps are commonly used when preparing data for transformer models like BERT?
- AAdding special tokens such as [CLS] and [SEP] to the sequence
- BSplitting tokens into subword units using a model-specific tokenizer
- CRemoving all punctuation marks to ensure cleaner embeddings
- DAdding positional information to each token embedding
- Q11MSQ3 Marks·Choose all correct optionsEnd Term · 31 Aug 2025 (FN)Key ↓
Which of the following preprocessing steps are commonly required when preparing data for transformer models like BERT?
- ALowercasing text (for uncased models)
- BSplitting into subword units using BPE or WordPiece
- CRemoving all punctuation marks
- DAdding position indices for each token
Type 6 · asked 2 times · Transformer & self-attention
Compute a word's attention output (sum of elements) from given matrices
Read the passage below, then answer Q12
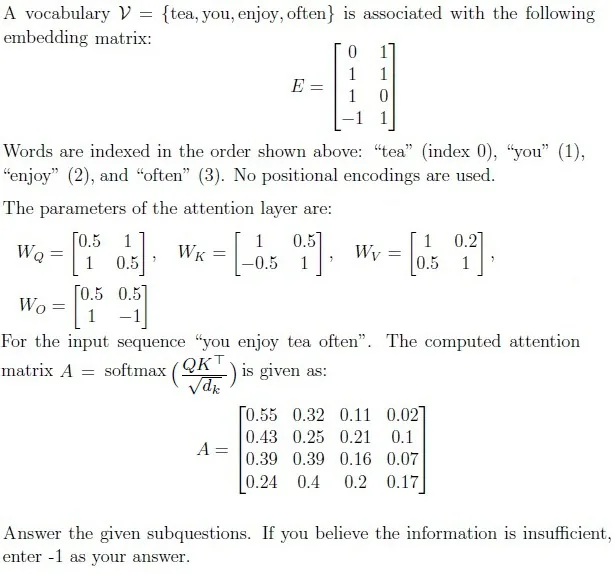 Q12NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓
For the input “you enjoy tea often”, compute the final representation of the word “enjoy” after the attention layer (i.e., after applying W_Q, W_K, W_V , attention weights, and W_O). Enter the sum of the elements in the resulting vector.
Your answer:Read the passage below, then answer Q13
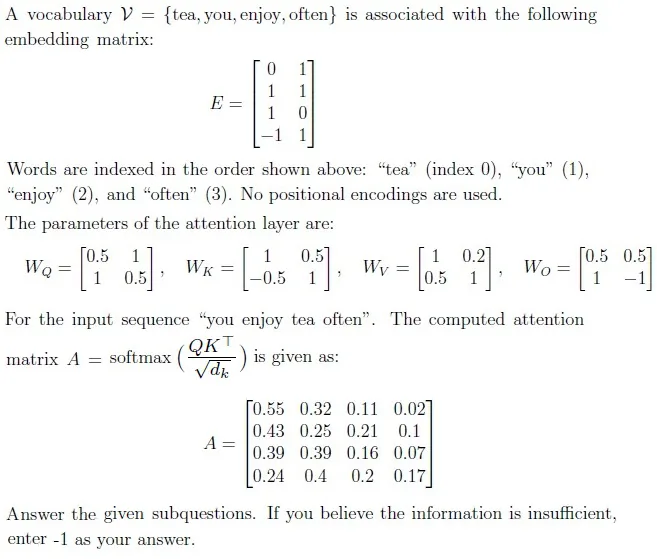 Q13NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓
For the input “you enjoy tea often”, compute the final representation of the word “tea” after the attention layer (i.e., after applying W_Q, W_K, W_V , attention weights, and W_O). Enter the sum of the elements in the resulting vector.
Your answer:
Type 7 · asked 2 times · Transformer & self-attention
Find an attention score after reordering the input sentence
Read the passage below, then answer Q14
Q14NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓Suppose the input sentence is “tea you enjoy often”. Using the same matrices and processing method, what is the attention score (i.e., softmax entry from A) for the query word “tea” attending to key word “often”?
Your answer:Read the passage below, then answer Q15
Q15NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓Suppose the input sentence is “tea you enjoy often”. Using the same matrices and processing method, what is the attention score (i.e., softmax entry from A) for the query word “tea” attending to key word “often”?
Your answer:
Type 8 · asked 2 times · Efficient & sparse attention
Read the block permutation pi from a block attention mask
Read the passage below, then answer Q16
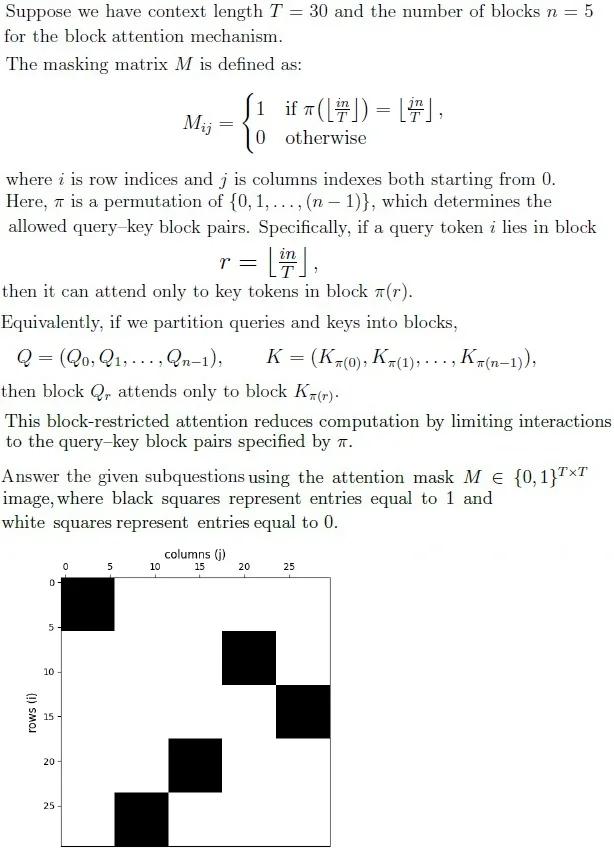
Based on the above data, answer the given subquestions.
Q16MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓Choose the correct representation of π for the given mask image.
- Aπ = (2, 1, 3, 4, 0)
- Bπ = (0, 4, 3, 1, 2)
- Cπ = (0, 3, 4, 2, 1)
- DAll of these
Read the passage below, then answer Q17
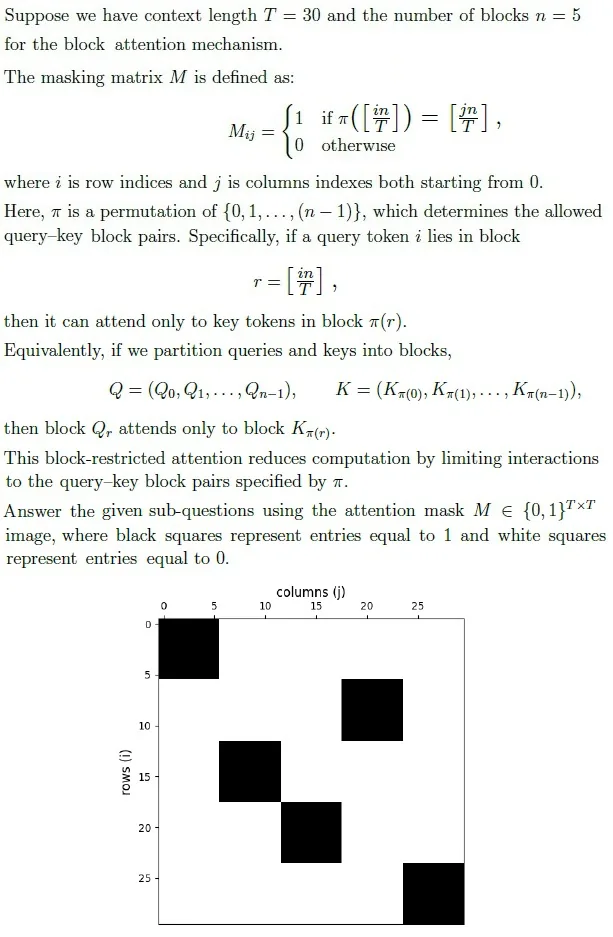 Q17MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓
- A
- B
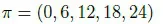
- C
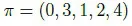
- D
- A
Type 9 · asked 2 times · Efficient & sparse attention
Count permutations of pi for n blocks
Read the passage below, then answer Q18
Based on the above data, answer the given subquestions.
Q18NAT1 Mark·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓How many permutations of π are possible for n = 5?
Your answer:Read the passage below, then answer Q19
Q19NAT1 Mark·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓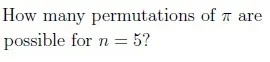 Your answer:
Type 10 · asked 2 times · Efficient & sparse attention
Compute the sparsity percentage of a block attention matrix
Read the passage below, then answer Q20
Based on the above data, answer the given subquestions.
Q20NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓What percentage of entries in the attention matrix are zero (i.e., the sparsity)?
Your answer:Read the passage below, then answer Q21
Q21NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓What percentage of entries in the attention matrix are zero (i.e., the sparsity)?
Your answer:
Type 11 · asked 2 times · Positional encodings: relative & ALiBi
List relative positions j - i for a token
Read the passage below, then answer Q22
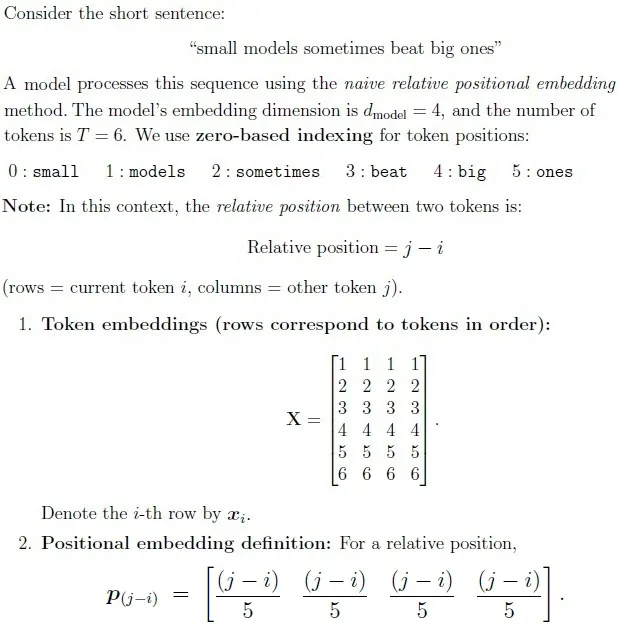
Based on the above data, answer the given subquestions.
Q22MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓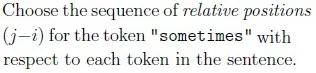
- A(0, 1, 2, 3, 4, 5)
- B(-1, 0, 1, 2, 3, 4)
- C(-3, -2, -1, 0, 1, 2)
- D(-2, -1, 0, 1, 2, 3)
Read the passage below, then answer Q23
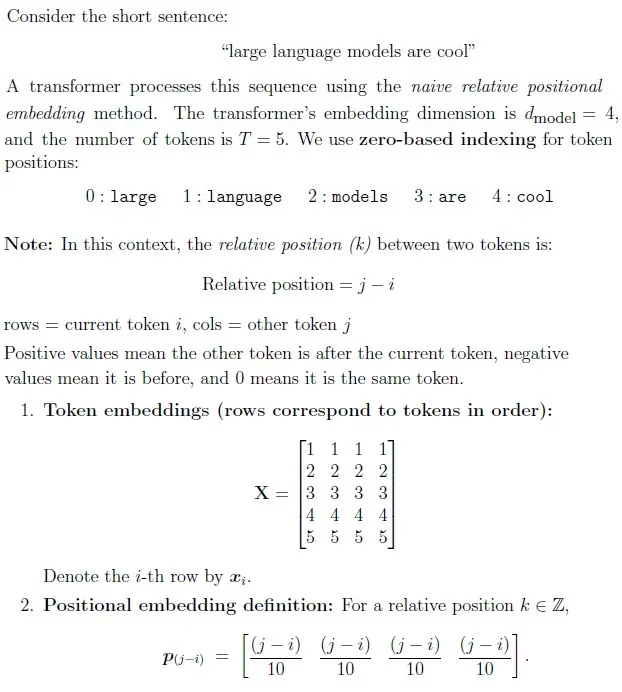
Based on the above data, answer the given subquestions.
Q23MCQ1 Mark·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓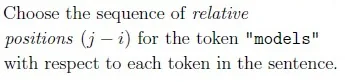
- A(0, 1, 2, 3, 4)
- B(-1, 0, 1, 2, 3)
- C(-2, -1, 0, 1, 2)
- D(-3, -2, -1, 0, 1)
Type 12 · asked 2 times · Positional encodings: relative & ALiBi
Find the naive relative position embedding p(j-i) for a token pair
Read the passage below, then answer Q24
Based on the above data, answer the given subquestions.
Q24MCQ2 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓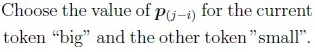
- A[−0.4,−0.4,−0.4,−0.4]
- B[−0.1,−0.1,−0.1,−0.1]
- C[−0.8,−0.8,−0.8,−0.8]
- D[−0.2,−0.2,−0.2,−0.2]
Read the passage below, then answer Q25
Based on the above data, answer the given subquestions.
Q25MCQ1 Mark·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓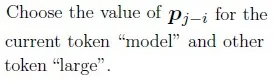
- A
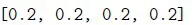
- B
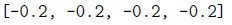
- C
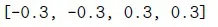
- D
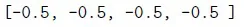
- A
Type 13 · asked 2 times · Positional encodings: relative & ALiBi
Compute the combined embedding h_i with naive relative positions
Read the passage below, then answer Q26
Based on the above data, answer the given subquestions.
Q26NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓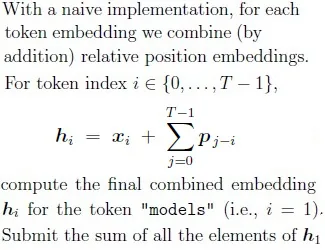 Your answer:
Read the passage below, then answer Q27
Based on the above data, answer the given subquestions.
Q27NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓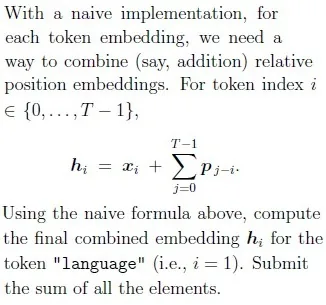 Your answer:
Type 14 · asked 2 times · Positional encodings: relative & ALiBi
Compute the pre-attention score e_ij with relative position embeddings
Read the passage below, then answer Q28
Based on the above data, answer the given subquestions.
Q28NAT2 Marks·Write the numberEnd Term · 31 Aug 2025 (AN)Key ↓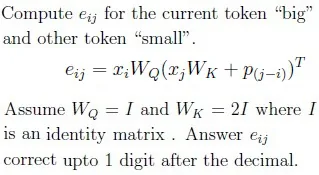 Your answer:
Read the passage below, then answer Q29
Based on the above data, answer the given subquestions.
Q29NAT3 Marks·Write the numberEnd Term · 31 Aug 2025 (FN)Key ↓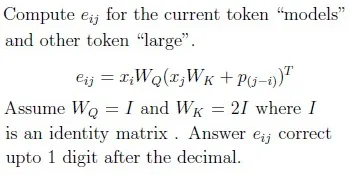 Your answer:
Type 15 · asked 2 times · Decoding strategies & teacher forcing
Identify which decoding strategies are deterministic or random
- Q30MSQ3 Marks·Choose all correct optionsEnd Term · 31 Aug 2025 (FN)Key ↓
A GPT-based model is fine-tuned for story generation. During evaluation, you test different decoding strategies on the same prompt: 1. Method A: Every run produces the exact same story, even when executed multiple times. 2. Method B: The story changes slightly in each run, but overall structure and key events remain similar. 3. Method C: The story is wildly different each time, sometimes even changing the genre. Based on the observations, select the most likely decoding strategies for each method:
- AMethod A: Greedy decoding
- BMethod A: Top-K sampling with K = 50
- CMethod B: Top-P sampling with p = 0.9
- DMethod C: Top-P sampling with p = 0.5 and high temperature T = 1.5
- EMethod C: Beam search with K = 5
- Q31MSQ2 Marks·Choose all correct optionsQuiz 1 · 26 Oct 2025 (AN)Key ↓
Which of the following decoding strategies is/are inherently non-deterministic?
- ABeam
- BGreedy
- CNucleus
- DExhaustive
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.