Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning
Word embeddings (word2vec/CBOW)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
End Term · 31 Aug 2025 (FN)End Term
Read the passage below, then answer Q1–Q3
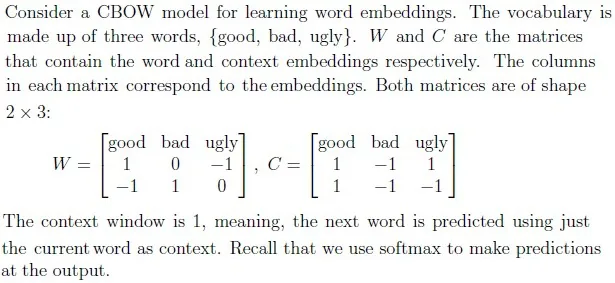
Based on the above data, answer the given subquestions.
Q1NAT2 Marks·Write the number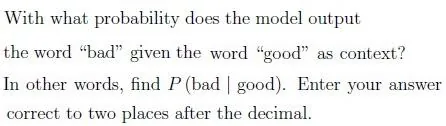 Your answer:
- Q2MCQ2 Marks·Choose one option
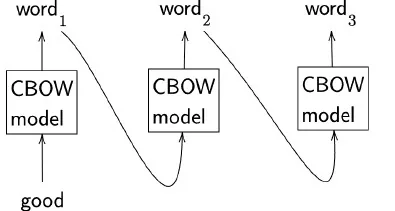
The CBOW model is now used to generate a “sentence” or a string of words. First we pass the word “good” and retain the word with highest probability as the output, say word_1, which is in turn passed as input to the model. If the model is run this way for exactly three time steps, what is the sentence that it outputs? Note that the sentence here is “word_1 word_2 word_3”.
- Abad ugly good
- Bgood bad ugly
- Cbad bad bad
- Dgood good good
- Ebad ugly bad
- Q3MCQ3 Marks·Choose one option
Now consider updating the word embeddings using the sample “good good”. The first “good” in the string is used as context and the second “good” as the true label. Use cross entropy as the loss function and run one iteration of gradient descent with η = 1 starting with the existing values for the embeddings. Find the updated word embedding for “good” and choose the most appropriate option from below. Note that you have to compute the updated word embedding for “good” and not its context embedding.
- A(1.76, -0.24)
- B(1.24, -0.76)
- C(1.76, 1.76)
- D(1.76, -1.76)
- E(1.24, -1.24)
End Term · 31 Aug 2025 (AN)End Term
Read the passage below, then answer Q4–Q6
Consider a CBOW model for learning word embeddings. The vocabulary is made up of three words, {good, bad, ugly}. W and C are the matrices that contain the word and context embeddings respectively. The columns in each matrix correspond to the embeddings. Both matrices are of shape 2 x 3:
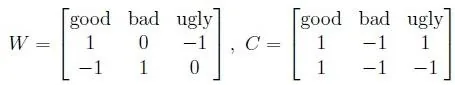
The context window is 1, meaning, the next word is predicted using just the current word as context. Recall that we use softmax to make predictions at the output.
Based on the above data, answer the given subquestions.
Q4NAT2 Marks·Write the number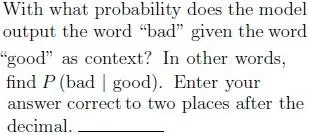 Your answer:
- Q5MCQ2 Marks·Choose one option
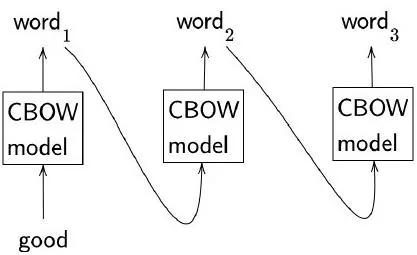
The CBOW model is now used to generate a “sentence” or a string of words. First we pass the word “good” and retain the word with highest probability as the output, say word_1, which is in turn passed as input to the model. If the model is run this way for exactly three time steps, what is the sentence that it outputs? Note that the sentence here is “word_1 word_2 word_3”.
- Abad ugly good
- Bgood bad ugly
- Cbad bad bad
- Dgood good good
- Ebad ugly bad
- Q6MCQ3 Marks·Choose one option
Now consider updating the word embeddings using the sample “good good”. The first “good” in the string is used as context and the second “good” as the true label. Use cross entropy as the loss function and run one iteration of gradient descent with η = 1 starting with the existing values for the embeddings. Find the updated word embedding for “good” and choose the most appropriate option from below. Note that you have to compute the updated word embedding for “good” and not its context embedding.
- A(1.76, -0.24)
- B(1.24, -0.76)
- C(1.76, 1.76)
- D(1.76, -1.76)
- E(1.24, -1.24)
End Term · 13 Apr 2025 (AN)End Term
Read the passage below, then answer Q7–Q8
Based on the above data, answer the given subquestions.
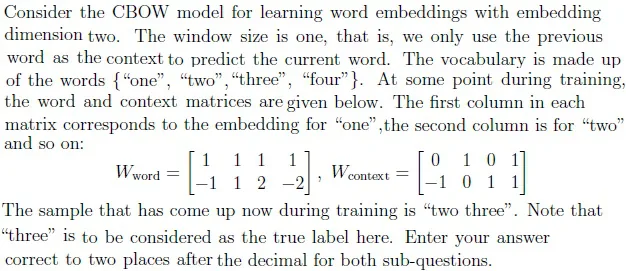
Q7NAT2 Marks·Write the numberFind the probability of predicting “three” given “two” as context.
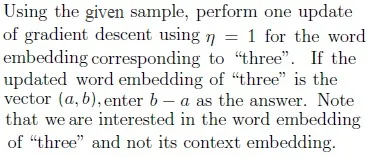
Your answer:- Q8NAT2 Marks·Write the number
 Your answer: