Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning
Quiz 1 · 26 Oct 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
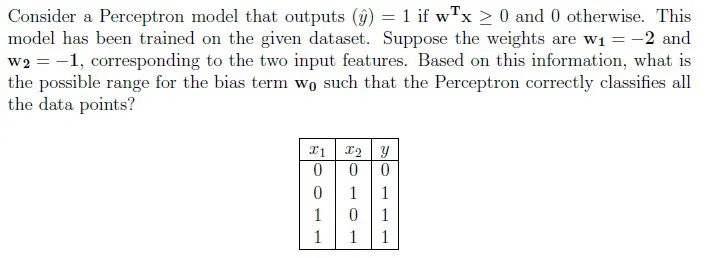
- Q1MCQ4 Marks·Choose one option
- A
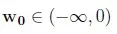
- B
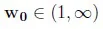
- C

- D

- E
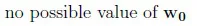
- A
- Q2MCQ3 Marks·Choose one option
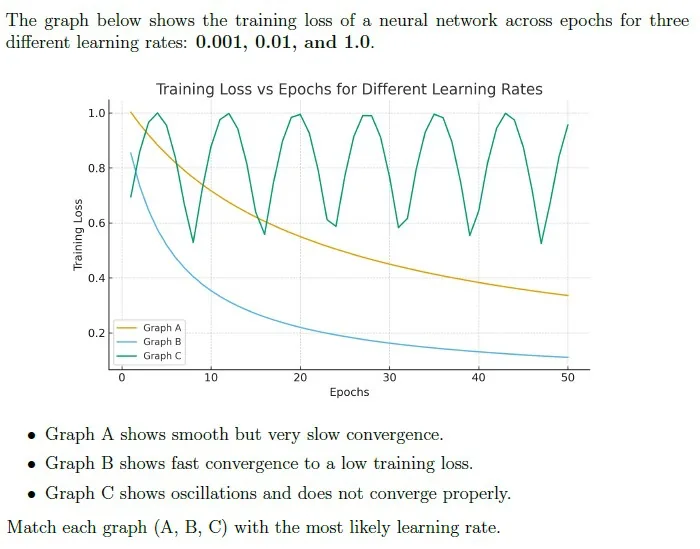
- AA → 0.01 , B → 0.001 , C → 1.0
- BA → 0.001 , B → 0.01 , C → 1.0
- CA → 1.0 , B → 0.001 , C → 0.01
- DA → 0.01 , B → 1.0 , C → 0.001
- Q3MCQ3 Marks·Choose one option
Which of the following statements best describes the primary representational advantage of a Multi-Layer Perceptron (MLP) over a Single-Layer Perceptron (SLP)?
- AAn MLP can learn non-linear decision boundaries, allowing it to classify data that is not linearly separable.
- BAn MLP converges faster than an SLP on linearly separable data because its hidden layers accelerate learning.
- CAn MLP is less prone to overfitting than an SLP because it has more parameters to capture the data distribution.
- DAn MLP can only be used for classification tasks, whereas an SLP can be used for both classification and regression.
- Q4MCQ3 Marks·Choose one option
A data scientist is training a deep learning model on a massive dataset containing billions of data points. They find that using traditional Batch Gradient Descent (GD) is computationally infeasible. What is the primary reason that makes Batch GD impractical for this task, thus requiring an alternative like Stochastic Gradient Descent (SGD)?
- AIt is impossible to fit the entire large dataset into the computer’s memory (RAM) at once.
- BThe gradient calculated by Batch GD is often too noisy and inaccurate, leading to poor convergence.
- CBatch GD is guaranteed to get stuck in sharp local minima, whereas SGD can escape them.
- DBatch GD requires calculating the gradient of the loss function with respect to the parameters over the entire dataset for a single update, which is computationally very expensive.
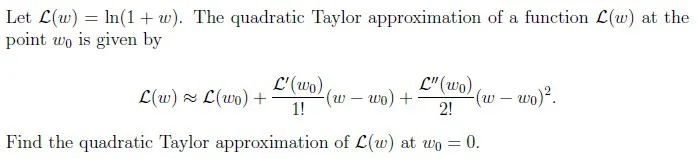
- Q5MCQ3 Marks·Choose one option
- A

- B

- C

- D

- A
- Q6MSQ3 Marks·Choose all correct options
You are adapting a neural network that was originally designed for a 10-class image classification problem to perform a regression task, specifically to predict the price of a car. Which of the following modifications are essential or standard practice for this conversion?
- AChange the activation function of the final output layer to a linear function.
- BSet the number of neurons in the output layer to one.
- CChange the loss function from Categorical Cross-Entropy to Mean Squared Error (MSE).
- DUse accuracy as the primary metric to evaluate the model’s performance.
- EKeep the softmax activation function in the output layer to scale the predicted price.
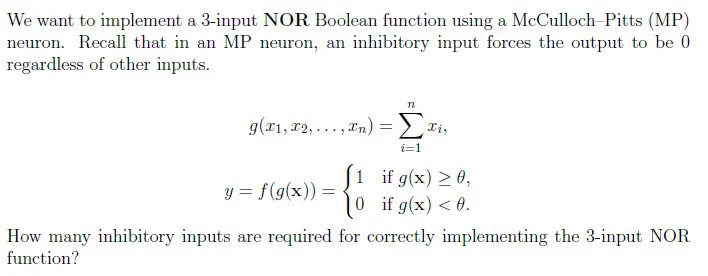
- Q7NAT3 Marks·Write the number
 Your answer:
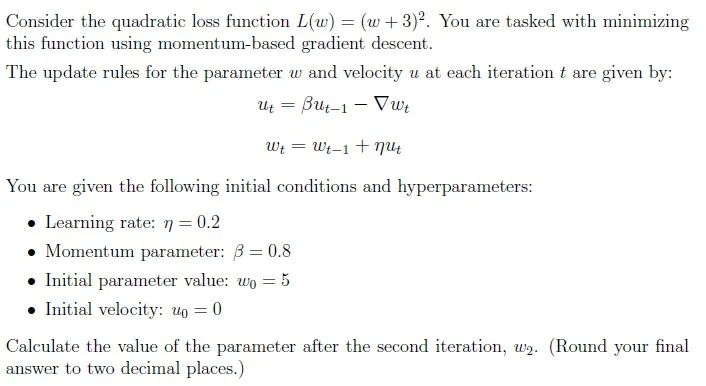
- Q8NAT4 Marks·Write the number
 Your answer:
Read the passage below, then answer Q9–Q12
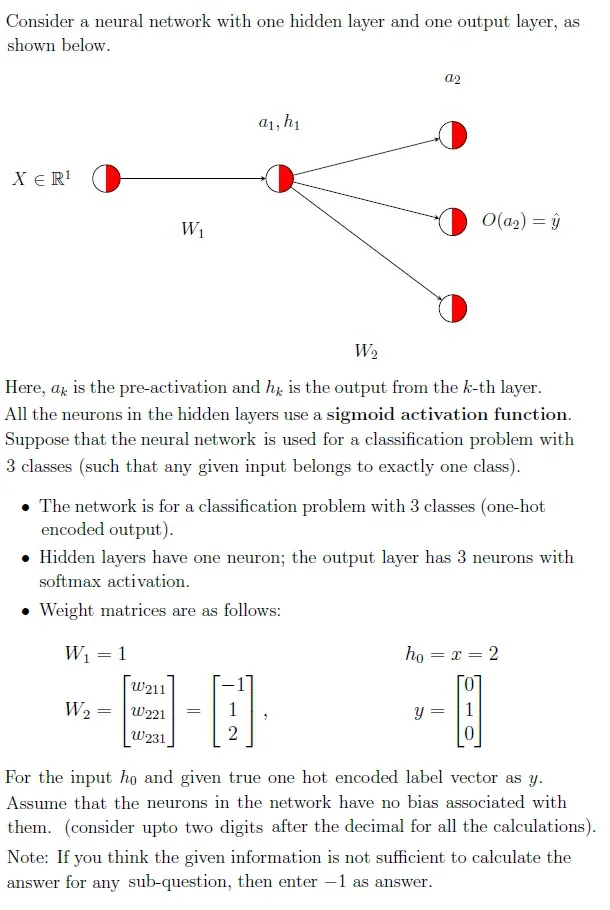
Based on the above data, answer the given subquestions.
Q9NAT1 Mark·Write the numberWhat is the value of the output of the hidden layer? (Answer correct upto two digits after the decimal)
Your answer:- Q10NAT1 Mark·Write the number
What is the value of the cross entropy loss? (use natural log). (Answer correct upto two digits after the decimal)
Your answer: - Q11NAT2 Marks·Write the number
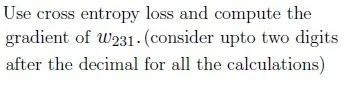 Your answer:
- Q12NAT2 Marks·Write the number
Use cross entropy loss and compute the gradient of W_1 which is the weight between input and hidden layer. (consider upto two digits after the decimal for all the calculations)
Your answer: Read the passage below, then answer Q13–Q16
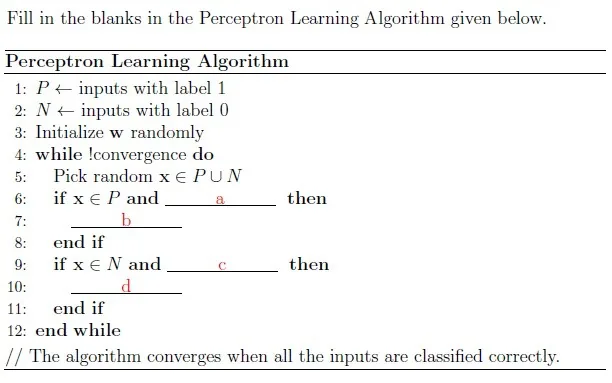
Based on the above data, answer the given subquestions.
Q13MCQ1 Mark·Choose one option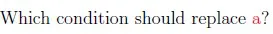
- A
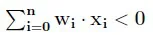
- B
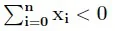
- C
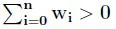
- D
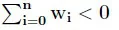
- A
- Q14MCQ1 Mark·Choose one option
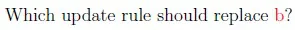
- A
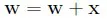
- B
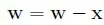
- C
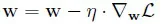
- D
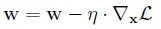
- A
- Q15MCQ1 Mark·Choose one option
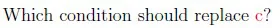
- A
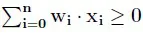
- B
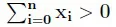
- C
- D
- A
- Q16MCQ1 Mark·Choose one option
- A
- B
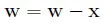
- C
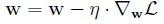
- D
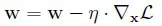
- A
Read the passage below, then answer Q17–Q18
Suppose you build a neural network with one hidden layer that uses sigmoid as an activation function and an output layer with a softmax activation function. You initialize the hidden layer weights W_1 randomly and set the output layer weights W_2 to all zeros. Assume the bias is set to be zero. You train the network using stochastic gradient descent.
Based on the above data, answer the given subquestions.
Q17MCQ2 Marks·Choose one optionAfter one iteration of gradient descent, will the new weight for W_1 be the same as the previous weight?
- AYes
- BNo
- Q18MCQ2 Marks·Choose one option
After one iteration of gradient descent, will the new weight for W_2 be the same as the previous weight?
- AYes
- BNo