Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning Practice
Quiz 2 · 3 Aug 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
In a speaker diarization pipeline that uses Whisper for transcription and an embedding model for speaker identification,you observe that one speaker's segments are consistently broken into multiple smaller segments, each assigned a different speaker label (e.g., SPEAKER 1, SPEAKER 3, SPEAKER 5). The transcribed text for this speaker is perfectly accurate. What is the MOST likely cause of this specific issue?
- A

- B

- C
- D

- A
- Q2MCQ3 Marks·Choose one option
- A
- B

- C

- D
- A
- Q3MSQ5 Marks·Choose all correct options
Which statements accurately describe the roles and differences of the data collators used in the ASR and TTS training scripts?
- A

- B

- C

- D

- E

- A
- Q4MSQ5 Marks·Choose all correct options

- A

- B

- C

- D

- E

- A
- Q5NAT5 Marks·Write the number
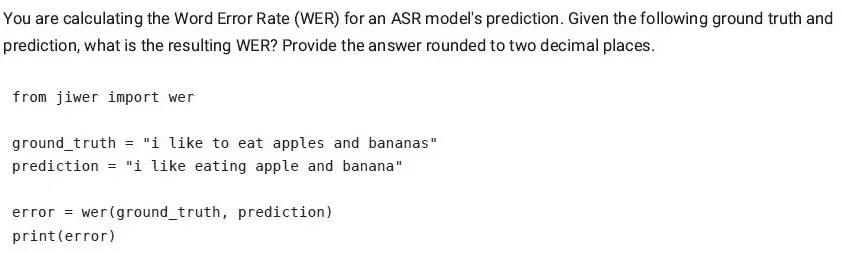 Your answer:
- Q6NAT5 Marks·Write the number
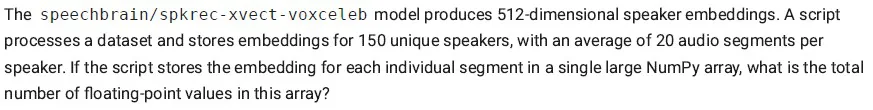 Your answer:
Read the passage below, then answer Q7–Q9
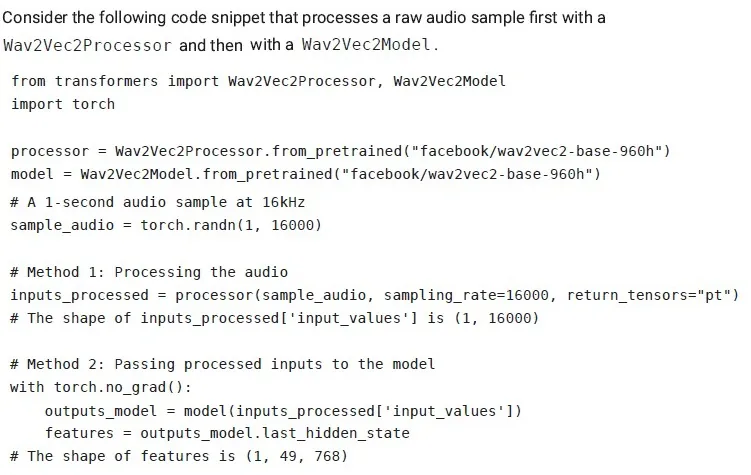
Based on the above data, answer the given subquestions.
Q7MCQ4 Marks·Choose one option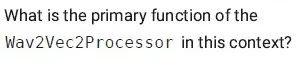
- ATo convert the raw audio waveform into a sequence of contextualized hidden states.
- BTo normalize the raw audio waveform and prepare it in the correct tensor format for the model.
- CTo downsample the audio from its native sampling rate to 16000 Hz.
- DTo tokenize the audio into a sequence of discrete units, similar to a text tokenizer.
- Q8NAT5 Marks·Write the number
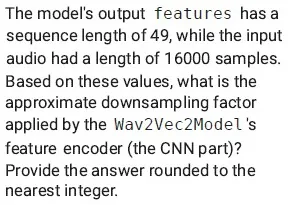 Your answer:
- Q9MSQ5 Marks·Choose all correct options
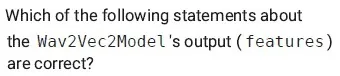
- A
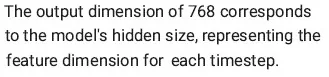
- B
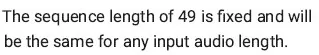
- C
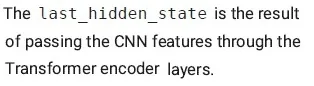
- D
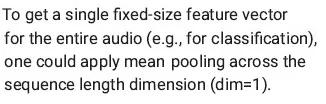
- E
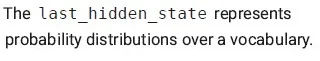
- A
Read the passage below, then answer Q10–Q11
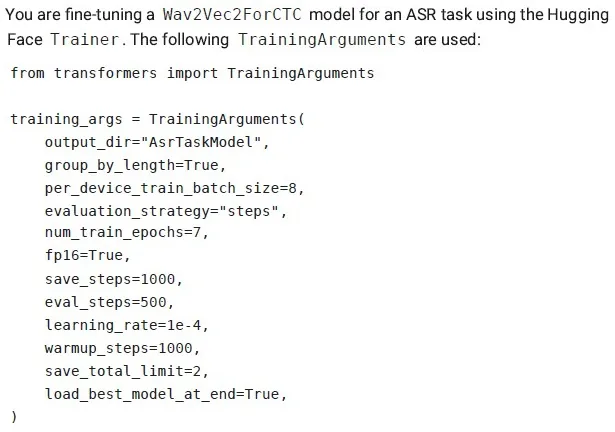
Based on the above data, answer the given subquestions.
Q10MCQ5 Marks·Choose one option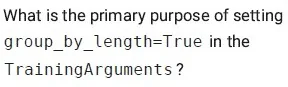
- ATo sort the entire dataset by audio duration before training begins.
- BTo ensure each batch contains audios of exactly the same length, eliminating the need for padding.
- CTo create batches with samples of similar input length, which minimizes the amount of padding required and improves training efficiency.
- DTo group samples by the length of their text transcription rather than their audio length.
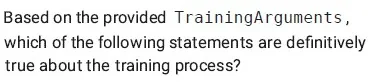
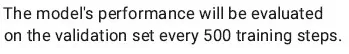
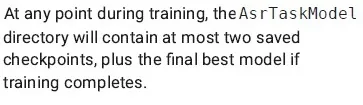
- Q11MSQ5 Marks·Choose all correct options
- A
- B
- C
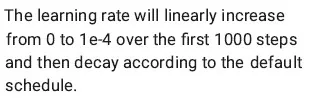
- D
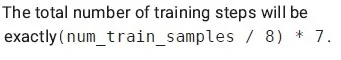
- E
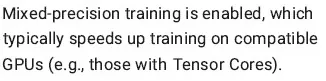
- A