Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Deep Learning for Computer Vision
Neural networks & training
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
Quiz 1 · 26 Oct 2025 (AN)Quiz 1
- Q1MCQ2 Marks·Choose one option

- A0.9829, 4.05, 1, 4.0673, 4.05, 4.05
- B0.8808, 3.50, 1, 3.54, 3.50, 3.50
- C0.7311, 2.00, 1, 2.13, 2.00, 2.00
- D0.5000, 0.00, 0, 0.69, 0.00, 0.00
- Q2MCQ2 Marks·Choose one option
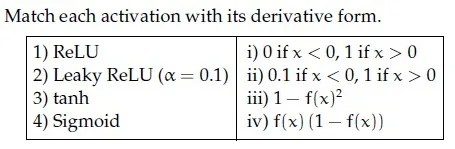
- A1→ii, 2→i, 3→iii, 4→iv
- B1→i, 2→ii, 3→iii, 4→iv
- C1→i, 2→iv, 3→ii, 4→iii
- D1→iv, 2→ii, 3→i, 4→iii
- Q3MCQ2 Marks·Choose one option
Which is True?
- ANesterov momentum looks ahead and often converges faster than classical momentum.
- BA large fixed learning rate always speeds convergence.
- CAdam uses only a first-moment estimate of gradients.
- DNone of these
- Q4MSQ3 Marks·Choose all correct options
Which statements are true? (Select all that apply)
- A
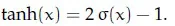
- B
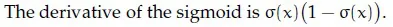
- C
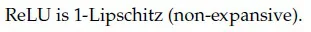
- D
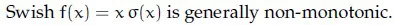
- A
- Q5MSQ3 Marks·Choose all correct options
Which statements are false?
- AMomentum maintains an EMA-like velocity of gradients/updates.
- BRMSProp normalizes step sizes by a running RMS of gradients.
- CIn the Adam optimizer, the hyper-parameters β_1 and β_2 control the exponential decay rates for the moving averages of the gradient and its squared vale. Adam with reduces to SGD with momentum. β_1 = 0 and β_2 = 0 reduces to SGD with momentum.
- DCosine-annealed warm restarts can help escape sharp minima.
- Q6NAT3 Marks·Write the number
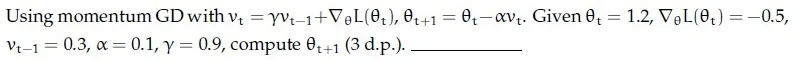 NOTE: Enter your answer in three decimal places.Your answer:
- Q7NAT3 Marks·Write the number
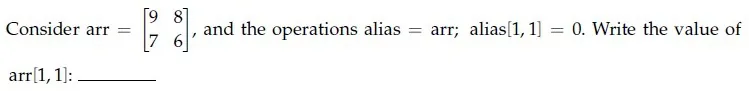 Your answer:
- Q8NAT3 Marks·Write the number
 Your answer:
End Term · 31 Aug 2025 (FN)End Term
- Q9MCQ2 Marks·Choose one option
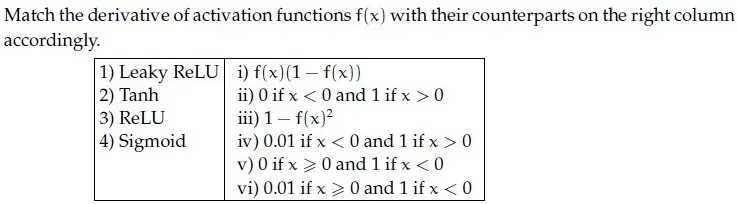
- A1→ vi, 2→ iii, 3 →v, 4 → i
- B1→ i, 2→ iv, 3 → iii, 4→ ii
- C1→ i, 2→ v, 3 → iii, 4→ iv
- D1→ iv, 2→ iii, 3→ ii, 4 → i
- Q10MCQ2 Marks·Choose one option
Which one of the following statements regarding hyperparameter tuning is false?
- AValidation set is the best choice for tuning hyperparameters
- BPicking hyperparameters that perform the best on the training set leads to overfitting
- CTuning hyperparameters on the test set is an acceptable approach to find the most powerful model for generalization performance
- DTest set performance, with hyperparameters tuned on the validation set, would be a realistic measure of how the model will generalize to new data.
- Q11MSQ2 Marks·Choose all correct options
Which one of the following statements is true:
- AWeight change criterion is a method of ‘early stopping’ that checks whether or not the error is dropping over epochs to decide whether to continue training or stop.
- BL1 norm tends to create more sparse weights than L2 norm.
- CDuring the training phase, for each iteration, Dropout ignores a random fraction, p, of nodes, and accounts for it in the test phase by scaling down the activations by a factor of p.
- DA single McCulloch-Pitts neuron is capable of modeling AND, OR, XOR, NOR, and NAND functions.
- Q12MSQ2 Marks·Choose all correct options
Which of the following statements are true? (Select all that apply)
- A
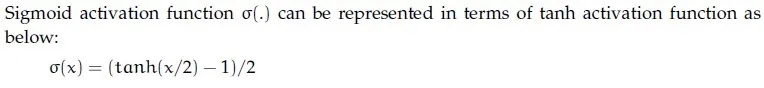
- B
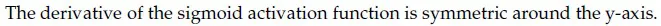
- C
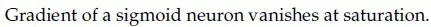
- D
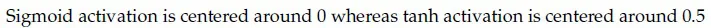
- A
- Q13NAT2 Marks·Write the number
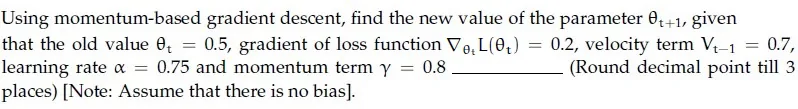 Your answer:
Read the passage below, then answer Q14–Q15
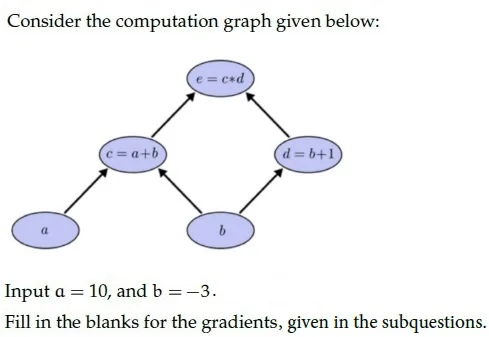 Q14NAT1 Mark·Write the number
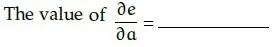 Your answer:
- Q15NAT1 Mark·Write the number
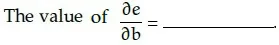 Your answer:
Read the passage below, then answer Q16–Q21
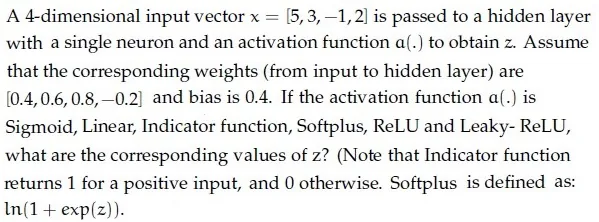
Based on the above data, answer the given subquestions.
Q16NAT1 Mark·Write the numberSigmoid _______________
Your answer:- Q17NAT1 Mark·Write the number
Linear _______________
Your answer: - Q18NAT1 Mark·Write the number
Indicator Function _______________
Your answer: - Q19NAT1 Mark·Write the number
Softplus _______________
Your answer: - Q20NAT1 Mark·Write the number
ReLu _______________
Your answer: - Q21NAT1 Mark·Write the number
Leaky-ReLu _______________
Your answer:
End Term · 31 Aug 2025 (AN)End Term
- Q22MCQ2 Marks·Choose one option
Consider the following Pytorch code: 1. x = torch.tensor([[-3.,2.,3.],[4.,-5.,7.],[20.,3.,2.]]) 2. print(torch.mean(x,dim=0,keepdim=True)) The output of the code is:
- Atensor([ 7., 0., 4.])
- Btensor([[ -7., 10., -4.]])
- Ctensor([[ -7.],[7.],[4.]])
- Dtensor([ -7., 7., 3.])
- Etensor([[7., 0., 4.]])
- Ftensor([[ 0.],[7.],[4.]])
- Q23MCQ2 Marks·Choose one option
Which one of the following statements regarding hyperparameter tuning is false?
- AValidation set is the best choice for tuning hyperparameters
- BPicking hyperparameters that perform the best on the training set leads to overfitting
- CTuning hyperparameters on the test set is an acceptable approach to find the most powerful model for generalization performance
- DTest set performance, with hyperparameters tuned on the validation set, would be a realistic measure of how the model will generalize to new data.
- Q24MSQ2 Marks·Choose all correct options
Which one of the following statements is true:
- AWeight change criterion is a method of ‘early stopping’ that checks whether or not the error is dropping over epochs to decide whether to continue training or stop.
- BL1 norm tends to create more sparse weights than L2 norm.
- CDuring the training phase, for each iteration, Dropout ignores a random fraction, p, of nodes, and accounts for it in the test phase by scaling down the activations by a factor of p.
- DA single McCulloch-Pitts neuron is capable of modeling AND, OR, XOR, NOR, and NAND functions.
- Q25NAT2 Marks·Write the number
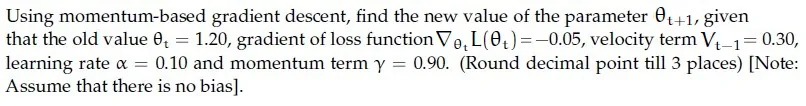 Your answer:
Read the passage below, then answer Q26–Q27
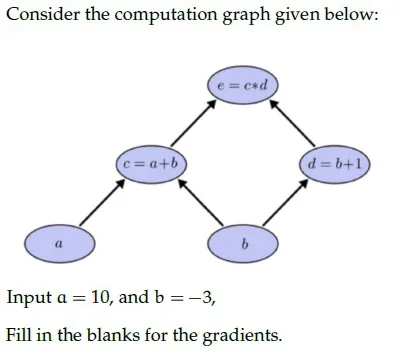
Based on the above data, answer the given subquestions.
Q26NAT1 Mark·Write the number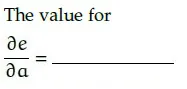 Your answer:
- Q27NAT1 Mark·Write the number
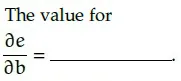 Your answer:
Read the passage below, then answer Q28–Q33
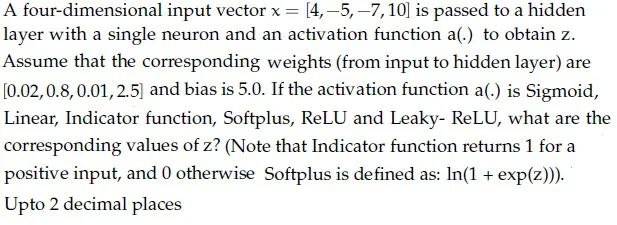
Based on the above data, answer the given subquestions.
Q28NAT1 Mark·Write the numberSigmoid ______________
Your answer:- Q29NAT1 Mark·Write the number
Linear ______________
Your answer: - Q30NAT1 Mark·Write the number
Indicator Function ______________
Your answer: - Q31NAT1 Mark·Write the number
Softplus _____________
Your answer: - Q32NAT1 Mark·Write the number
ReLU _______________
Your answer: - Q33NAT1 Mark·Write the number
Leaky-ReLU _____________
Your answer:
Official KeyMaster Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.
Reveal KeyCollapse Key
Master Answer Key & Explanations
Official answer keys from IIT Madras BS past papers. Click any question to review.