Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Reinforcement Learning
Policy evaluation, PI & VI
Official Paper
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ5 Marks·Choose one option
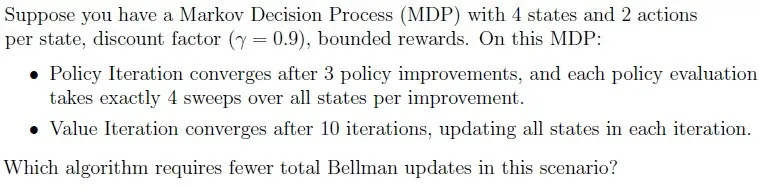
- APolicy Iteration
- BValue Iteration
- CBoth require equal updates
- DIt cannot be determined
- Q2MSQ5 Marks·Choose all correct options
Which of the following statements correctly describes the differences in computational complexity and convergence behaviour between Policy Iteration and Value Iteration algorithms in solving Markov Decision Processes?
- AValue Iteration requires fewer iterations to converge, but each iteration is computationally more expensive due to the policy evaluation step.
- BValue Iteration performs a combined update of value estimation and policy improvement in one step and requires more iterations to converge compared to Policy Iteration.
- CPolicy Iteration can only be applied to small state spaces, while Value Iteration scales well to large state spaces.
- DValue Iteration is simpler to implement because it only maintains a value function, while Policy Iteration maintains both policy and value function.
- EBoth Policy Iteration and Value Iteration are guaranteed to converge to the optimal policy.
- Q3NAT5 Marks·Write the number
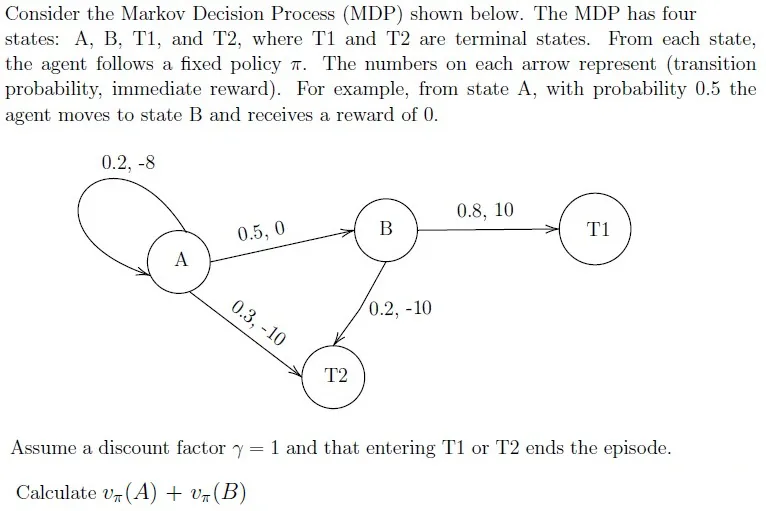 Your answer:
- Q4NAT4 Marks·Write the number
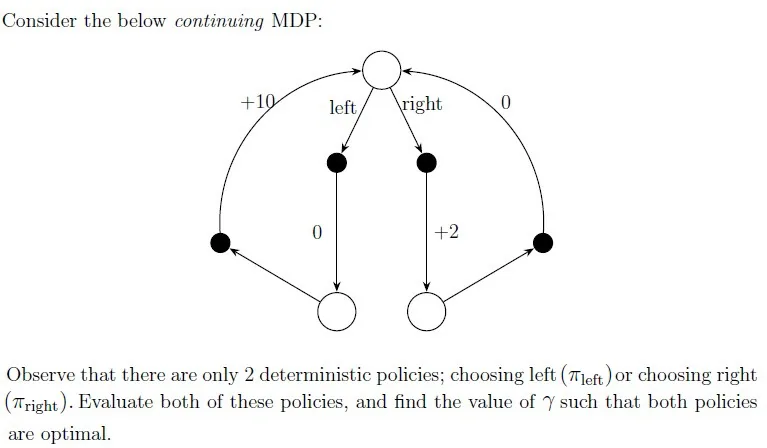 Your answer: