Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Mathematical Foundations of Generative AI
Most repeated questions
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
Type 1 · asked 3 times · VAEs & reparameterisation
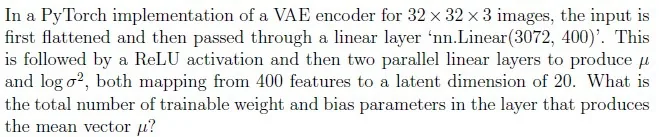
Count trainable parameters of fully connected generator/encoder layers
- Q1NAT3 Marks·Write the numberQuiz 2 · 3 Aug 2025 (AN)Key ↓
 Your answer:
- Q2MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
Given d_z=20, if the first decoder layer is a fully connected layer that outputs 3 x 64 x 64 units and includes a bias term, how many trainable parameters does this layer have?
- A245,760
- B258,048
- C122,880
- D262,144
- Q3MCQ2 Marks·Choose one optionQuiz 1 · 26 Oct 2025 (AN)Key ↓
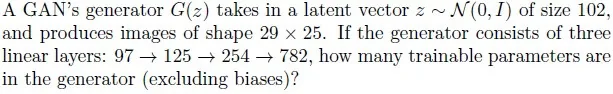
- A80,402
- B99,402
- C242,503
- D159,3
Type 2 · asked 2 times · VAEs & reparameterisation
Compute the latent z with the reparameterisation trick
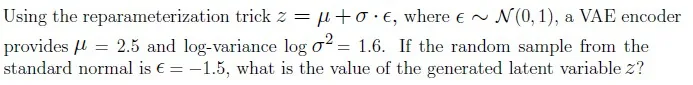
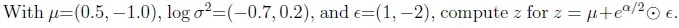
Type 3 · asked 2 times · DDPM: forward & reverse process
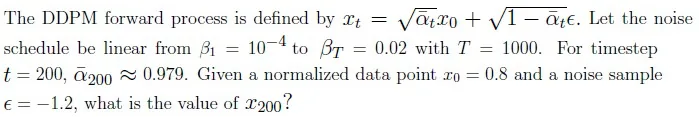
Compute the noised sample x_t in the DDPM forward process
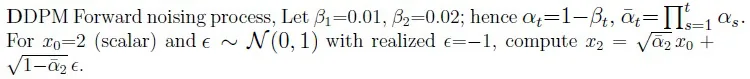
Type 4 · asked 2 times · GAN objective & training
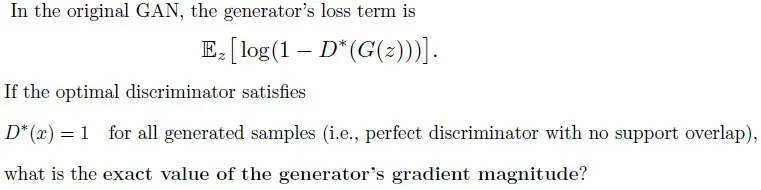
Find the GAN generator gradient when supports are disjoint
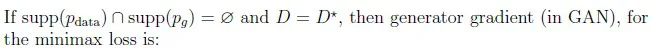
Type 5 · asked 2 times · GAN objective & training
Compute the output spatial size of (transposed) conv layers
- Q10MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (AN)Key ↓
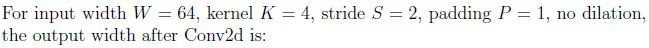
- A31
- B32
- C33
- D34
- Q11MCQ4 Marks·Choose one optionEnd Term · 31 Aug 2025 (FN)Key ↓
Starting from 4×4 spatial size, apply four ConvTranspose2d blocks each with kernel 4, stride 2, padding 1. Final spatial size is:
- A16 × 16
- B32 × 32
- C64 × 64
- D128 × 128
Type 6 · asked 2 times · DDPM: forward & reverse process
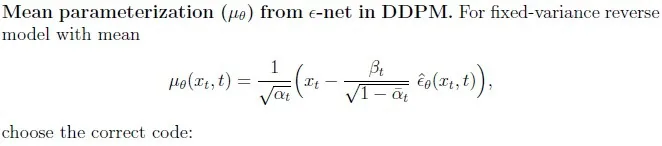
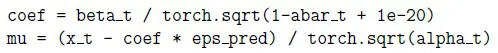
Pick the PyTorch code for the DDPM mean from predicted noise
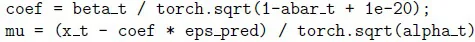

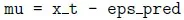
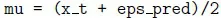


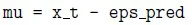
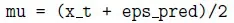
Type 7 · asked 2 times · Transformers, attention & decoding
Renormalise token probabilities after top-p/top-k filtering
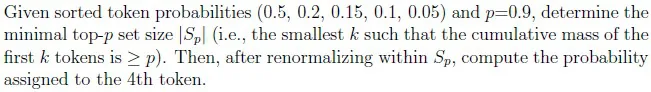

Type 8 · asked 2 times · Transformers, attention & decoding
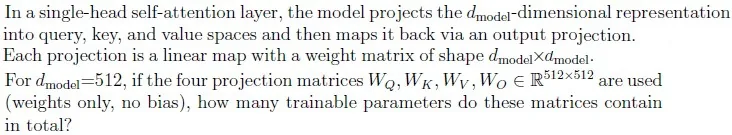
Count projection matrix parameters in self-attention
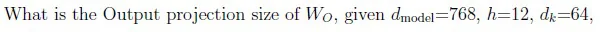
Type 9 · asked 2 times · RL for LMs: policy gradient & PPO
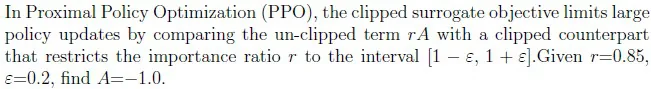
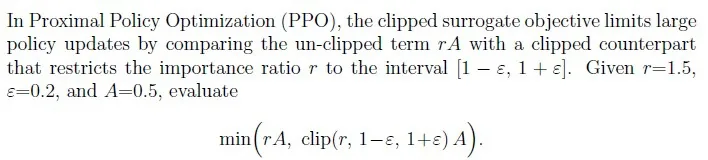
Evaluate the PPO clipped surrogate objective
Type 10 · asked 2 times · BiGAN, domain adaptation & FID