Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Introduction to Natural Language Processing
Sequence models & decoding
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ4 Marks·Choose one option
How does an LSTM differ from a standard RNN in terms of remembering information?
- AIt uses a larger hidden state.
- BIt stores all past hidden states explicitly.
- CIt introduces gates to control the flow of information.
- DIt completely replaces hidden states with attention mechanisms.
- Q2MCQ5 Marks·Choose one option
In the context of speculative decoding, a draft model predicts three tokens: "a", "quick", "fox". The main model assigns probabilities 0.8, 0.6, and 0.8 respectively.The draft model's probabilities for these words were 0.7, 0.9, and 0.9. Which tokens are most likely to be accepted?
- AAll three tokens
- BOnly "a" and "fox"
- COnly "a"
- DNone of the tokens
- Q3MSQ4 Marks·Choose all correct options
During sequence-to-sequence model training, which of the following statements is/are correct regarding Teacher Forcing and Student Forcing?
- ATeacher Forcing is used during inference, while Student Forcing is used during training.
- BTeacher Forcing provides the correct previous output as input during training, whereas Student Forcing generates outputs based on its own previous predictions.
- CStudent Forcing helps the model converge faster than Teacher Forcing.
- DTeacher Forcing is mainly used in reinforcement learning settings.
- Q4MSQ4 Marks·Choose all correct options
Which of the following statements about beam search is/are incorrect ?
- ABeam search balances exploration and exploitation by considering multiple sequences at each step.
- BA larger beam width increases computational cost but improves search quality.
- CGreedy search is equivalent to beam search with beam size B = 1.
- DUnlike greedy search, beam search guarantees finding the globally optimal sequence.
- Q5MSQ5 Marks·Choose all correct options
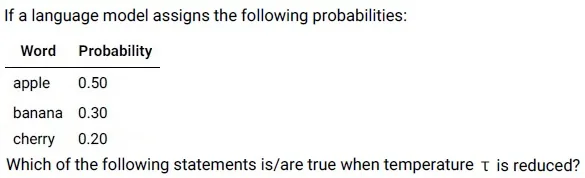
- AThe probability of "apple" increases further.
- BThe probabilities of "banana" and "cherry" become closer to "apple".
- CThe probabilities remain unchanged.
- DThe model always picks "banana".
- EThe model always picks "cherry".
- Q6NAT4 Marks·Write the number
A beam search with beam width = 4 and vocabulary size = 8 is run for 3 decoding steps. How many sequences will remain at the end of 3 steps after pruning?
Your answer: