Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Introduction to Natural Language Processing
Model interpretability
Official Paper
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
Which of the following statements about Attention Flow in Transformer models is TRUE?
- AAttention flow computes the contribution of each token independently without considering other tokens.
- BAttention flow assigns higher scores to tokens that appear earlier in the sequence by default.
- CAttention flow combines attention scores across multiple layers to determine overall token influence.
- DAttention flow values are always normalized across all tokens in the sequence to sum to 1.
- Q2MCQ5 Marks·Choose one option
Consider the following attention matrices for two layers (corresponding to tokens 1 and 2) in a transformer model: Layer 1 Attention Matrix:
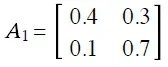 Layer 2 Attention Matrix:
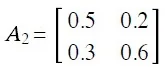 What is the total attention from token 2 to token 1 after performing attention rollout?
- A0.57
- B0.33
- C0.39
- D0.26
- Q3NAT4 Marks·Write the number
Consider the following regression model: F(x) = 500 * Age + 1000 * Income + 20000 For an input with: Age = 30 Income = 50 Baseline Input: Age = 0 Income = 0 What is the Integrated Gradient for the feature Income?
Your answer: - Q4NAT6 Marks·Write the number
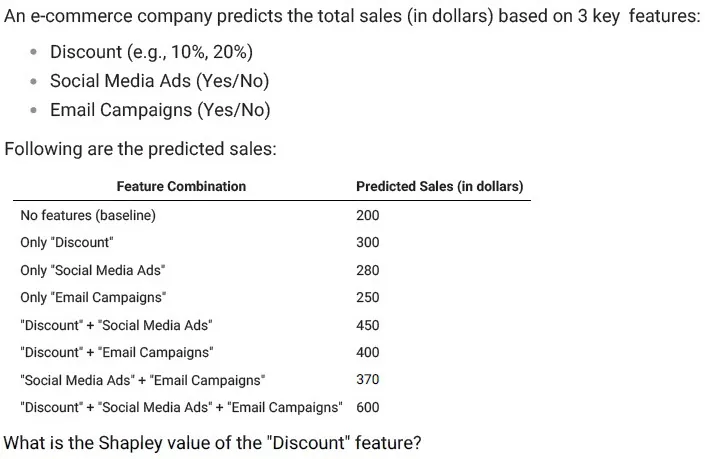 Your answer: