Indian Institute of Technology Madras
BS Degree Programme · Examination & Study Paper
Introduction to Natural Language Processing
End Term · 13 Apr 2025 (Afternoon)
Examination Instructions & Guidelines
- Solve on notebook/paper first before checking solutions.
- MCQ: Exactly 1 option is correct. Negative marking applies.
- MSQ: One or more options correct. Select all to score.
- NAT: Numerical response. No negative marking.
- Scientific calculator allowed for all calculations.
- Official answer key is sealed at the end of this sheet.
- Q1MCQ3 Marks·Choose one option
Why might accuracy be a misleading metric for evaluating POS tagging systems in cases of class imbalance?
- ABecause accuracy does not account for the number of true negatives.
- BBecause accuracy gives equal weight to all classes, even if some tags are much rarer than others.
- CBecause accuracy only measures the precision of the system, ignoring recall.
- DBecause accuracy is not affected by the number of false positives and false negatives.
- Q2MCQ3 Marks·Choose one option
In stochastic POS tagging, why is it necessary to calculate both individual word probabilities and tag sequence probabilities?
- AIndividual word probabilities are sufficient for accurate tagging, and tag sequence probabilities are redundant.
- BIndividual word probabilities are only used for rare words, while tag sequence probabilities are used for common words.
- CTag sequence probabilities help in determining the most likely sequence of tags, while individual word probabilities provide local context.
- DBoth probabilities are used to reduce the computational complexity of the tagging process.
- Q3MCQ3 Marks·Choose one option
How does Retrieval-Augmented Generation (RAG) differ from standard parametric models like GPT-3?
- ARAG eliminates the need for transformer-based token generation.
- BRAG uses retrieval but does not update its knowledge dynamically over time.
- CRAG only works when trained on labeled question-answer datasets.
- DRAG retrieves external documents dynamically, reducing reliance on pre- trained knowledge.
- Q4MCQ3 Marks·Choose one option
Which of the following architectures is most commonly used as the generator in RAG models?
- AGPT-3
- BBART
- CBERT
- DRoBERTa
- Q5MCQ3 Marks·Choose one option
A company wants to optimize an LLM for programming tasks. Which approach is the most efficient if they have limited labeled data?
- ATrain a new model from scratch using a large programming dataset.
- BFine-tune a transformer model with instruction tuning.
- CUse Few-shot prompting with an existing LLM.
- DApply a BERT-based model instead of transformers.
- Q6MCQ3 Marks·Choose one option
Which of the following statements about Attention Flow in Transformer models is TRUE?
- AAttention flow computes the contribution of each token independently without considering other tokens.
- BAttention flow assigns higher scores to tokens that appear earlier in the sequence by default.
- CAttention flow combines attention scores across multiple layers to determine overall token influence.
- DAttention flow values are always normalized across all tokens in the sequence to sum to 1.
- Q7MCQ3 Marks·Choose one option
Which of the following scenarios represents an ethical concern with LLM deployment?
- AA summarization model shortening news articles while maintaining factual accuracy.
- BA question-answering system providing different answers for different demographics when asked about salary negotiations.
- CA chatbot refusing to generate offensive or harmful content.
- DA translation model translating medical terms with higher accuracy than general terms.
- Q8MCQ4 Marks·Choose one option
How does an LSTM differ from a standard RNN in terms of remembering information?
- AIt uses a larger hidden state.
- BIt stores all past hidden states explicitly.
- CIt introduces gates to control the flow of information.
- DIt completely replaces hidden states with attention mechanisms.
- Q9MCQ5 Marks·Choose one option
In the context of speculative decoding, a draft model predicts three tokens: "a", "quick", "fox". The main model assigns probabilities 0.8, 0.6, and 0.8 respectively.The draft model's probabilities for these words were 0.7, 0.9, and 0.9. Which tokens are most likely to be accepted?
- AAll three tokens
- BOnly "a" and "fox"
- COnly "a"
- DNone of the tokens
- Q10MCQ5 Marks·Choose one option
Consider the following attention matrices for two layers (corresponding to tokens 1 and 2) in a transformer model: Layer 1 Attention Matrix:
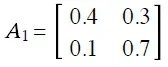 Layer 2 Attention Matrix:
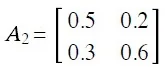 What is the total attention from token 2 to token 1 after performing attention rollout?
- A0.57
- B0.33
- C0.39
- D0.26
- Q11MSQ6 Marks·Choose all correct options
Which of the following sentences contain pragmatic ambiguity due to potential sarcasm or irony?
- A"Wow, another Monday! Just what I needed."
- B"The meeting was only three hours long. So productive!"
- C"I love spending hours in traffic. It’s my favorite part of the day."
- D"The weather is perfect for a picnic today."
- E"She always arrives on time, unlike some people."
- Q12MSQ4 Marks·Choose all correct options
Which of the following statements correctly describe how BERT differs from GPT and standard transformer models?
- ABERT is a bidirectional model, while GPT is autoregressive.
- BBERT uses masked language modeling (MLM), while GPT uses causal language modeling (CLM).
- CStandard transformers use encoder-only architectures, whereas BERT and GPT both use decoder-only architectures.
- DBERT is trained for sentence embeddings, while GPT is trained for next-token prediction.
- Q13MSQ4 Marks·Choose all correct options
Which of the following statements is/are incorrect regarding Reinforcement Learning from Human Feedback (RLHF), Supervised Instruction Fine-Tuning, LoRA, and QLoRA?
- ARLHF helps improve model behavior by learning from human preference rankings.
- BLoRA (Low-Rank Adaptation) reduces the number of trainable parameters by using low-rank matrices.
- CSupervised Instruction Fine-Tuning involves reinforcement learning for generating human-like responses.
- DQLoRA applies quantization to reduce memory consumption during fine- tuning.
- Q14MSQ4 Marks·Choose all correct options
During sequence-to-sequence model training, which of the following statements is/are correct regarding Teacher Forcing and Student Forcing?
- ATeacher Forcing is used during inference, while Student Forcing is used during training.
- BTeacher Forcing provides the correct previous output as input during training, whereas Student Forcing generates outputs based on its own previous predictions.
- CStudent Forcing helps the model converge faster than Teacher Forcing.
- DTeacher Forcing is mainly used in reinforcement learning settings.
- Q15MSQ4 Marks·Choose all correct options
Which of the following statements about beam search is/are incorrect ?
- ABeam search balances exploration and exploitation by considering multiple sequences at each step.
- BA larger beam width increases computational cost but improves search quality.
- CGreedy search is equivalent to beam search with beam size B = 1.
- DUnlike greedy search, beam search guarantees finding the globally optimal sequence.
- Q16MSQ4 Marks·Choose all correct options
Which components are essential in a RAG pipeline?
- Aretriever model (e.g., DPR) that fetches relevant documents.
- Bdecoder-only transformer for sequence generation.
- CBM25-based sparse retrieval method as the primary retriever.
- DBERT-based query encoder for document ranking.
- Q17MSQ4 Marks·Choose all correct options
Which of the following are the examples of unintended bias in an NLP model?
- AA sentiment analysis model rating all political tweets as "negative".
- BA chatbot trained specifically for medical consultations failing on legal queries.
- CA text summarization model producing longer summaries for academic papers.
- DA machine translation system translating "doctor" to "he" and "nurse" to "she" in a gender-neutral language.
- Q18MSQ4 Marks·Choose all correct options
Which of the following factors contribute to bias amplification in NLP models?
- AReinforcement learning from biased human feedback.
- BTraining on unbalanced datasets where stereotypes exist.
- CApplying debiasing techniques such as zeroing out gender-related word embeddings.
- DUsing a larger model size to improve performance.
- Q19MSQ5 Marks·Choose all correct options
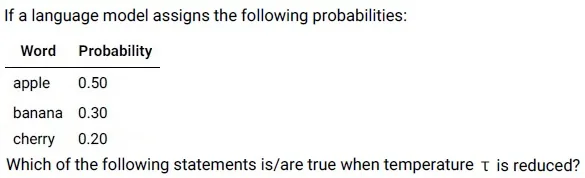
- AThe probability of "apple" increases further.
- BThe probabilities of "banana" and "cherry" become closer to "apple".
- CThe probabilities remain unchanged.
- DThe model always picks "banana".
- EThe model always picks "cherry".
- Q20NAT4 Marks·Write the number
In a transition-based parser using SHIFT, LEFTARC, and RIGHTARC operations, what is the minimum number of operations needed to parse the sentence "I love coding" (excluding the ROOT node)?
Your answer: - Q21NAT4 Marks·Write the number
A TF-IDF model is applied to a document corpus of 50,000 documents. The term "optimization" appears in 750 documents. In a specific document, "optimization" appears 8 times, and the total number of words in that document is 1200. Using log base 10 ( log_(10)), compute the TF-IDF score for "optimization" in this document. Enter your answer correct to three decimal places.
Your answer: - Q22NAT4 Marks·Write the number
A beam search with beam width = 4 and vocabulary size = 8 is run for 3 decoding steps. How many sequences will remain at the end of 3 steps after pruning?
Your answer: - Q23NAT4 Marks·Write the number
A transformer-based Retrieval-Augmented Generation (RAG) system retrieves the top-10 most relevant passages, where each passage contains 512 tokens. However, a portion of the model's 4096-token context length is reserved for the input query and special tokens (e.g., separators, instructions). If the model reserves 1024 tokens for the input query, how many full retrieved passages can fit within the remaining context window?
Your answer: - Q24NAT4 Marks·Write the number
Consider the following regression model: F(x) = 500 * Age + 1000 * Income + 20000 For an input with: Age = 30 Income = 50 Baseline Input: Age = 0 Income = 0 What is the Integrated Gradient for the feature Income?
Your answer: - Q25NAT6 Marks·Write the number
 Your answer: